
AI-Ready Data standard explained
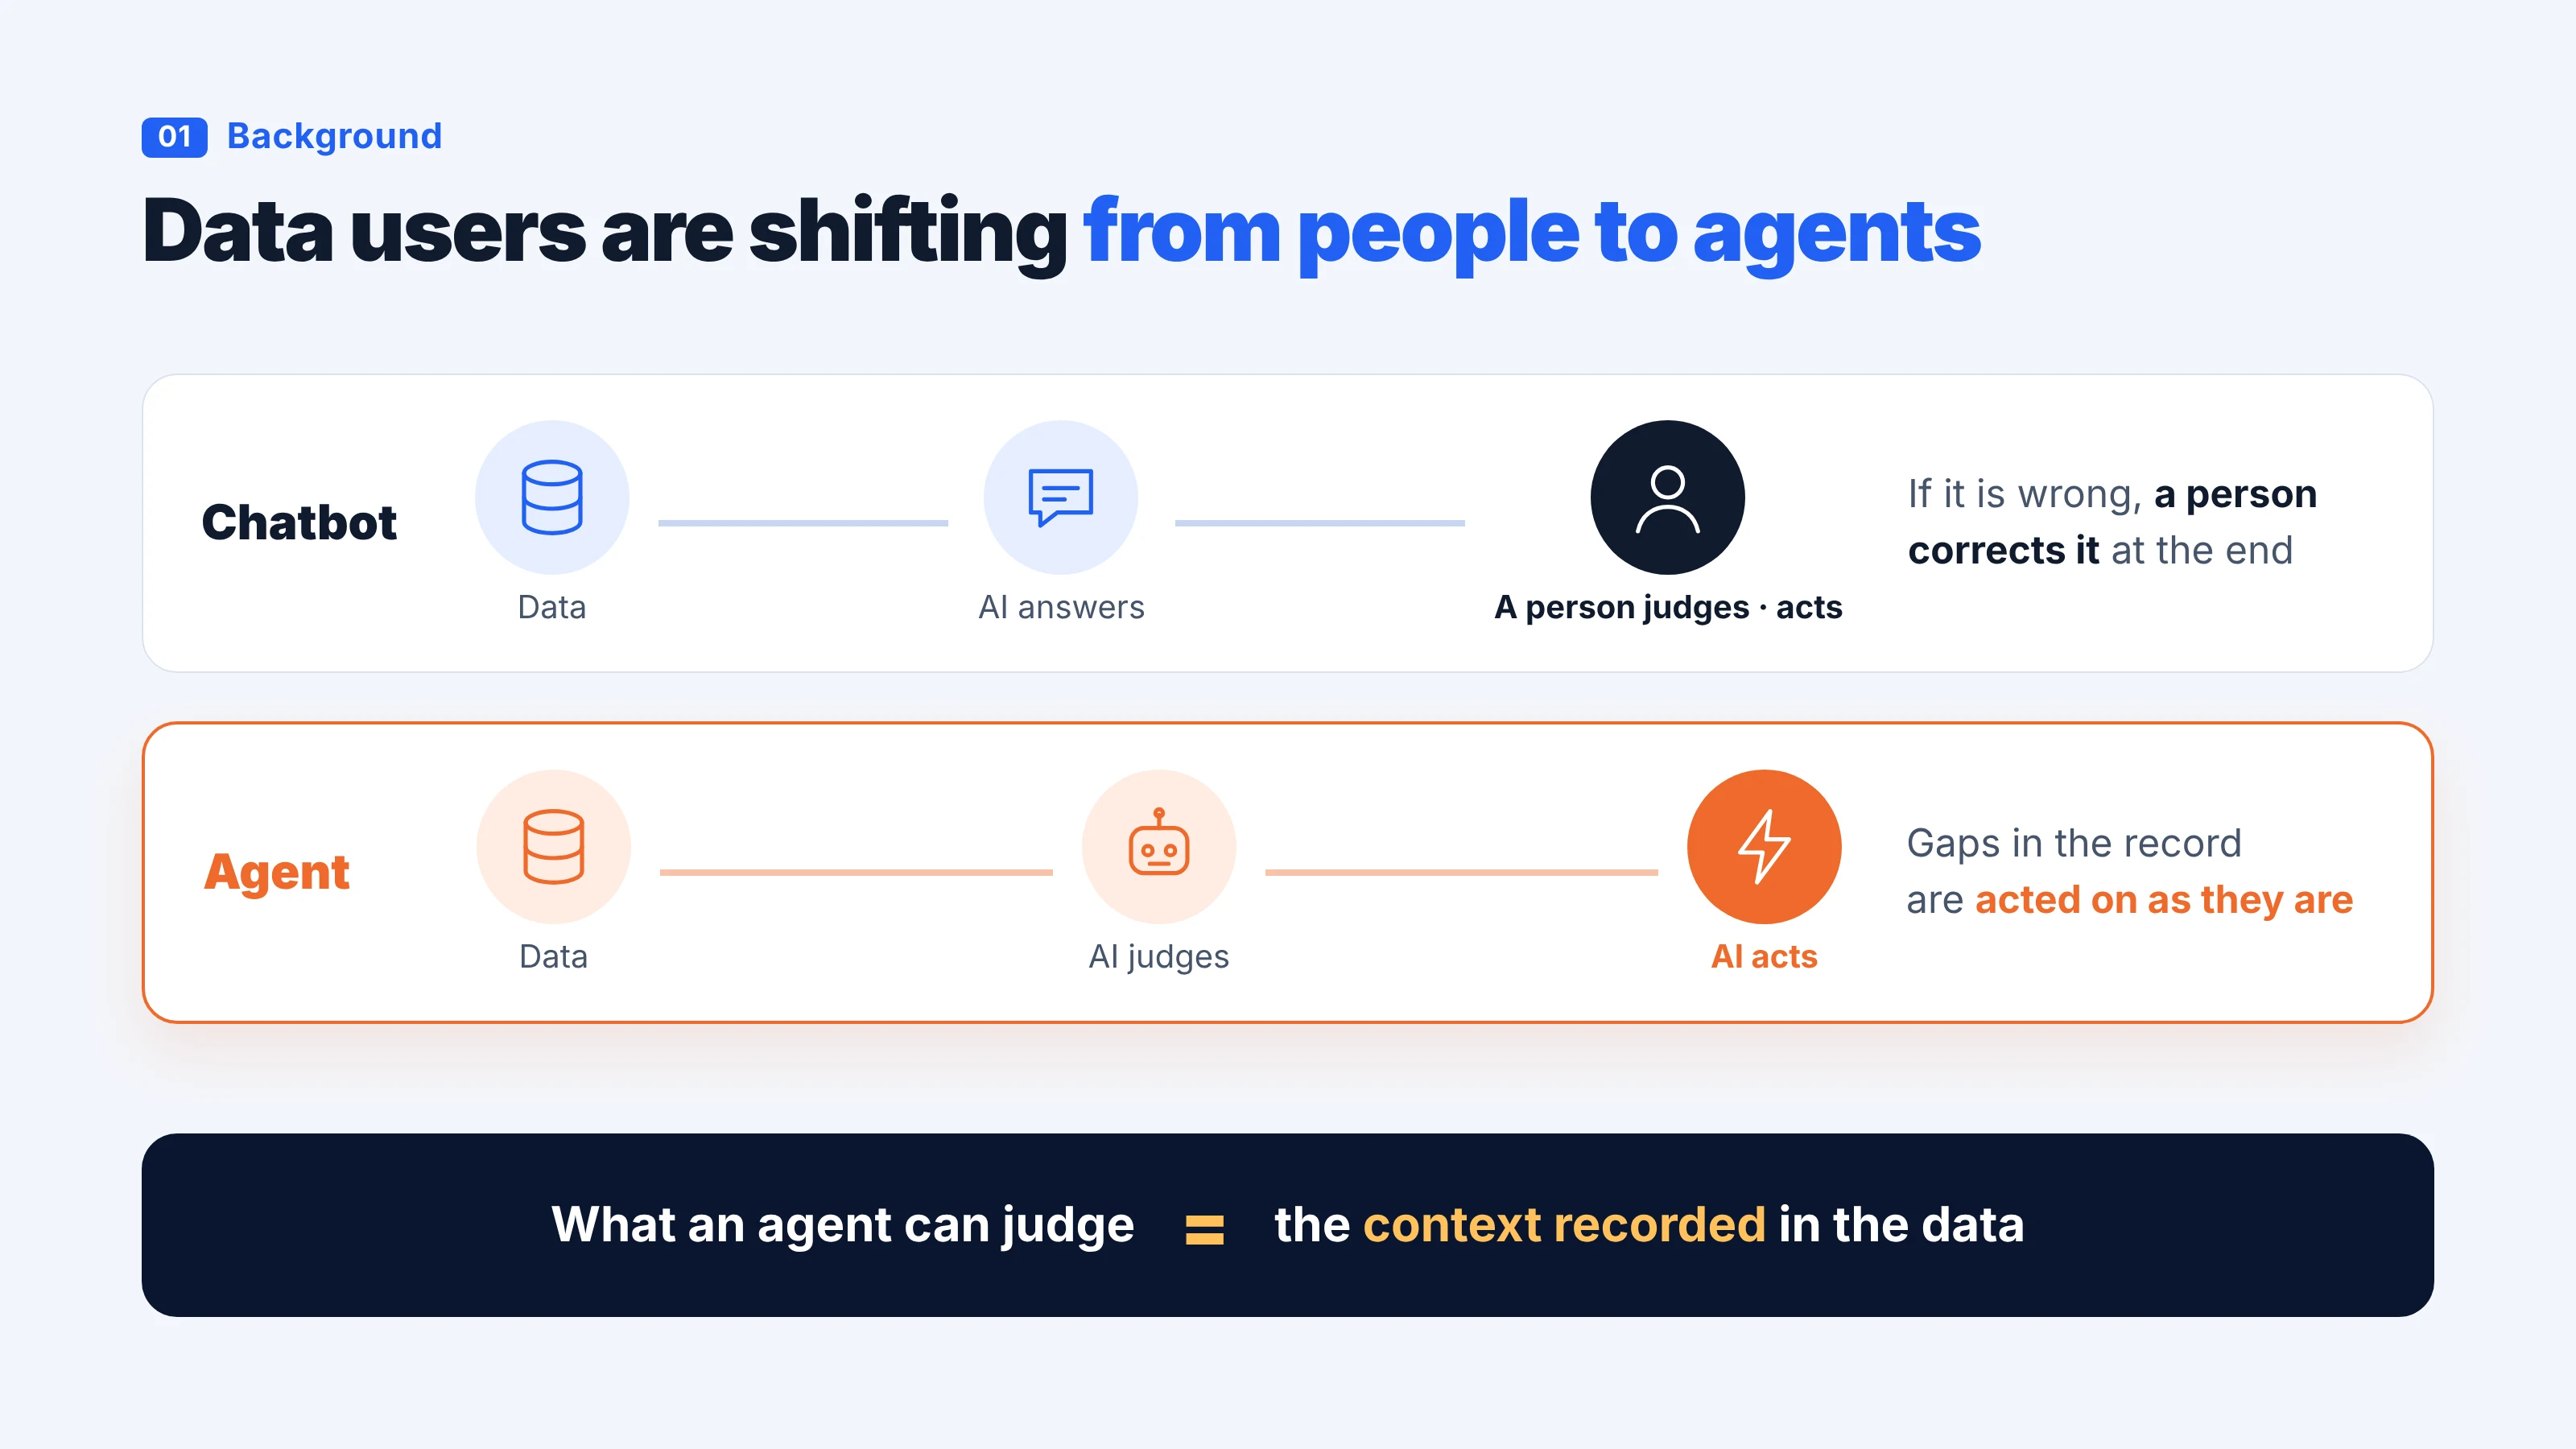
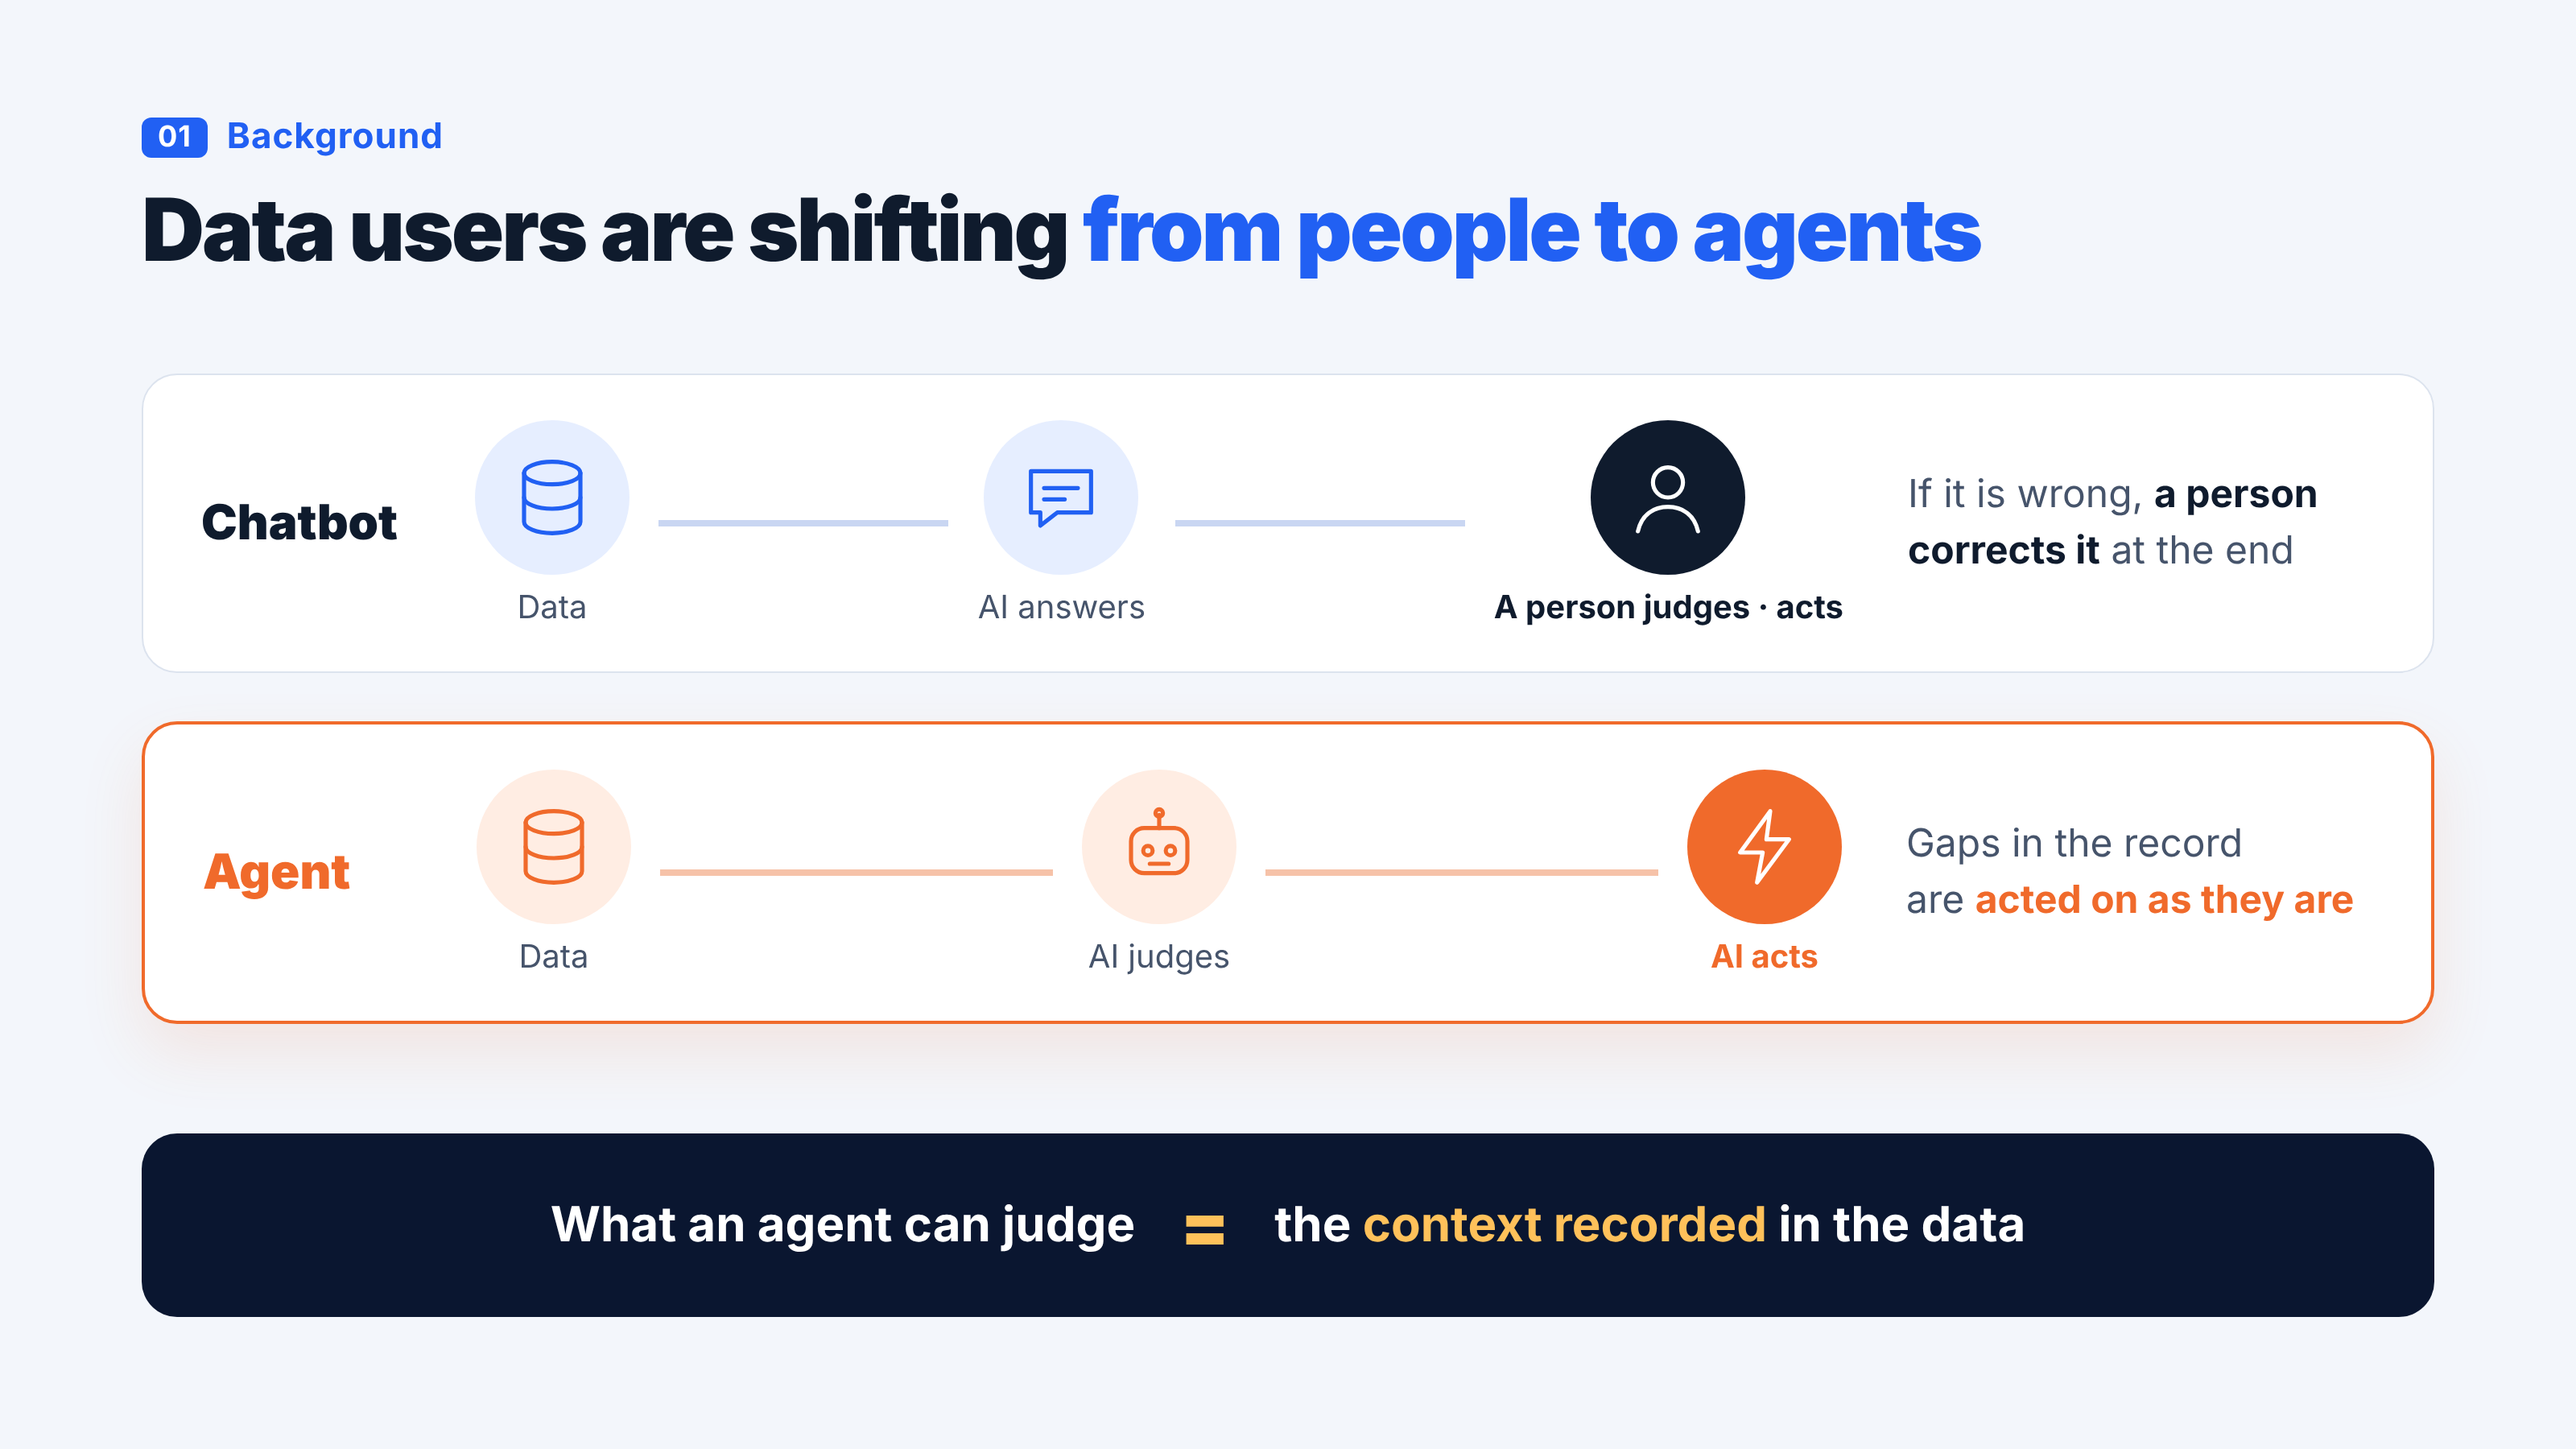
The users of data are expanding from people to AI. AI cannot verify facts that are not recorded.
So that agents use data
without guessing
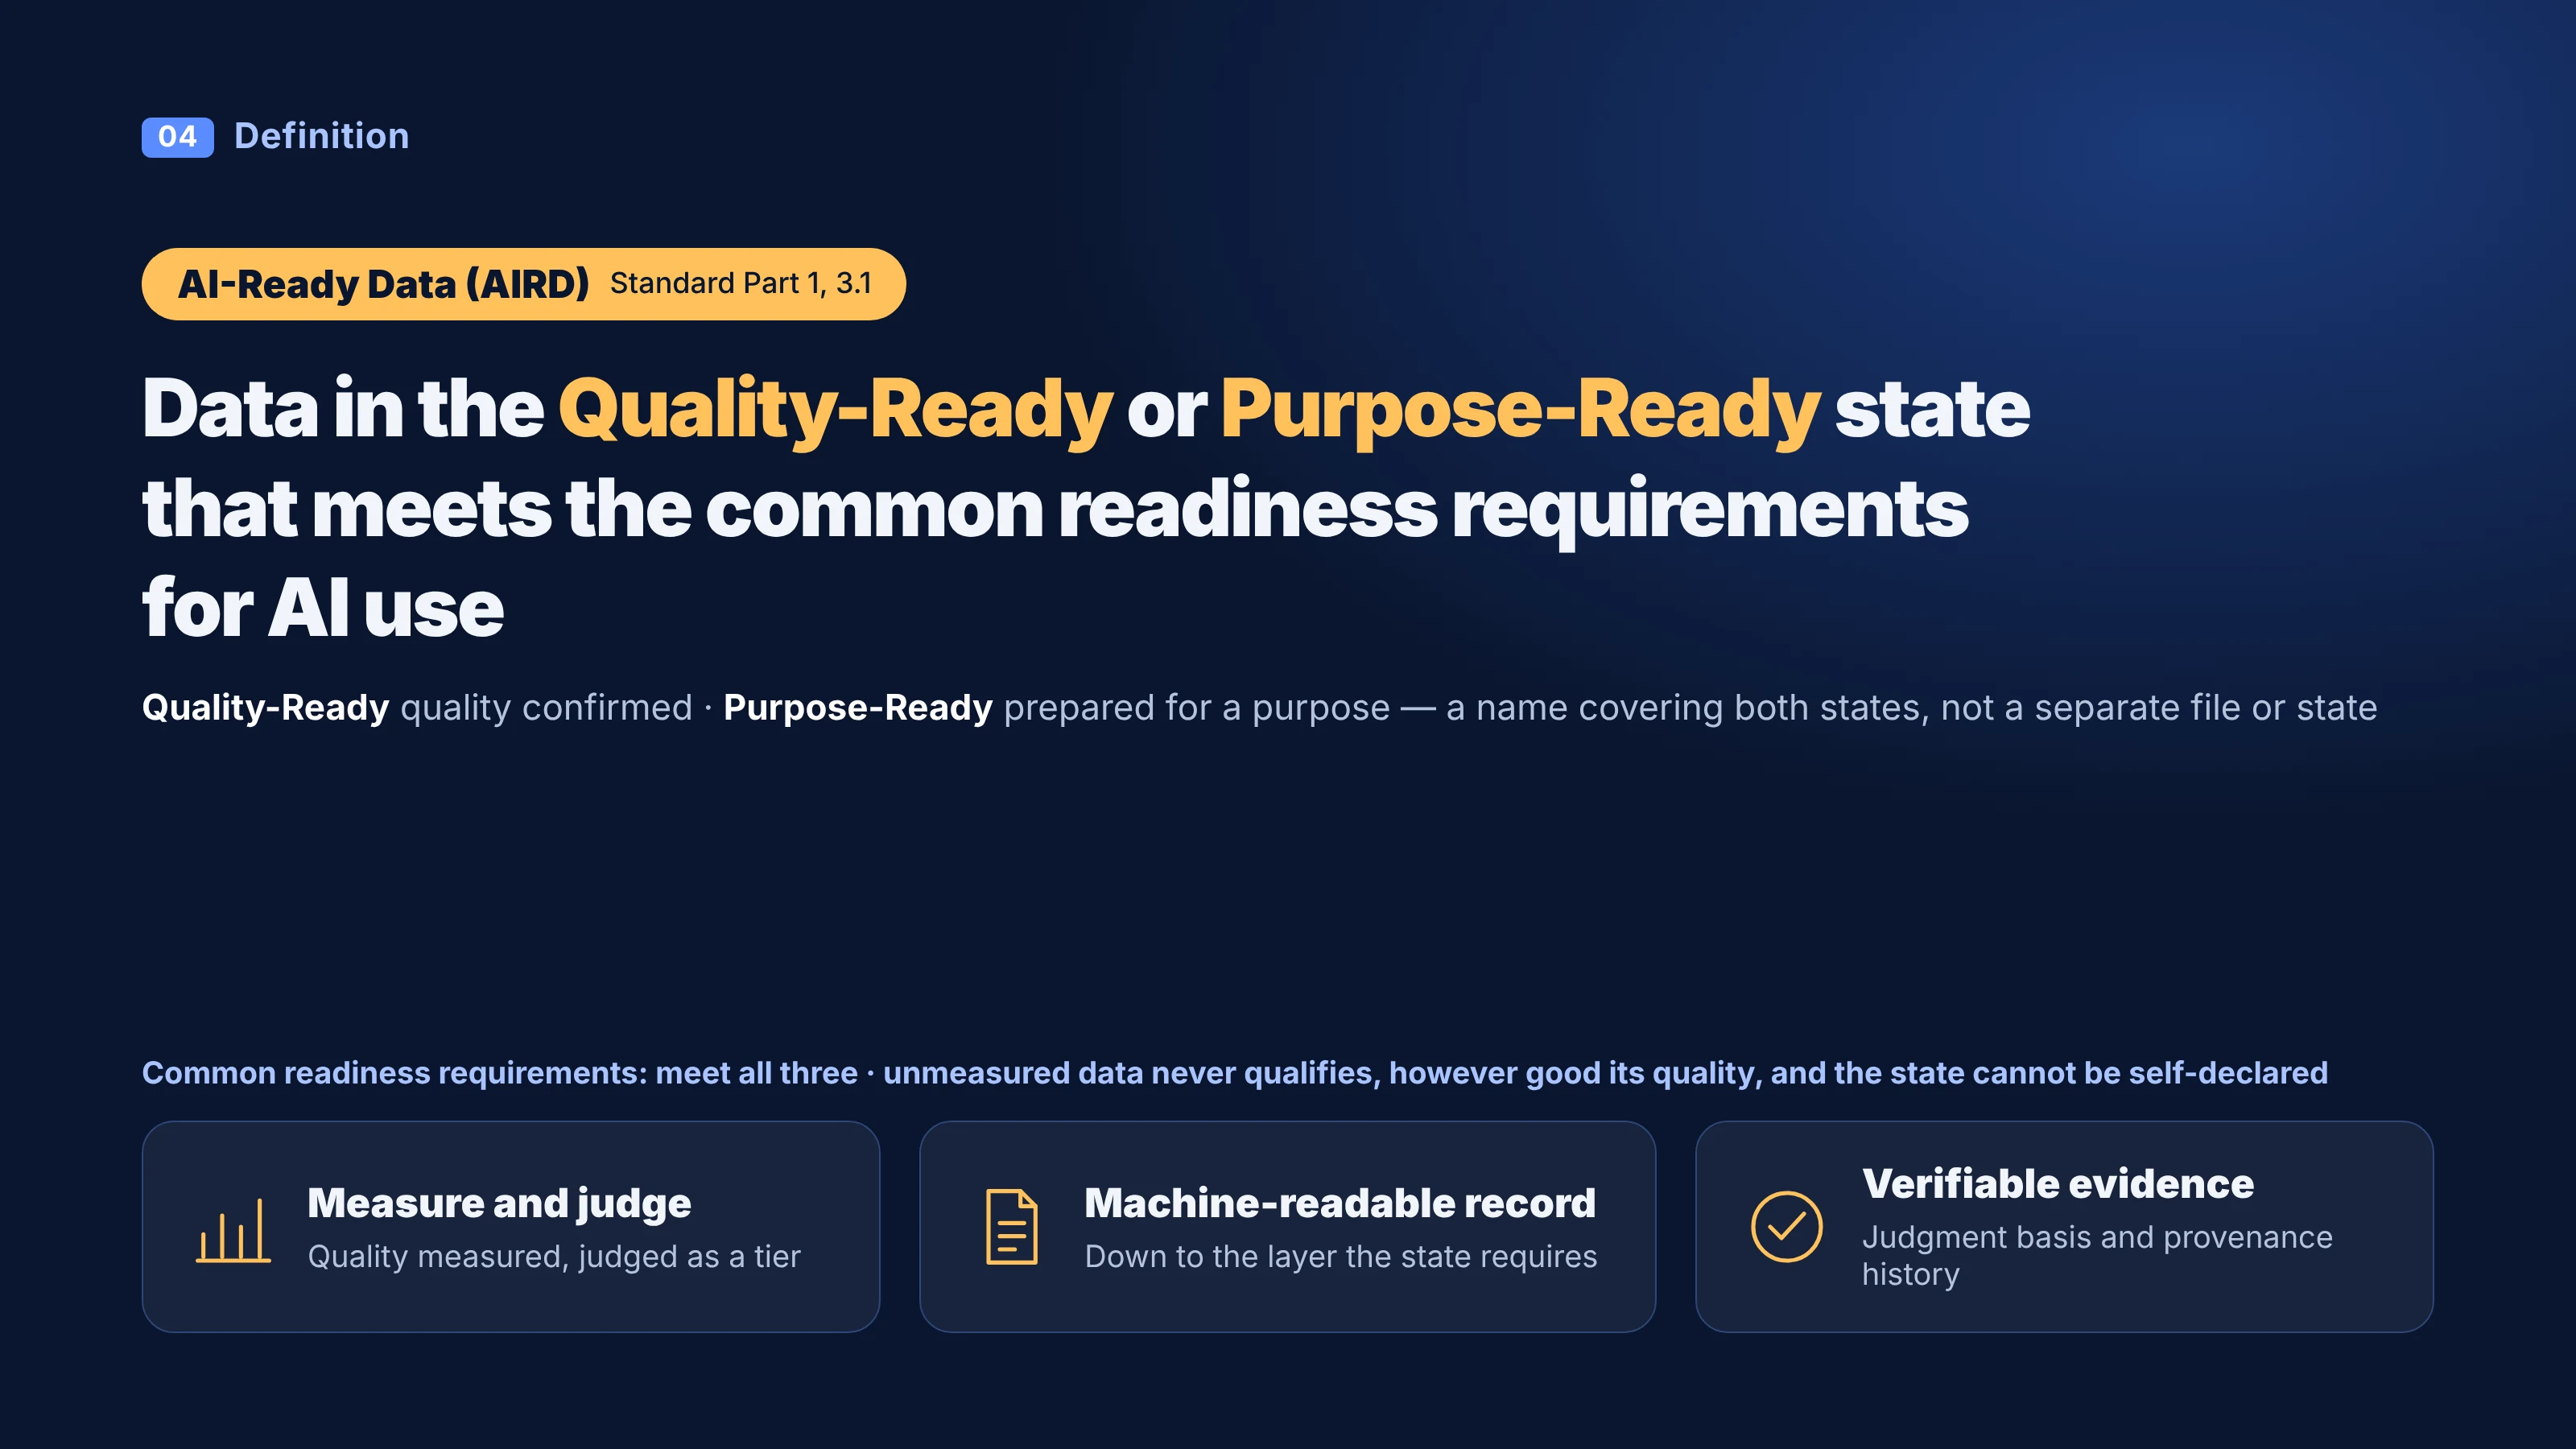
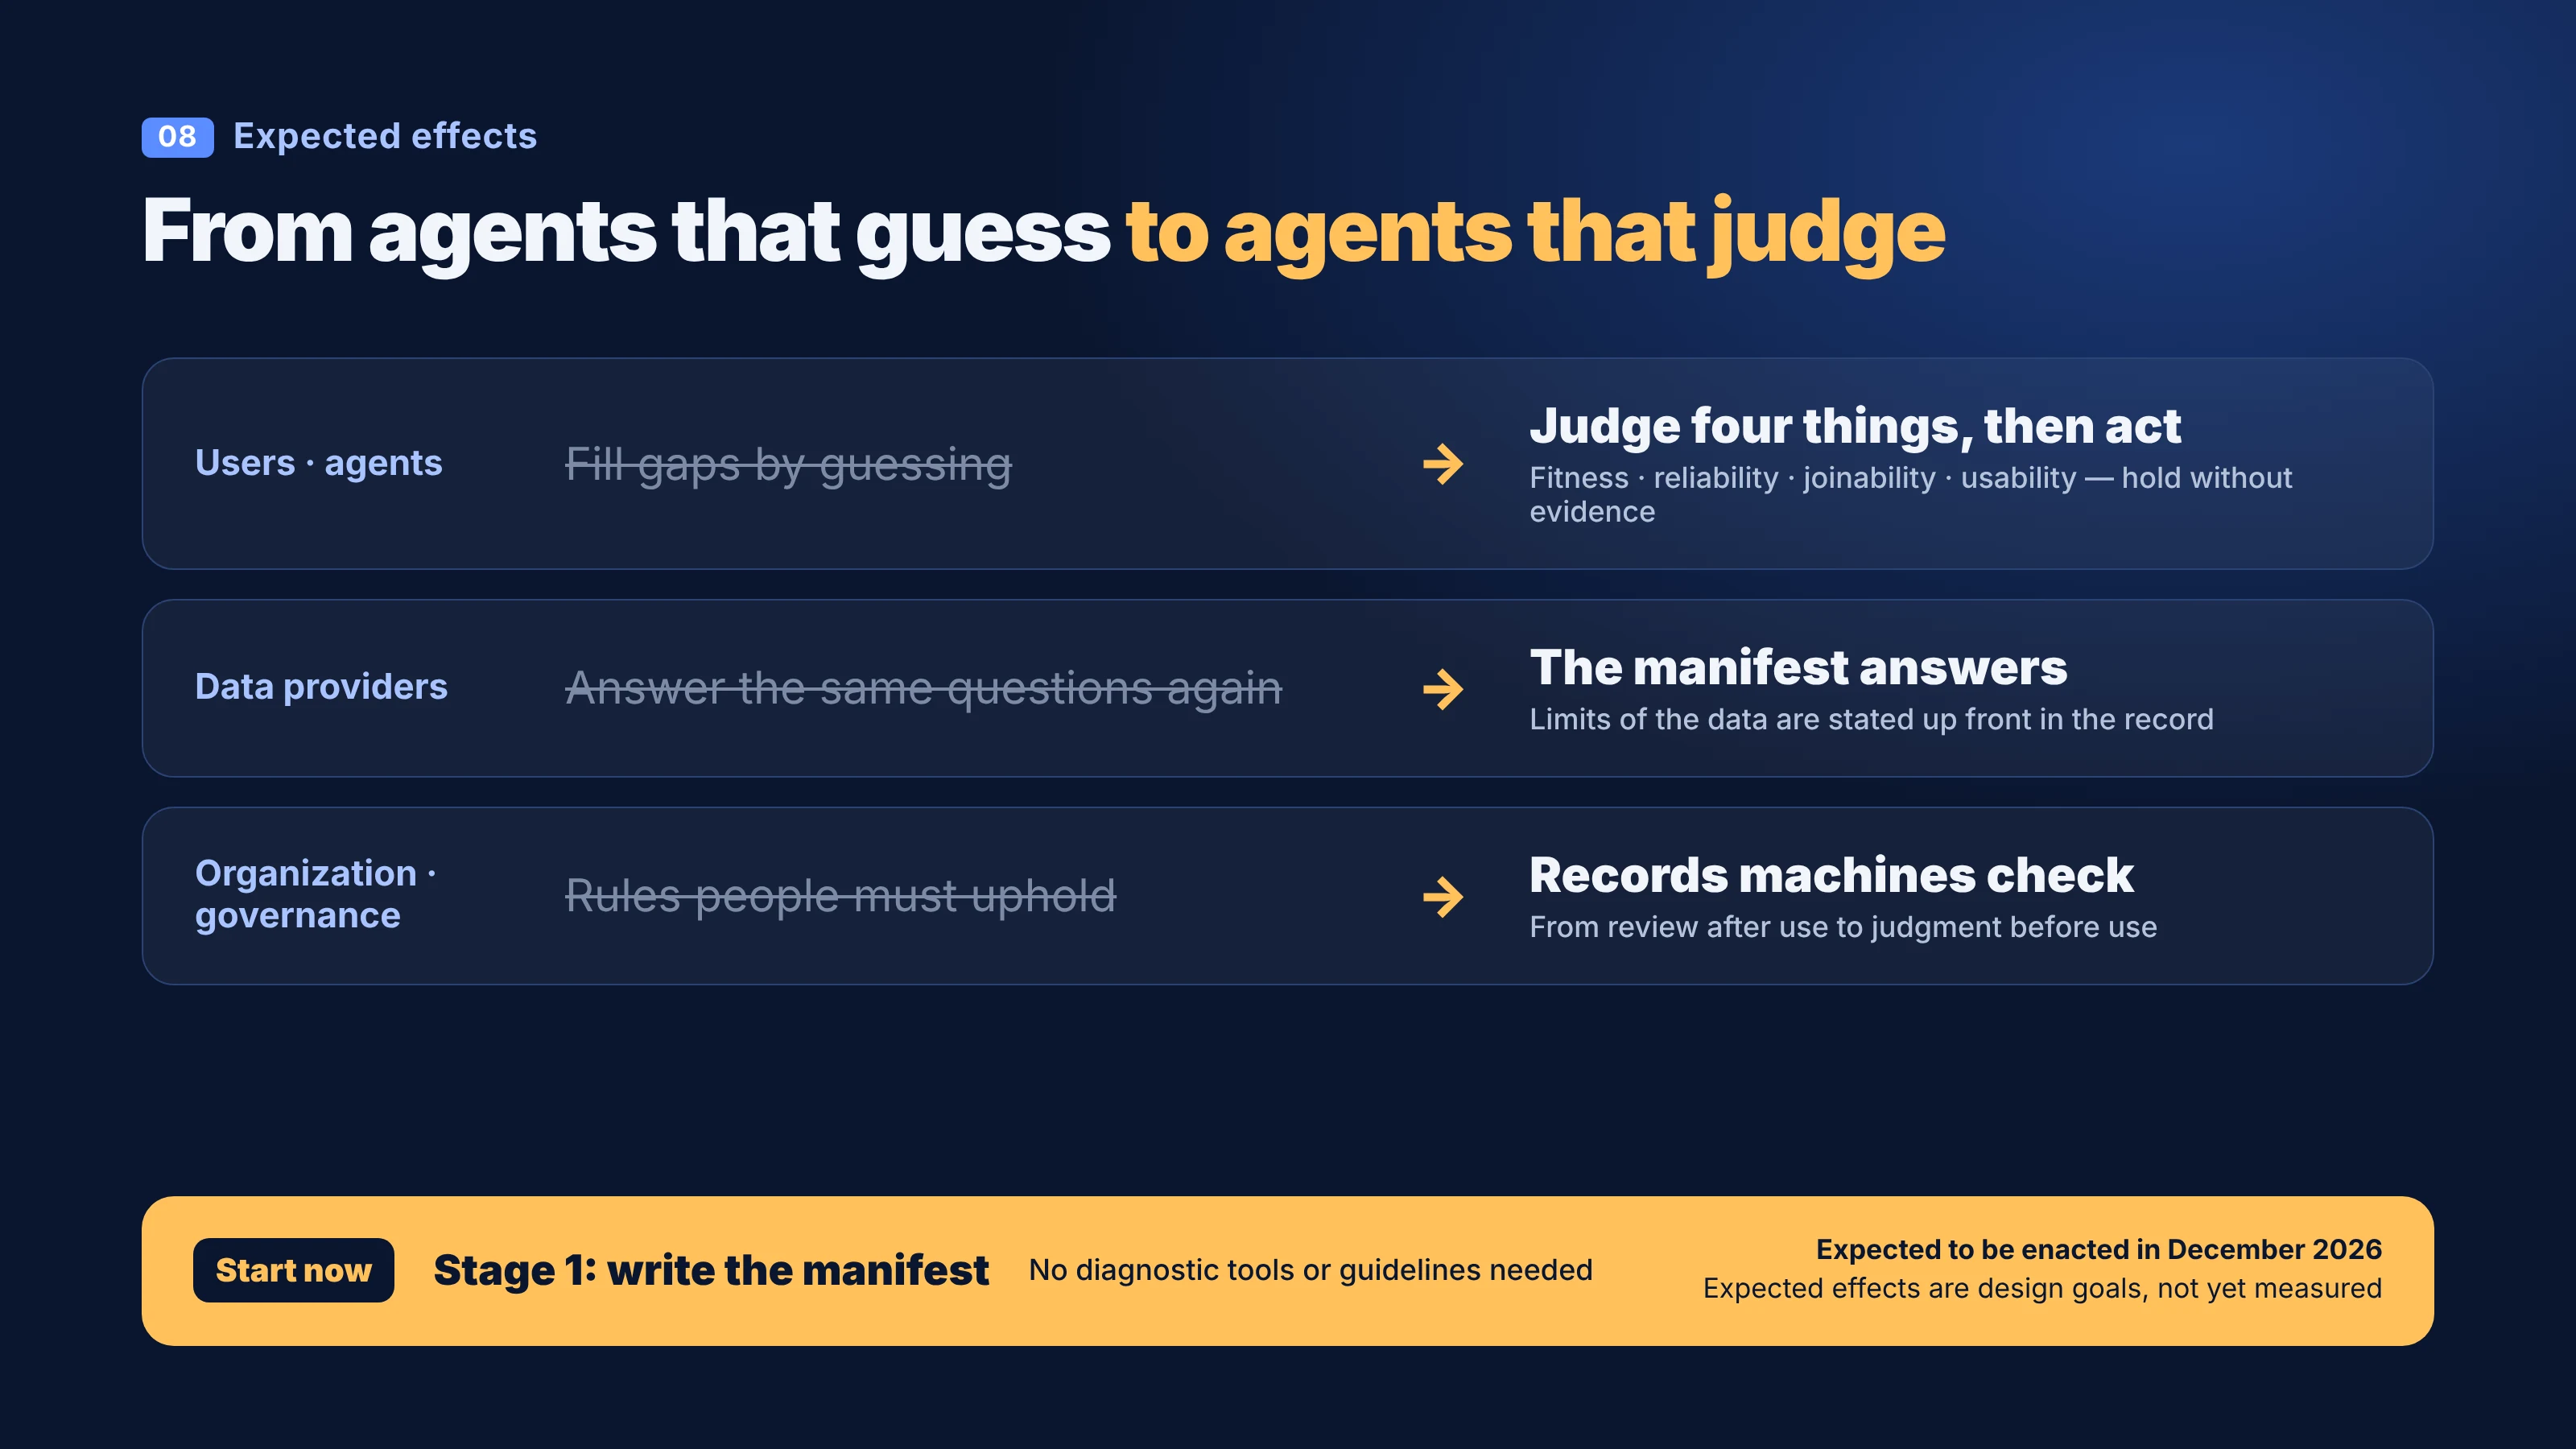
The AI-Ready Data (AIRD) standard specifies how to record facts about data in a machine-readable manifest, measure its quality, judge its readiness, and use the data on that basis. AI agents judge from this record and withhold, instead of guessing, when evidence is missing.
Where it applies
Where to start, by role
Observations of public-sector data and enterprise data are in Why it is needed, with cases. To reproduce judgments, start from Judgment procedure; for terms and elements, start from Reference.
Case videos Under 2 minutes each
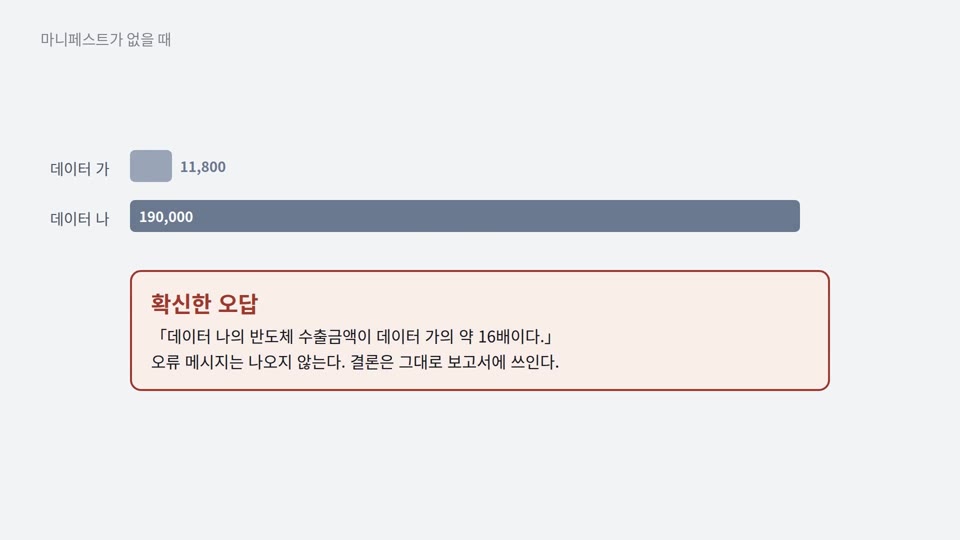 Joinability · Illustrative exampleSame name, different meaningIf differences in unit and period are not reflected, the result is 16 times the correct answer.
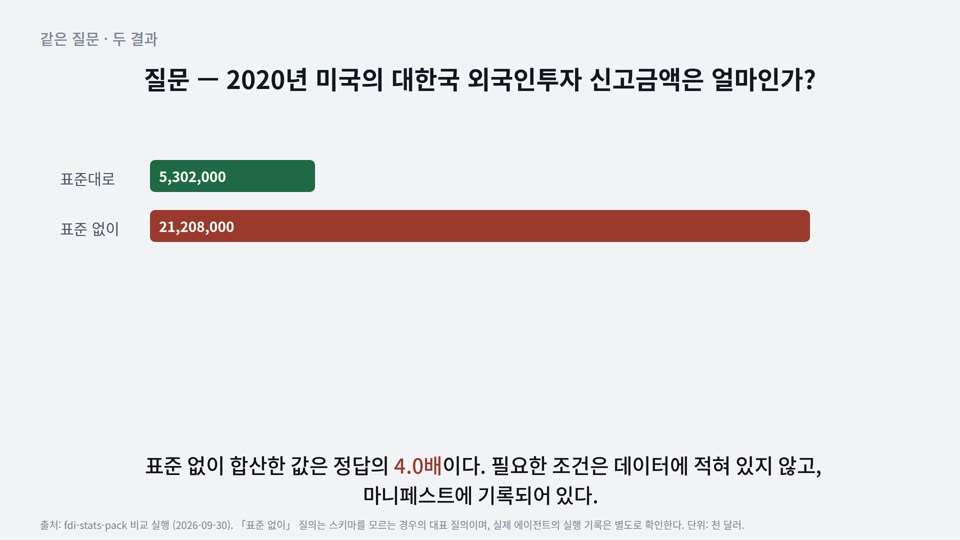 Reliability · Real dataThe same fact counted twiceIf duplicate reports, total rows and observation status are not distinguished, the sum is 4 times the correct answer.
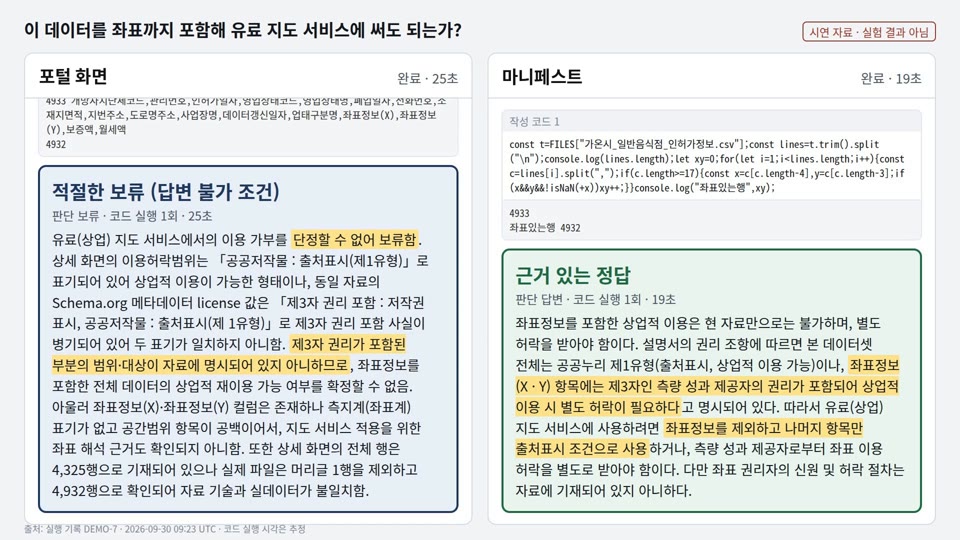 Usability · Run logJudging the permitted scope of useThe portal’s labels alone cannot establish the scope of third-party rights. The rights clause in the manifest states that scope (one run).
At a glance
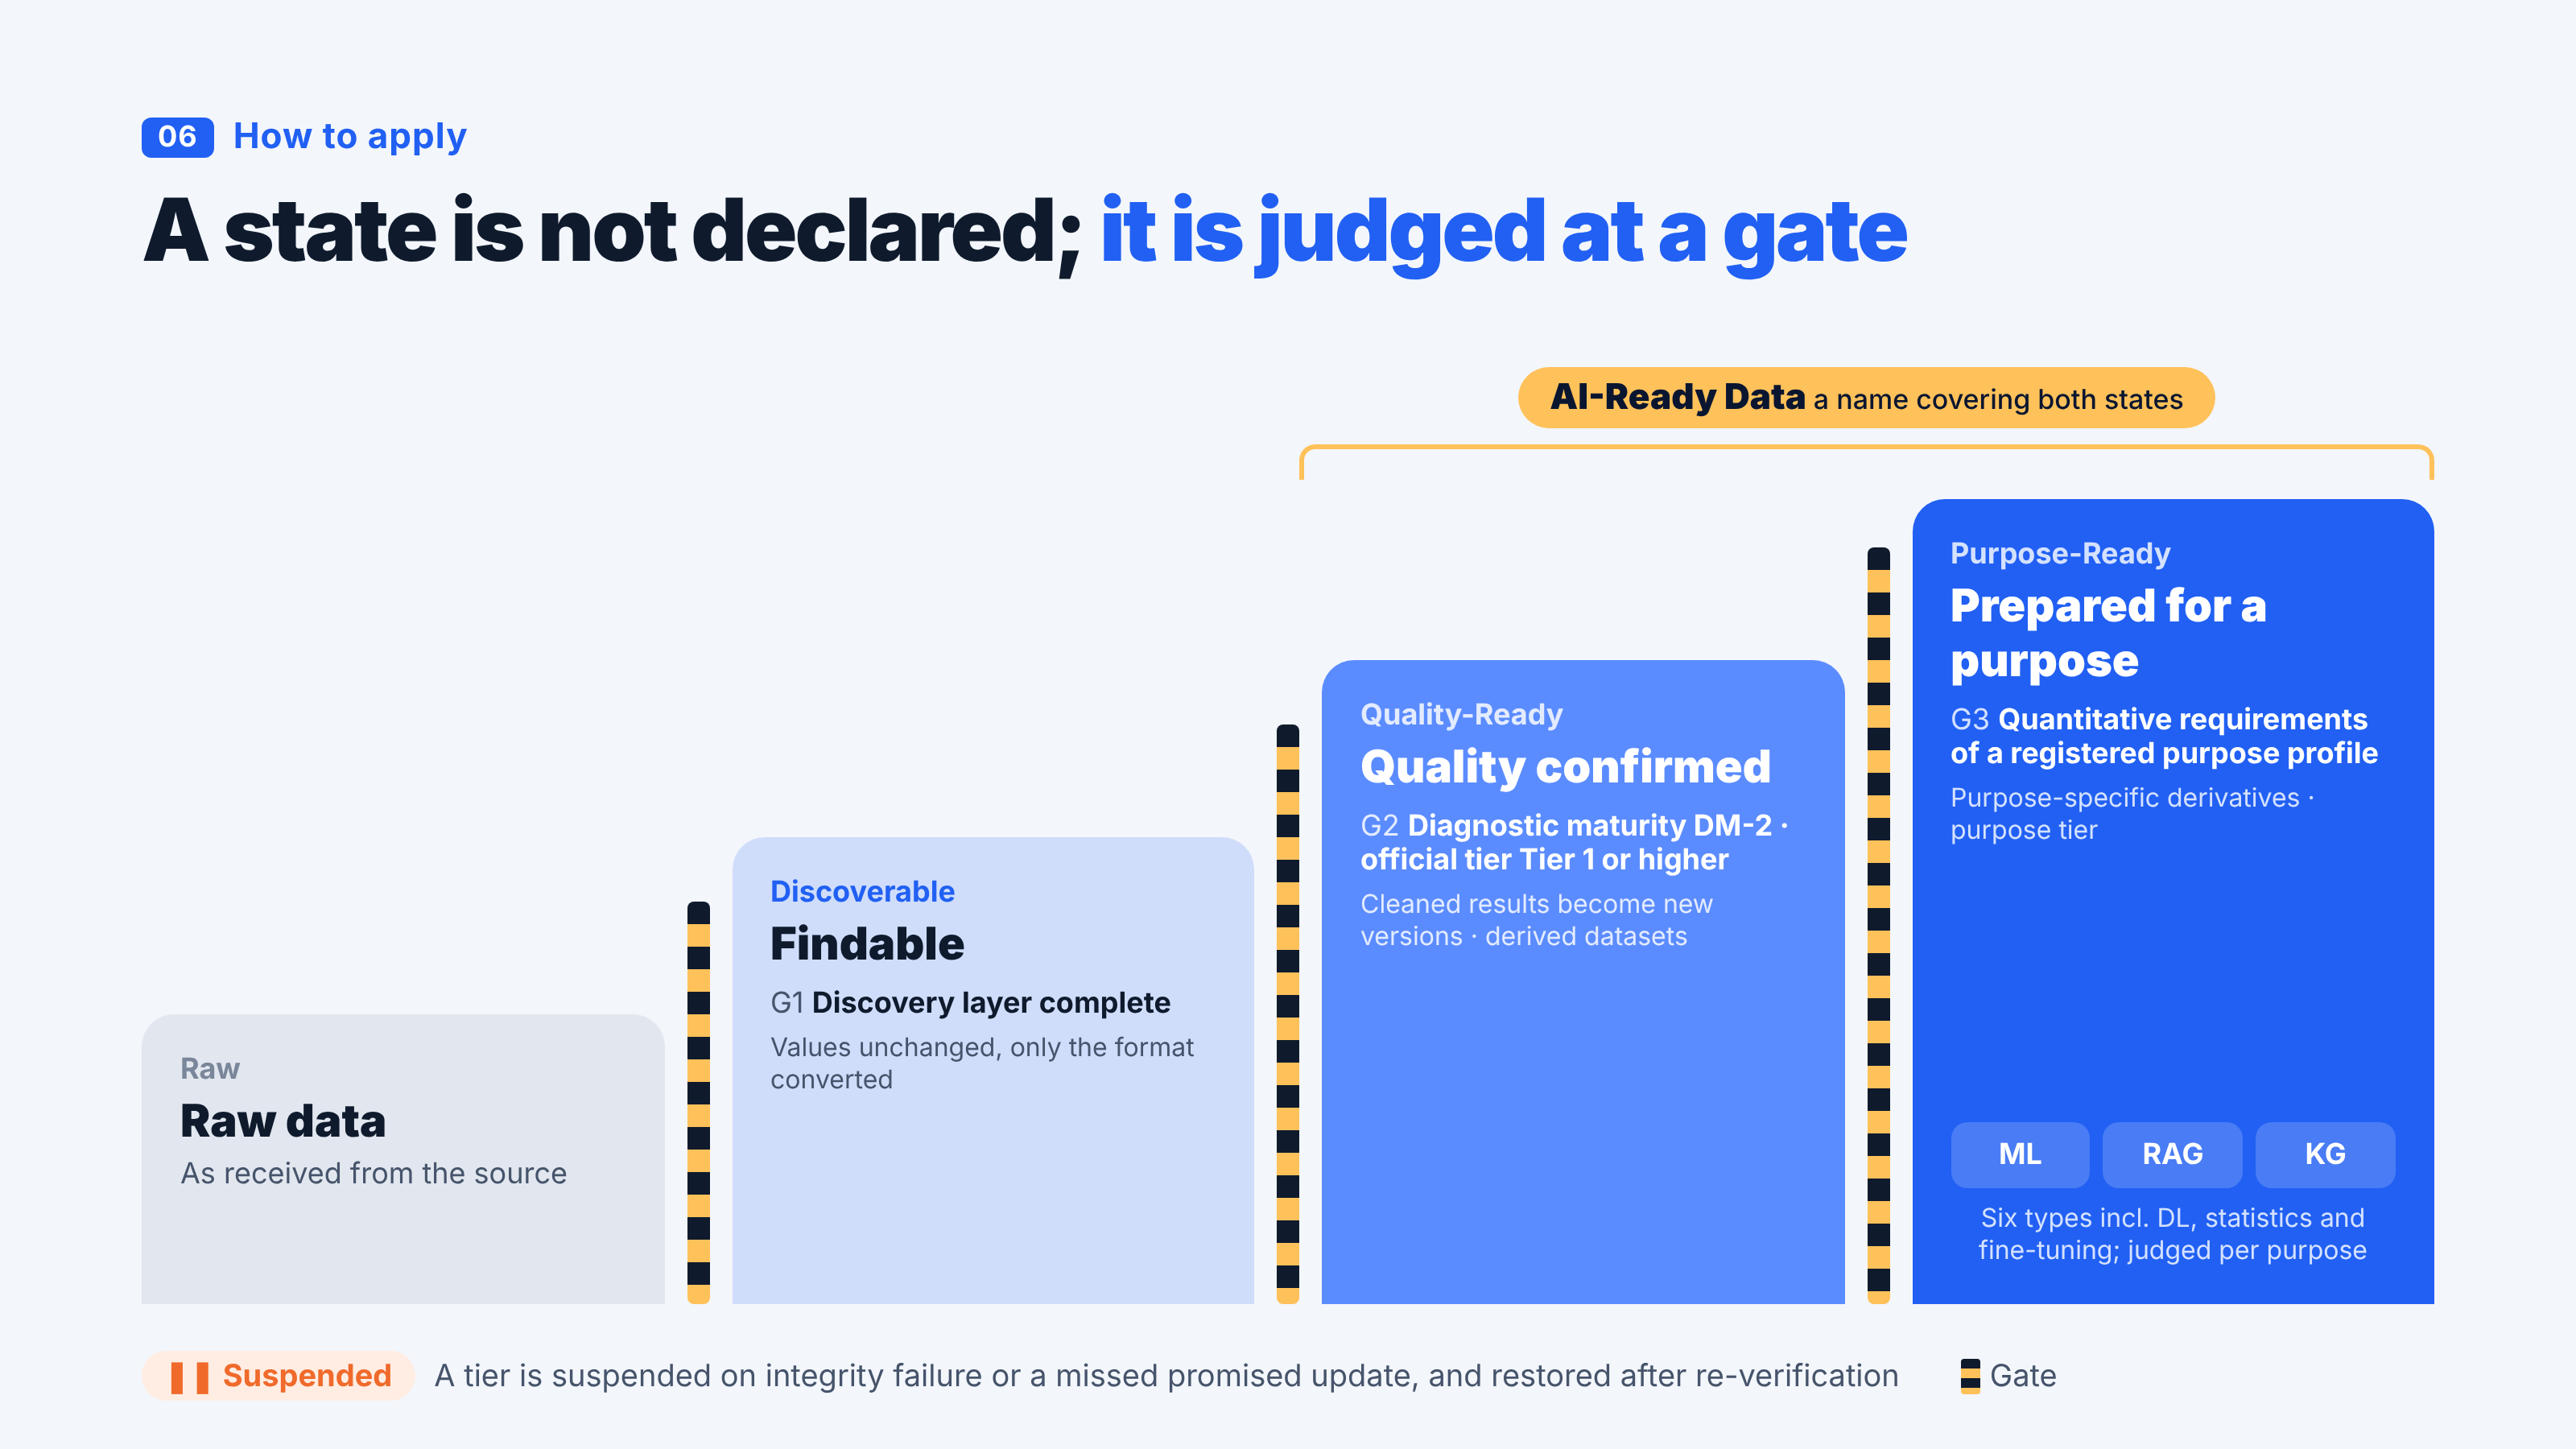
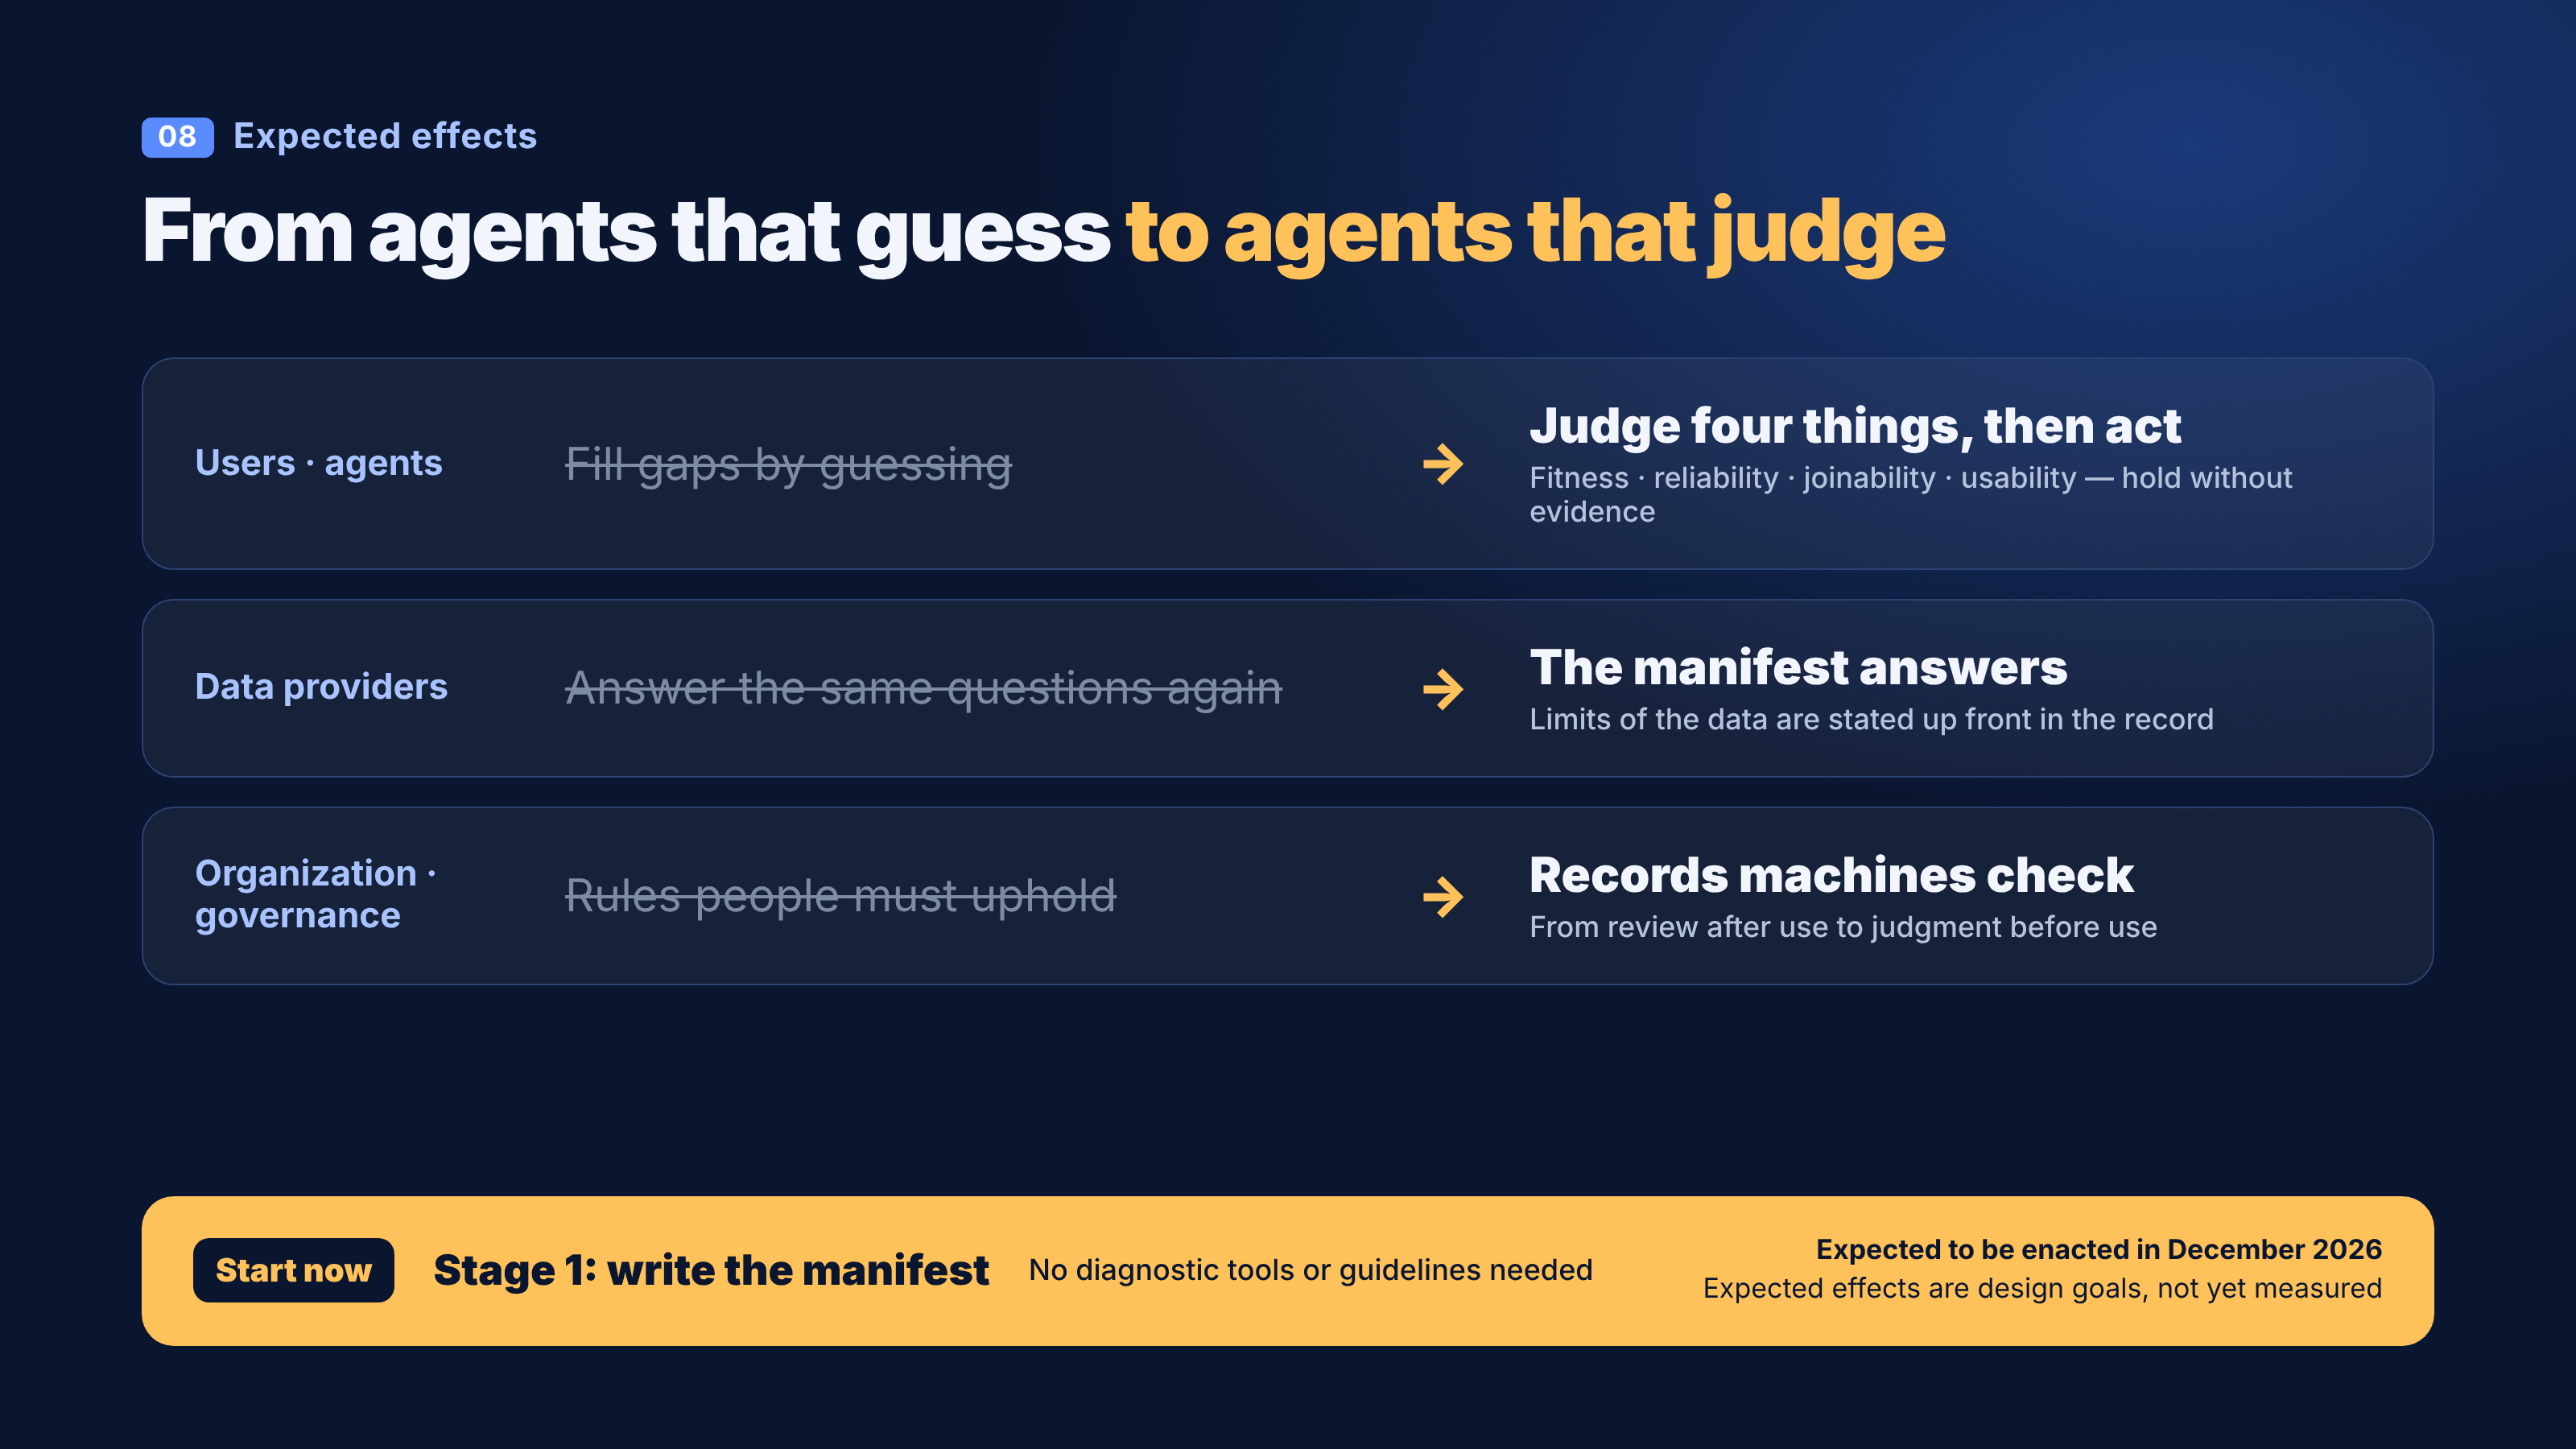
Next steps by role
The schedule is in Current status and release plan.
Why it is needed, with cases
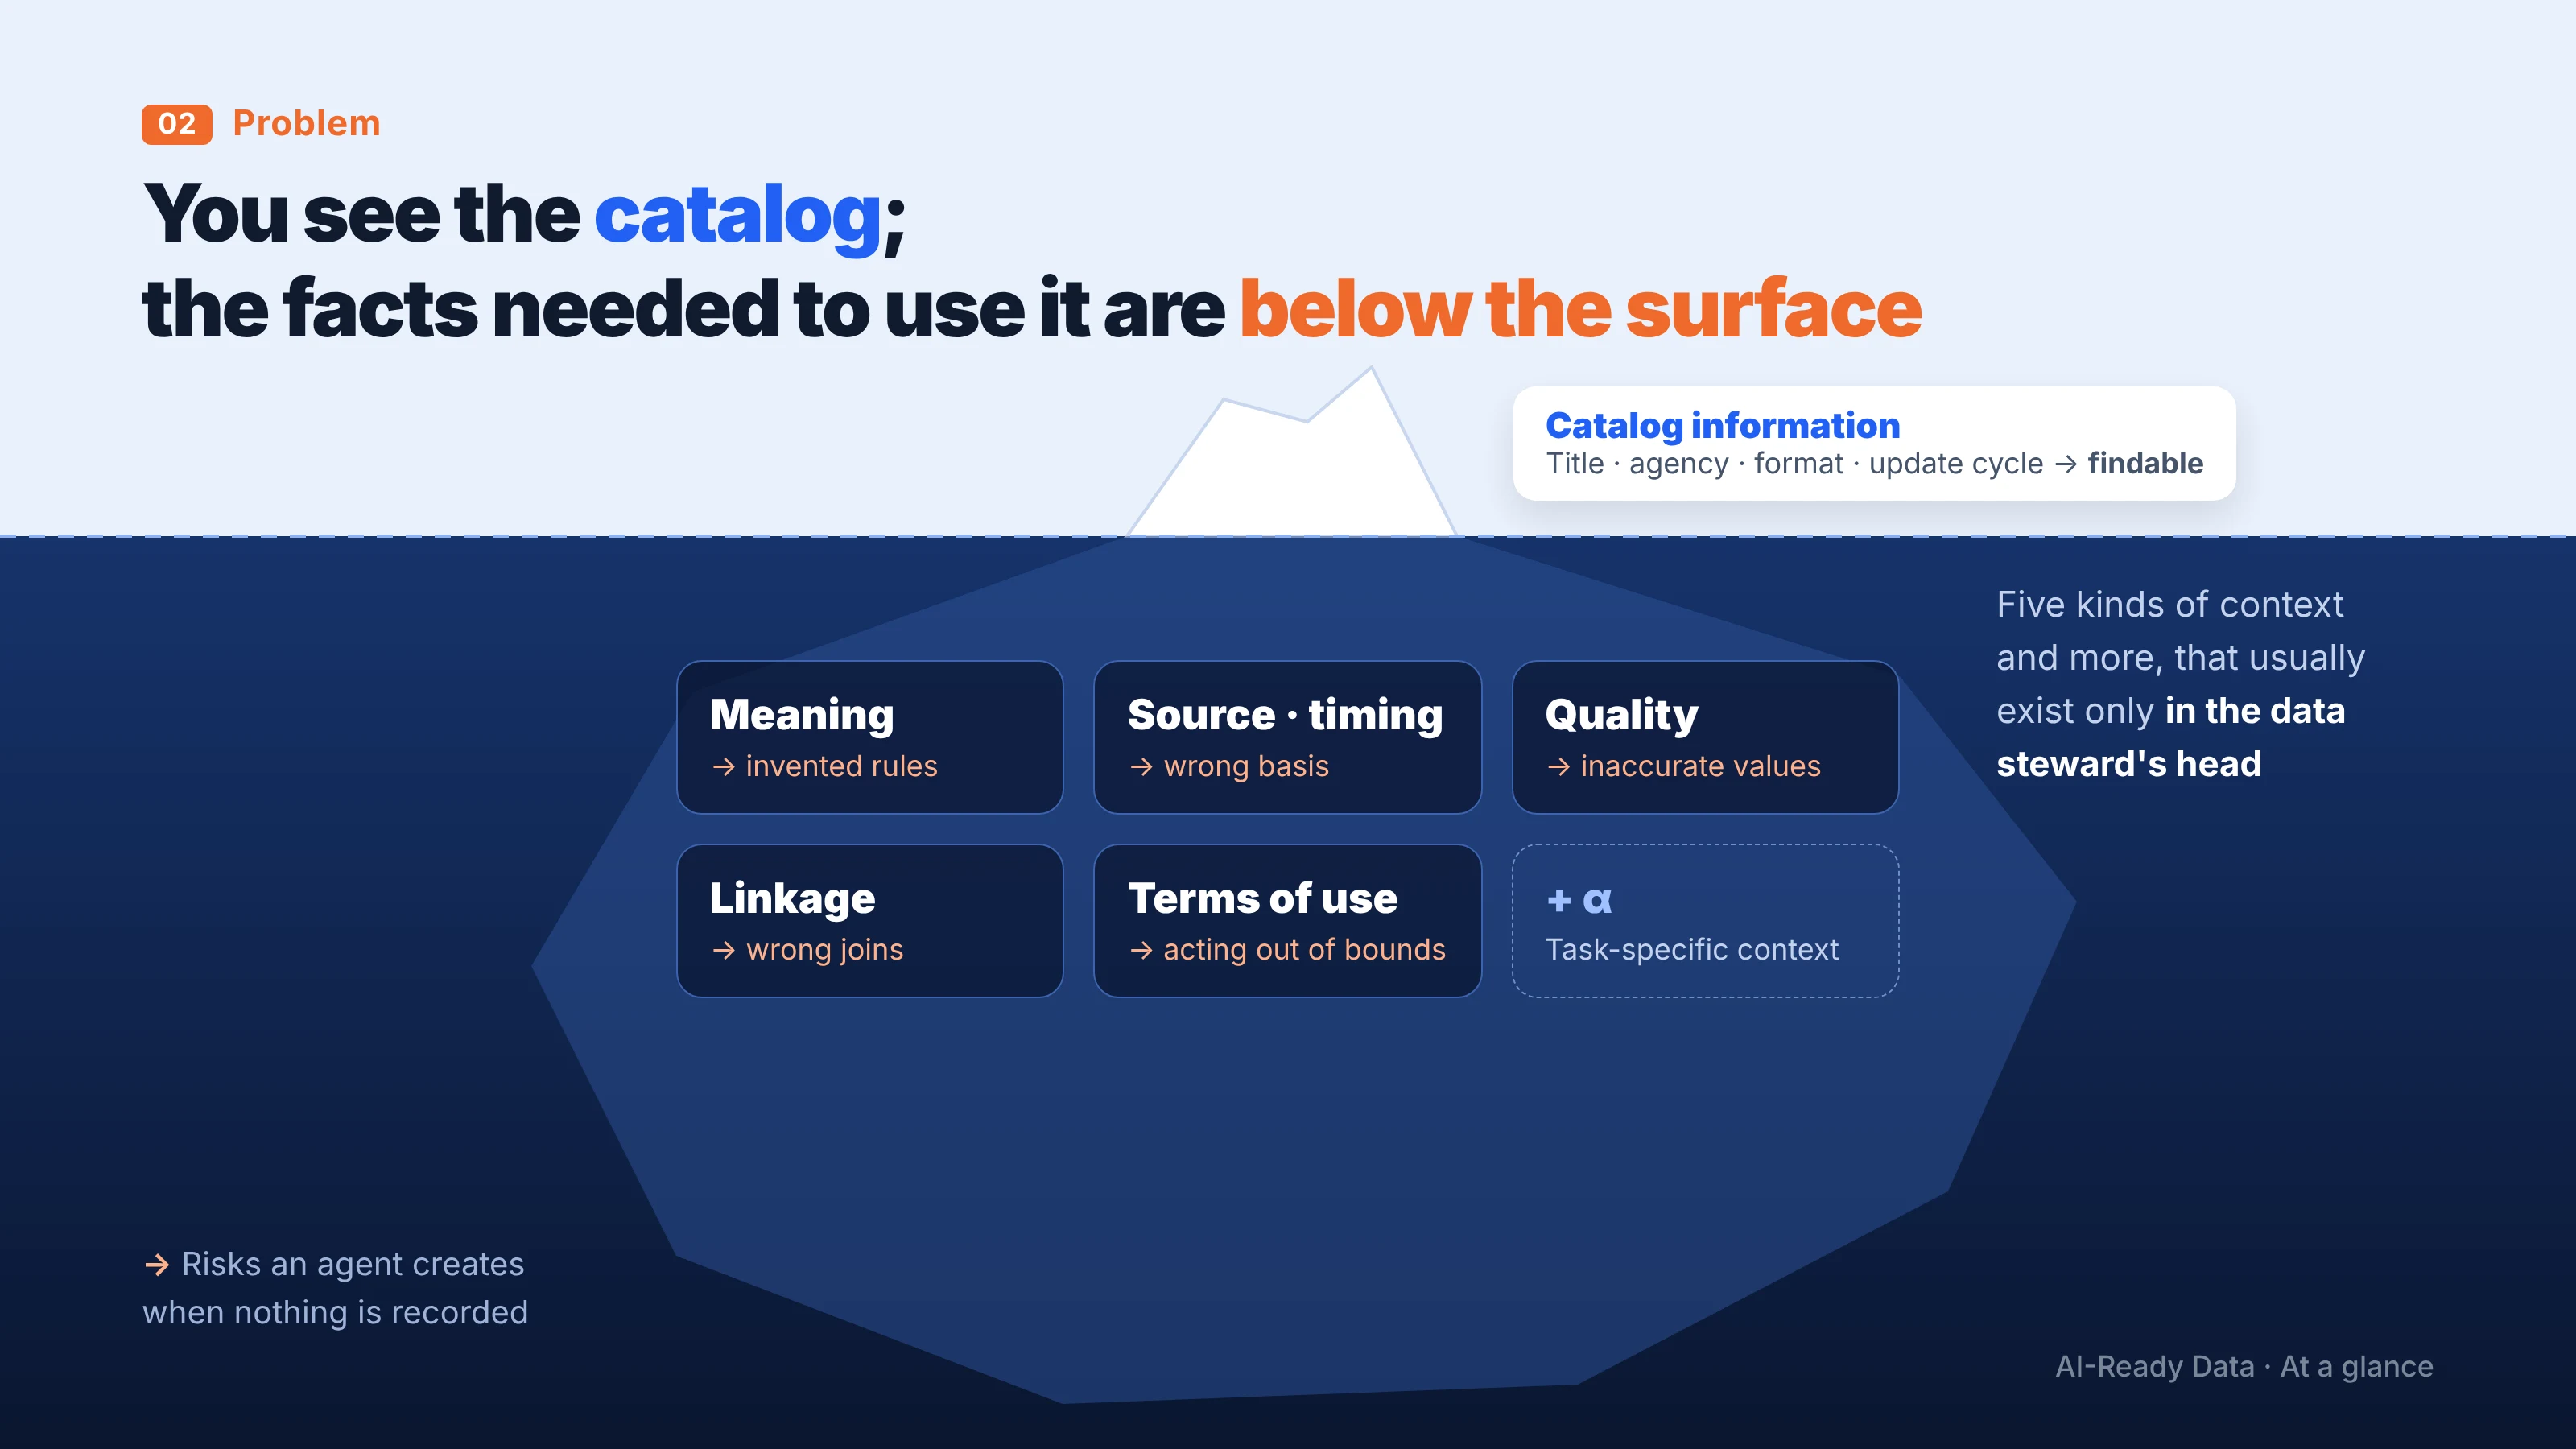
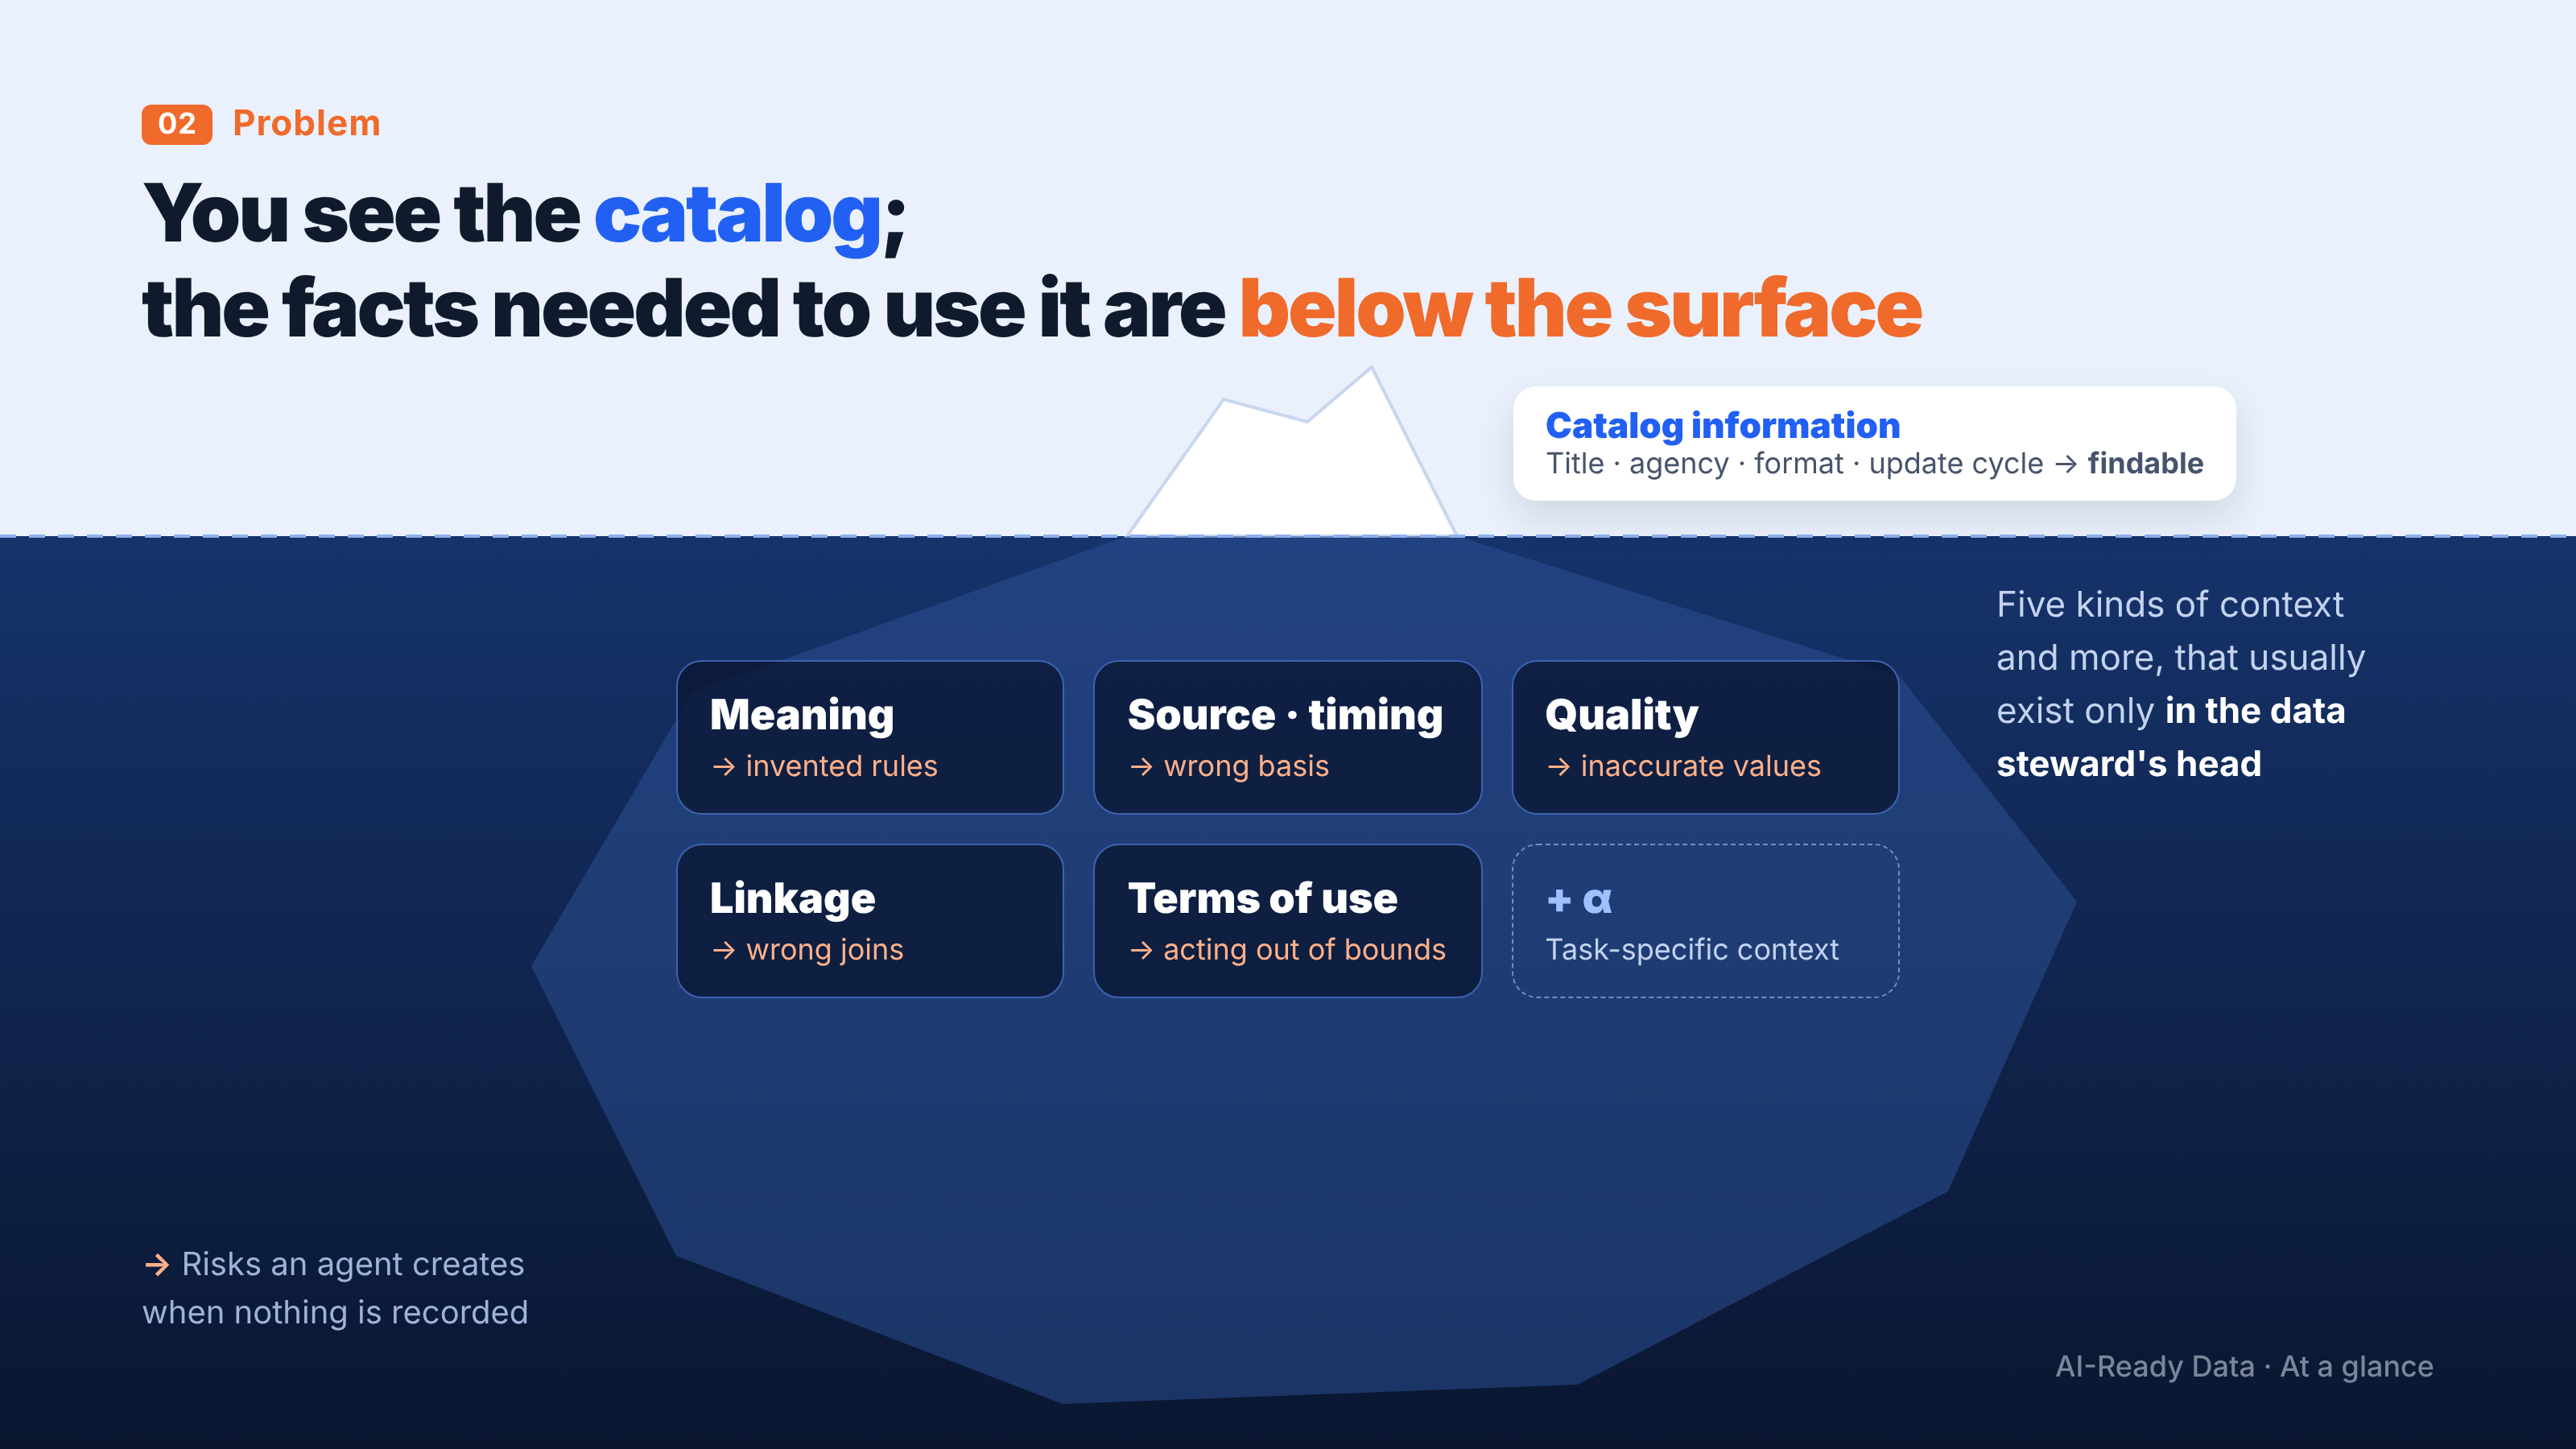
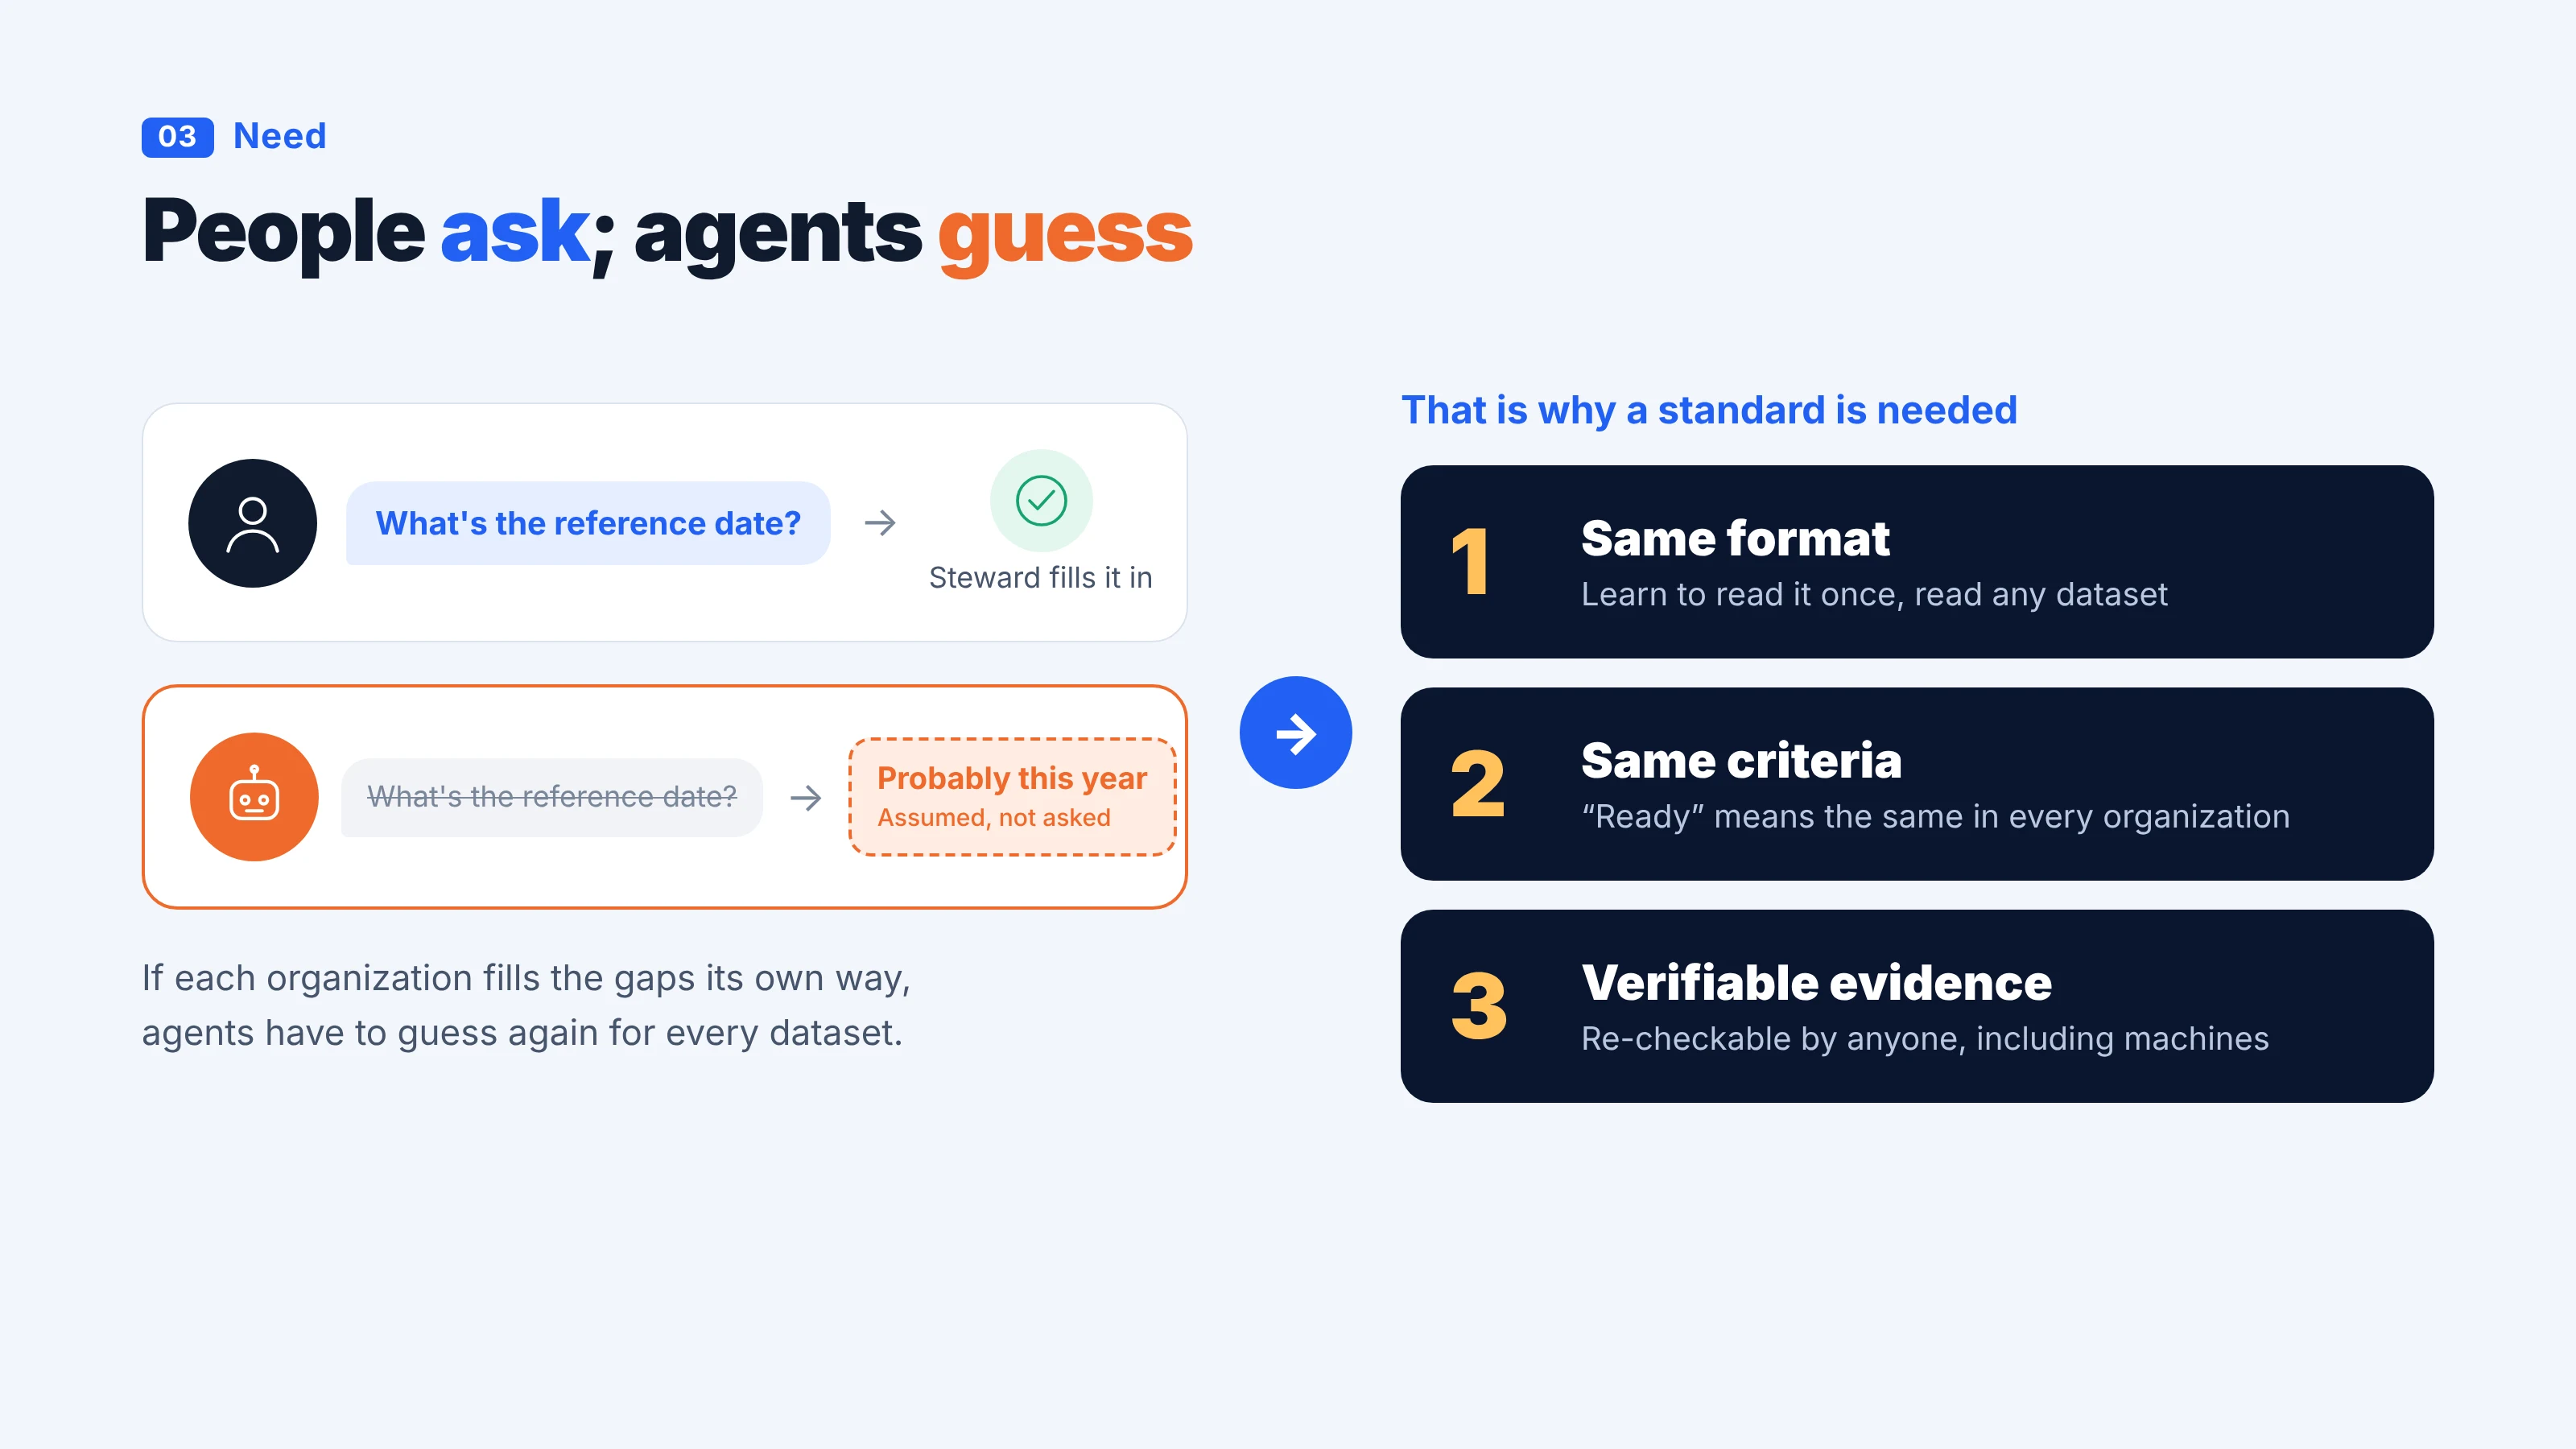
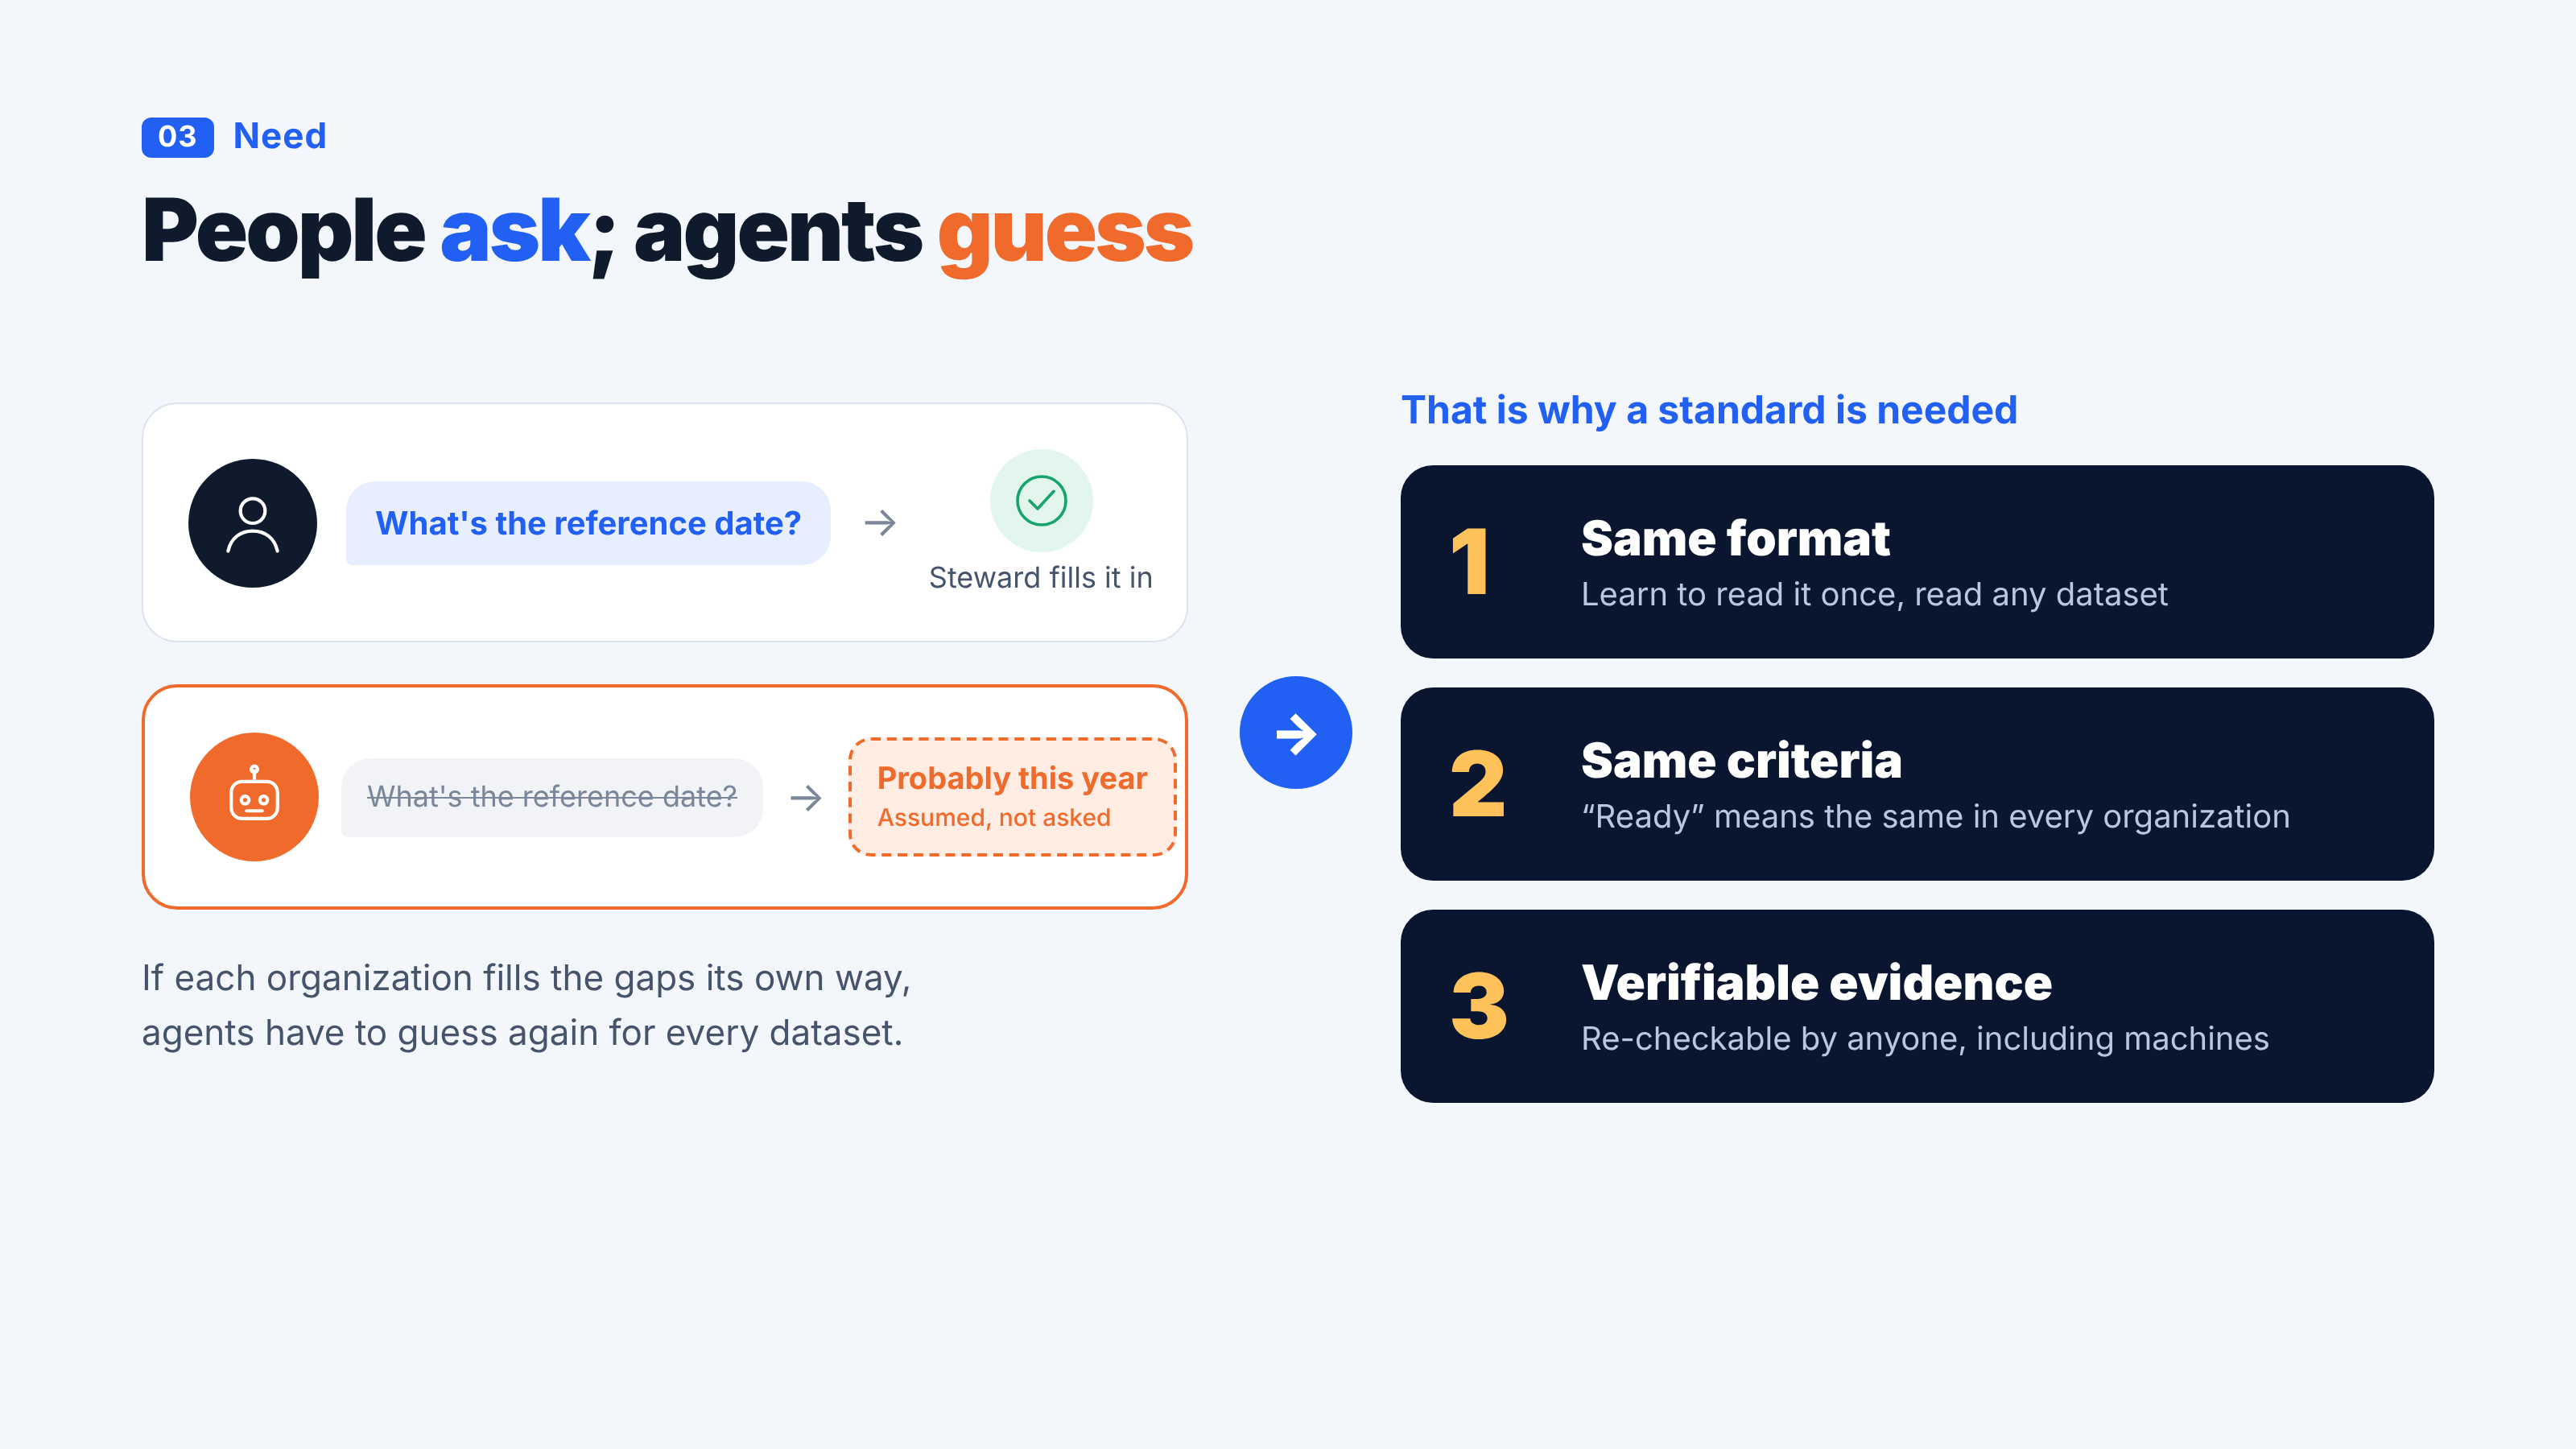
Agents guess facts that are not recorded with the data. Catalog listings alone do not establish currency, units or conditions of use, and the same model judges differently depending on whether a fact is recorded.
Observations of open data
We observed 84,271 file-data entries in the catalog of the Korea Public Data Portal (data.go.kr) (2026-08-31) and found three values that keep an agent from judging.
- 52.2% is the share of file data whose update frequency is “as needed”. An agent cannot judge whether this data is current.
- 20.8% is the share of file data whose next scheduled registration date has already passed. A machine has no evidence to check whether the schedule was kept.
- 0 is the number of fields, among the 36 fields of the catalog open-status listing, that hold a column’s unit or code scheme.
For enterprise data, custom terms of use limit judgment. All three datasets we checked restricted redistribution and automated collection.
Source and enterprise data observation
Source: observation of the Korea Public Data Portal catalog open-status listing (2026-08-31, 84,271 entries). Two DCAT files exported by the portal could not be processed by an RDF parser.
For enterprise data, conditions of use are the first obstacle. We checked the terms of use of three Korean private-sector structured datasets. All three could be downloaded free of charge, but all three restricted redistribution and automated collection through their own terms of use. None of the 14 license values in the vocabulary represents custom terms. The content of custom terms is written as text in rights (dct:rights). People read the terms and judge, but an agent cannot confirm the conditions of use.
Cause of the problem
What is missing is not the data but the facts needed to use it. People check with the provider to fill the gap; agents cannot.
How the standard responds
The standard has these facts recorded in the manifest in a machine-readable format, and has the evidence for quality measurement and judgment kept. Without evidence, an agent withholds instead of guessing. Details on record, measure, judge and use are in What the standard does.
Case videos
There are four videos (no sound; captions are off by default).
The demonstration videos were produced from run logs under the rules of an earlier version. The agents’ judgments do not depend on the measurement rules, but the manifest format shown in the videos differs from the current vocabulary.
Next step: What the standard does
What the standard does
Contents
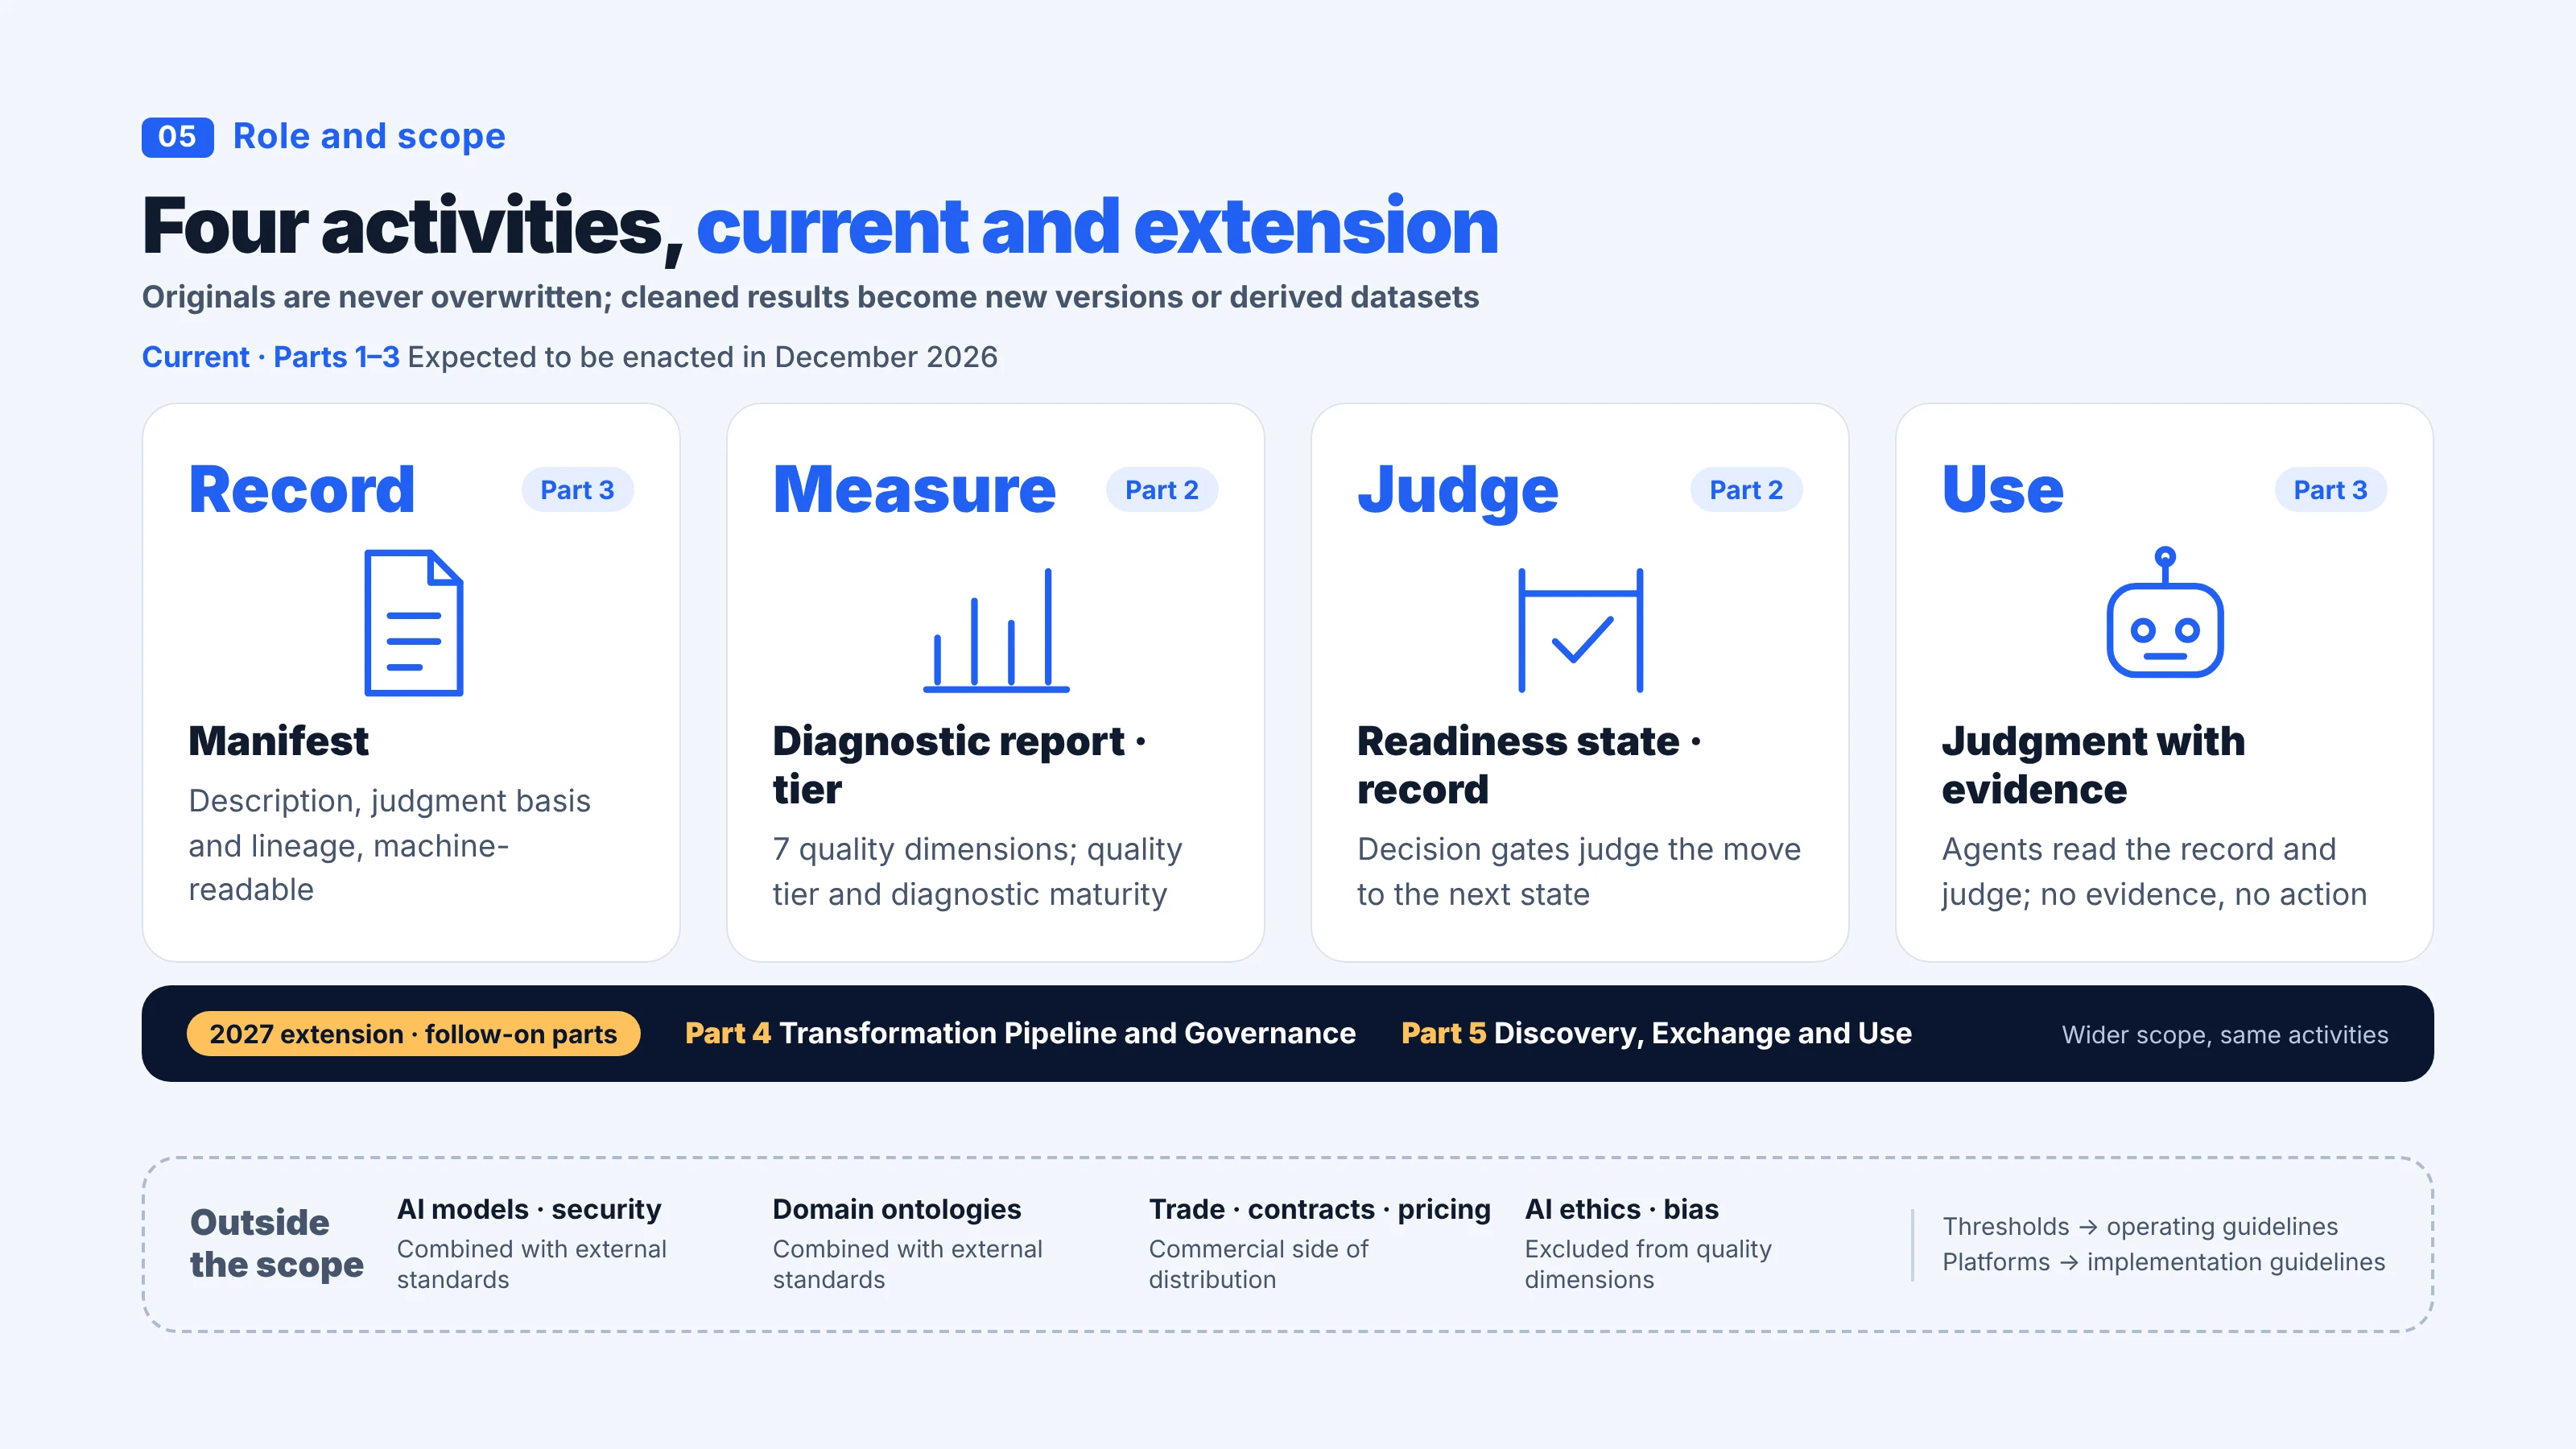
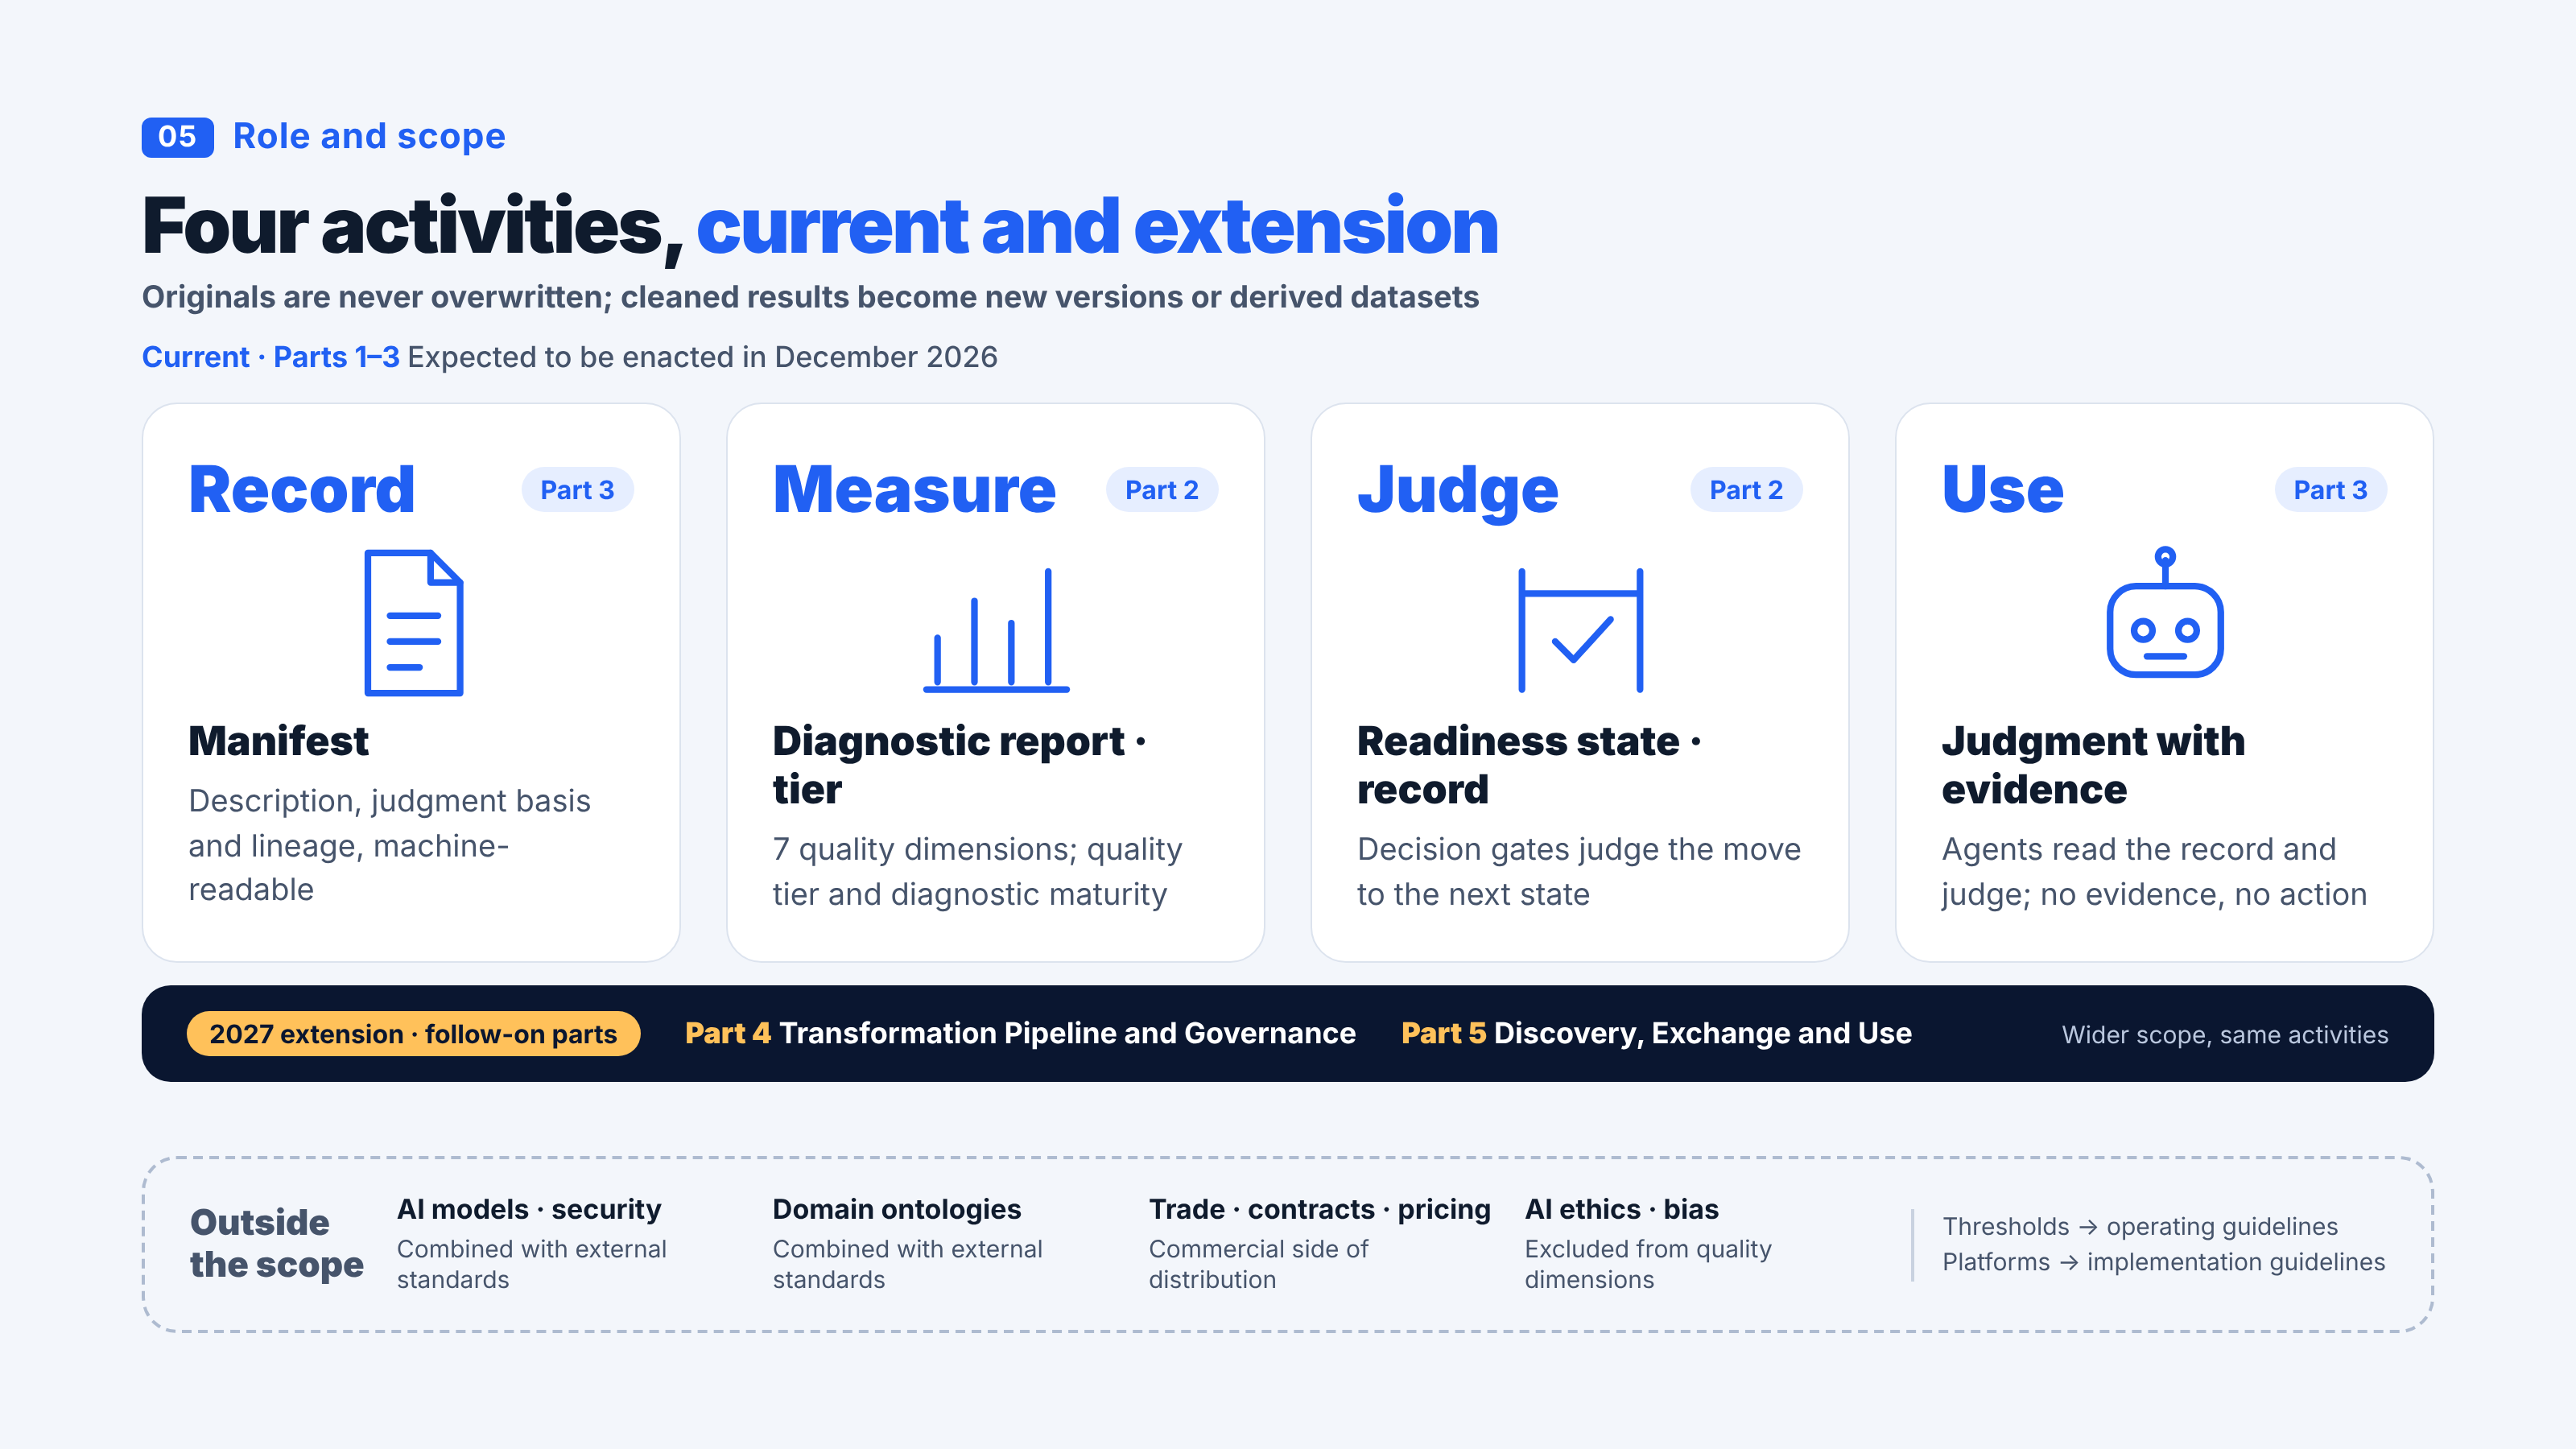
ContentsThe standard specifies four activities: record, measure, judge and use. Each activity records different files and is done by different actors, and each is possible to a different extent today.
The four activities
The four activities are done in order. Measurement needs a record, judgment needs measurement results and an operating guideline, and agents judge from that record. Quality tiers are judged by the organization applying an operating guideline, using the diagnostic tool; the guideline is either the one provided with the standard or one the organization builds and publishes itself.
| Activity | What it does | What remains | Now |
|---|---|---|---|
| ① Record | Records a dataset’s contents, location and conditions of use in set elements. | Manifest | Possible now |
| ② Measure | Measures quality with 16 indicators in 7 dimensions. | Diagnostic report | After the diagnostic tool is released |
| ③ Judge | Judges readiness and quality tier. Thresholds come from the operating guideline. | Readiness state · quality tier | After a guideline is applied |
| ④ Use | Agents judge from the record and withhold when evidence is missing. | Judgments that cite evidence | Partly possible |
What each activity specifies, who does it, which part
| Activity | What the standard specifies | What remains | Done by | Part | Now |
|---|---|---|---|---|---|
| ① Record Writing the manifest | Elements and format for recording a dataset’s contents, location and conditions of use; how to record versions and checksums | Manifest | Data provider | Part 3 (common concepts in Part 1) | Possible now |
| ② Measure Measuring quality and the diagnostic report | Formulas for 16 indicators in 7 quality dimensions; how to record indicator applicability and why an indicator was not measured | Diagnostic report | Diagnostic tool (the data provider prepares the inputs) | Part 2 | Diagnostic tool in development |
| ③ Judge Judgment procedure | Three readiness states and their transition conditions (for moving to the next state), the Diagnostic Maturity (how far the required indicators were measured) decision table, and the quality-tier system and order of judgment. Thresholds (the threshold profile) are set by the operating guideline | Readiness state · Diagnostic Maturity · quality tier, with judgment records | Diagnostic tool · organization applying a guideline | Part 1 (readiness states · transitions) · Part 2 (Diagnostic Maturity · quality tier) | After a guideline is applied |
| ④ Use What agents read | What agents read for each judgment, what they do when evidence is missing, and preparation for a use purpose | Judgments that cite their evidence · purpose-specific preparation results (operation files) | Agents · users · data providers (purpose preparation) | Part 3 (what agents read) · Part 1 (6 use purposes) Discovery, exchange and use in Part 5follow-on | Partly possible The purpose preparation procedure will be published after purpose criteria are registered |
The exact meaning of the concepts used in judgment (readiness state, decision gate, Diagnostic Maturity, quality tier) is in Key concepts. The labels in the “Now” column link to Current status and release plan.
Where the four activities apply in public-sector and enterprise data is in Where it applies.
Current scope and extension
The role of the standard is to set common rules that bring data into a state AI can judge (record · measure · judge) and let it be used as evidence (use). The current scope of the four activities is set by Parts 1–3, expected to be enacted in December 2026; the follow-on parts, expected to be enacted in 2027, extend the same activities.
| Activity | Current (Parts 1–3) | Extension (Parts 4 · 5 · in 2027) |
|---|---|---|
| Record | Elements and format of the manifest (Part 3) | Transformation pipeline (Part 4) |
| Measure | 7 quality dimensions · 16 indicators (Part 2) | — |
| Judge | Readiness state · quality tier · decision gates (Parts 1 · 2) | Governance (Part 4) |
| Use | Agents read the record and judge (Part 3, what agents read) | Discovery · exchange · use (Part 5) |
AI model and security specifications, domain ontologies, trading · contracts · pricing, and AI ethics and bias measurement are outside the scope of the standard; where needed, they are combined with external standards.
Files provided with the data
If only the data file is provided, an agent has to guess the data’s meaning, quality and conditions of use. AI-ready data therefore comes with documents that hold the facts needed for judgment, and the standard calls this distribution unit a pack. A pack consists of the following files.
- Data file: not placed in the pack; referenced by address and SHA-256 checksum.
- Manifest: describes discovery information, quality evidence and readiness state by purpose, and records the addresses and checksums of the other files.
- Diagnostic report: records the indicators measured and not measured.
- Pack manifest: included in packs from Quality-Ready onwards.
- Operation files by purpose: created when a use purpose is set.
An agent reads the evidence in the pack and judges, and withholds when there is none. Pack composition, file formats and validation are in Packaging and distribution.
The standard documents
The AI-Ready Data standard has five parts. Parts 1–3 are the draft standard in the December 2026 establishment scope; Parts 4 · 5 are follow-on parts expected to be enacted in 2027. Thresholds are set by an operating guideline separate from the standard.
Parts, operating guideline, menus and parts, citations
Structure of the standard
Building on the common concepts of Part 1, Part 2 covers measurement and judgment, and Part 3 recording. Part 4 (Transformation Pipeline and Governance) and Part 5 (Discovery, Exchange and Use) are follow-on parts. Parts 1–3 are the TTAK draft (v0.95).follow-on
| Part | Standard title | Role | Governing document |
|---|---|---|---|
| Part 1 | AI-Ready Data - Part 1: Overview and framework | Overview and framework · terms · readiness states · data types · use purpose types | Draft standard |
| Part 2 | AI-Ready Data - Part 2: Quality measurement and tiering | Quality measurement · tiering · 16 indicators · Diagnostic Maturity (DM) | Draft standard |
| Part 3 | AI-Ready Data - Part 3: Dataset description schema and application profile | Dataset description schema · manifest element specification · application profile · controlled vocabulary | Draft standard |
| Part 4 | AI-Ready Data - Part 4: Transformation Pipeline and Governance | To be set in the follow-on part | Follow-on part — expected to be enacted in 2027 |
| Part 5 | AI-Ready Data - Part 5: Discovery, Exchange and Use | To be set in the follow-on part | Follow-on part — expected to be enacted in 2027 |
Work on Parts 1–3 began on March 9, 2026; Parts 1–5 were proposed to TTA (Telecommunications Technology Association) as a standard on May 13, 2026; the review is in progress at TTA regular meetings. Progress is described in Origins and progress.
Specification documents
Requirements are set by the specification documents, so where the explanation and the specification differ, the specification prevails. This site links to the specification instead of reproducing it, and links to the specification documents will be added at establishment. References in the “Basis:” line (for example, Part 2 8.1) are clauses of the specification. When the specification documents will be published is in Current status and release plan.
Operating guideline
The standard specifies the method of judgment and the tier system; the operating guideline sets the thresholds (the threshold profile) and operational matters such as the diagnosis cycle and appeals. Organizations, agencies and domains may build their own guidelines, and every tier states the identifier and version of the guideline applied. How to build a guideline and the items of a threshold profile are in Building an operating guideline.
Site menus and parts
| Menu | Main parts explained |
|---|---|
| About the standard | Part 1 |
| Preparing data | Parts 1 · 2 · 3 |
| For agents | Part 3 |
| Operating guidelines | Part 1 7.1 · Part 2 Annex D |
| Concepts and judgment | Parts 1 · 2 · 3 |
| Reference | Parts 1 · 2 · 3 |
Types of references
External documents cited by the specification are divided into normative references, which are part of the conformance obligations, and a bibliography, which aids understanding. Both lists are in the specification documents.
Next step: Where it applies
Basis: Part 1 3.15, 5.5
Where it applies
Contents
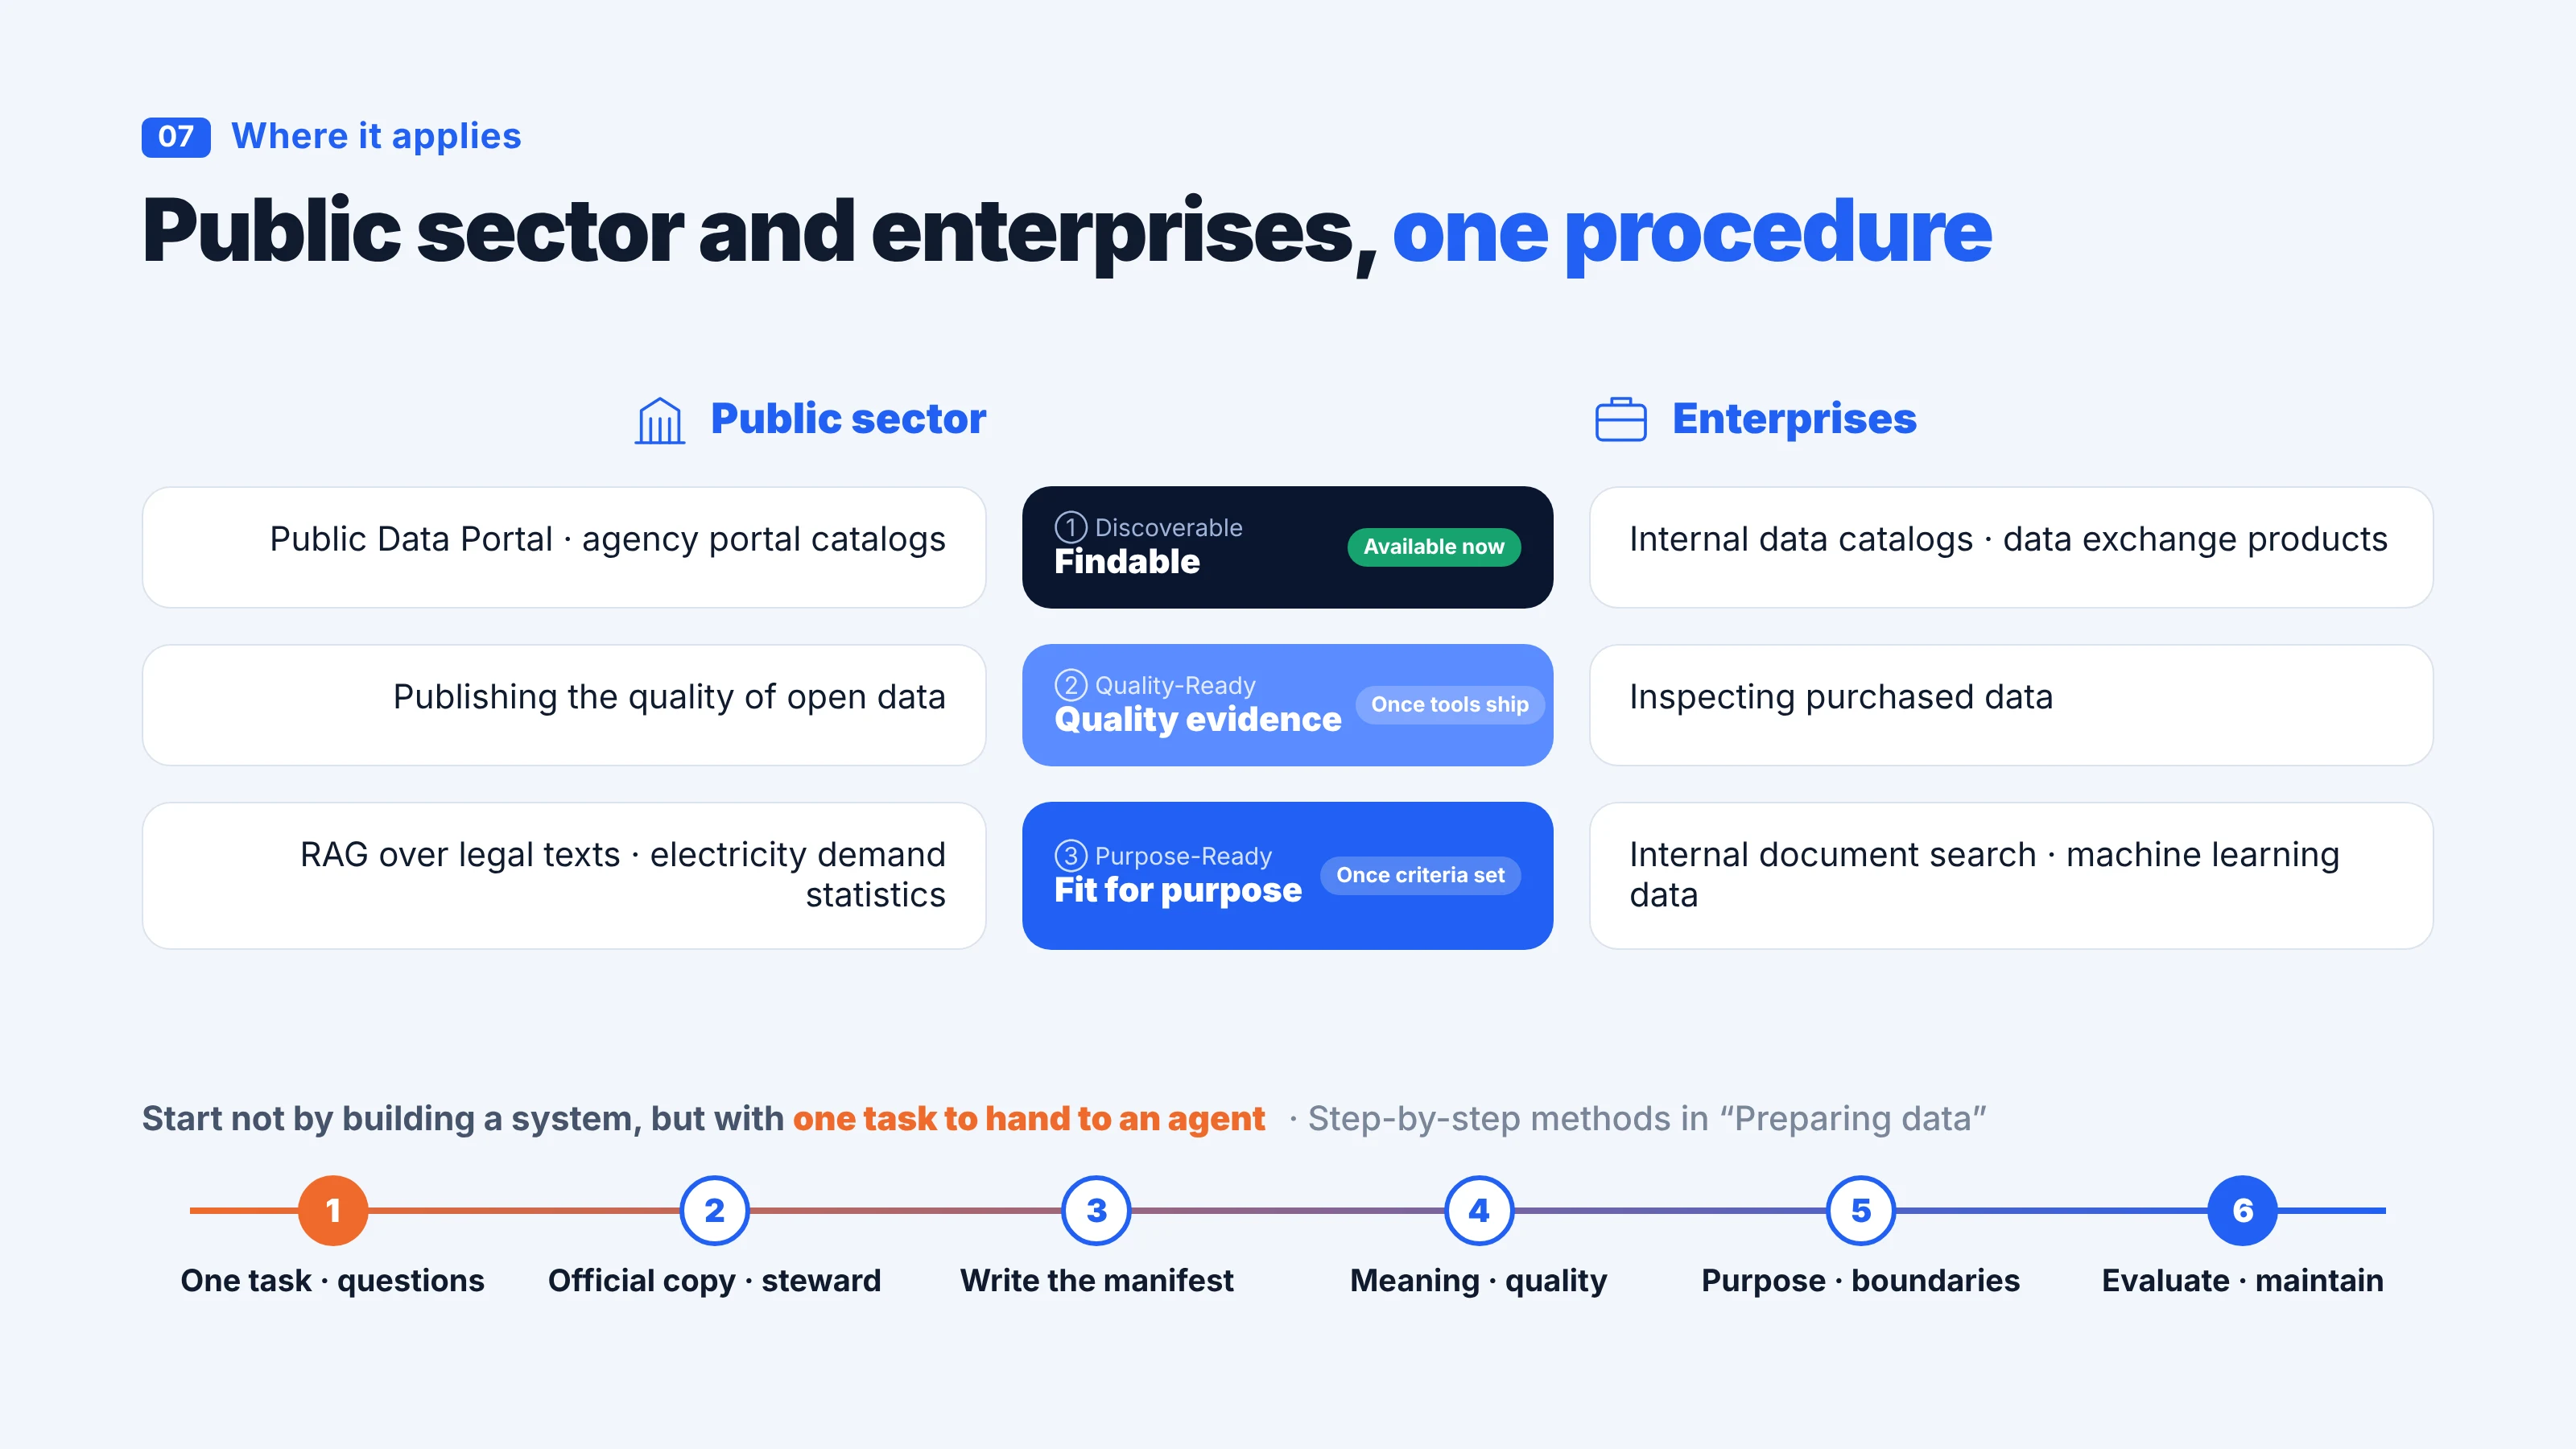
ContentsDiscoverable data applies to data catalogs; Quality-Ready data to published quality evidence and data acceptance; Purpose-Ready data to retrieval-augmented generation, machine learning and statistical analysis. The same procedure applies to public-sector and enterprise data.
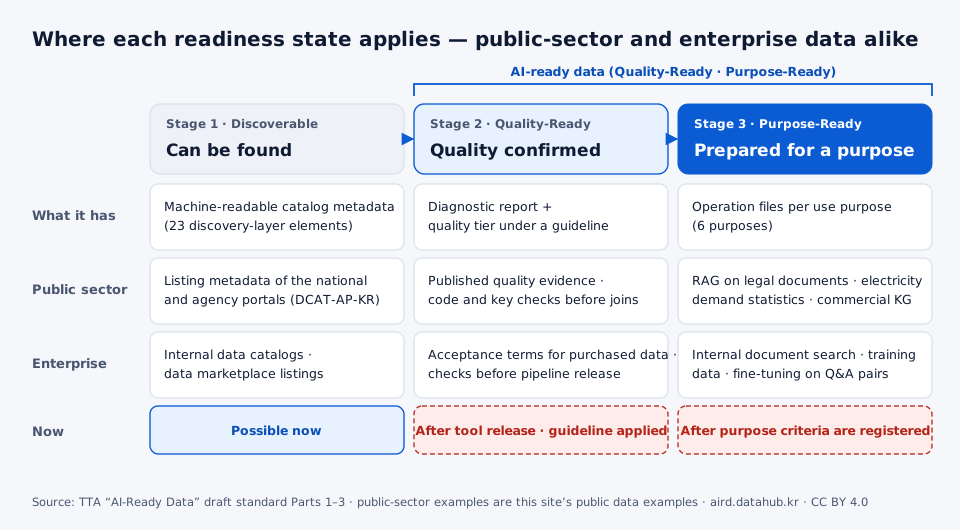
Starting point by organization
The stage an organization starts with, and how much it can do now, depend on its situation.
| Situation | Start with | Now |
|---|---|---|
| Opening or providing data to others | Stage 1 — bring listing metadata up to the discovery layer (Writing the manifest) | Possible now |
| In-house AI or agents finding and using data | Stage 1, with usability elements first (license, conditions of use, access rights) (What agents read) | Possible now |
| Buying, procuring or delivering data | Stage 2 — diagnostic report and operating guideline (Adoption brief) | After the diagnostic tool is released |
| Processing data for RAG or machine learning | Stages 1 and 2 first, then stage 3 | After purpose criteria are registered |
| Ranking organizations by data quality | Not suitable. A tier must be read with the guideline applied, so tiers under different guidelines cannot be ranked against each other. | — |
Discoverable — data catalogs
This applies to national and agency portal listings in the public sector and to internal catalogs and marketplace listings in enterprises, and it is possible now.
Public-sector and enterprise examples
Stage 1 provides a dataset’s contents, location and conditions of use as machine-readable metadata, in the form of the 23 discovery-layer elements of the manifest. It is the stage that applies the standard to a data catalog: data values are not changed, and it can be done now without a diagnostic tool or operating guideline.
| Sector | Applies to | What the standard adds |
|---|---|---|
| Public sector | Listing metadata of the Korea Public Data Portal (data.go.kr) and agency portals | Portal listing fields can be expressed in the vocabulary of DCAT-AP-KR (Korean application profile of DCAT for data portals). The discovery layer uses this vocabulary, adds elements agents need for judgment (lifecycle status, creation method and others), and records values such as update frequency from standard value lists instead of text strings. |
| Enterprise | Internal data catalogs · data marketplace listings · data specifications given to partners | The same elements and value lists apply. Title and description come from the internal catalog; identifiers use addresses based on the company domain. |
After this stage, agents can find the data, and read and process its update frequency and conditions of use from the metadata. An MCP server that applies part of the draft standard’s judgments to the portal’s listing metadata (Public Data Lens) is a working example of this stage.
Quality-Ready — quality evidence and acceptance
This applies to published open-data quality in the public sector and to acceptance of purchased data in enterprises, and it is possible after the diagnostic tool is released. Data in the Quality-Ready state that meets the common readiness requirements is AI-ready data.
Public-sector and enterprise examples, and current status
Stage 2 measures the quality of data values with 16 indicators in 7 dimensions and records measured and unmeasured indicators together in the diagnostic report. The quality tier is judged with the thresholds of the operating guideline applied.
| Sector | Applies to | What the standard adds |
|---|---|---|
| Public sector | Quality information of open data · checks before joining data from several agencies | Quality check results are published as a machine-readable diagnostic report. Indicators such as referential integrity against code tables and record-key uniqueness find problems before joins. |
| Enterprise | Acceptance of purchased or procured data · checks before releasing internal data pipelines | Delivery terms can state “guideline identifier, version and quality tier”. Wording for procurement and contracts is under review. |
The distributable diagnostic tool that produces the report is in development. Organizations can build their own operating guideline; the guideline provided by the standard will be published when the standard is established. The schedule is in Current status and release plan.
Purpose-Ready — preparation for AI use purposes
This applies to preparation per use purpose, such as RAG on legal documents and electricity-demand statistics in the public sector, or internal document search and machine-learning data in enterprises. It is possible once purpose criteria are registered.
Public-sector and enterprise examples, and current status
Stage 3 prepares the data for each use purpose and produces operation files per purpose. The standard has six use purposes: machine learning (ML), deep learning (DL), retrieval-augmented generation (RAG), fine-tuning (FineTuning), knowledge graphs (KG) and statistical analysis (Stats).
| Sector | Applies to | Examples on this site |
|---|---|---|
| Public sector | Q&A on laws and administrative documents · statistical analysis · knowledge graphs | Public data examples — legal documents × RAG · legal interpretation cases × fine-tuning · electricity demand × statistics · commercial district data × KG |
| Enterprise | Internal document search (RAG) · machine learning data · fine-tuning on customer-support instruction and response pairs | — |
A purpose tier is judged only after the purpose criteria (purpose profile) are registered. No purpose criteria are registered yet, so the purpose tier of every example is “not judged”, and the guide to preparing for a purpose will be published once purpose criteria are registered.
Outside the scope of the standard
- Portal features: data portal features (search screens, Q&A, recommendations) are not covered. The subject of the standard is the data and a record of the data that machines can read and process.
- Obligation: this standard is not an obligation under laws or regulations. Organizations cite it in management guidelines, project requirements or contract terms.
- Personal data: it does not replace personal data assessment. Whether data contains personal data is recorded; the assessment is made by the privacy office.
Next step: Current status and release plan
Current status and release plan
Contents
ContentsWriting the stage 1 manifest and fixing defects are possible now. Quality-tier judgment needs an operating guideline; the guideline provided by the standard will be published when the standard is established (expected December 2026).
What you can do now
Quality-Ready needs both diagnostic-tool measurement results and an operating guideline, so the highest state reachable today is Discoverable. Until the diagnostic tool’s release version is published, the procedure on this site alone cannot reach Quality-Ready. The current status of each action is as follows.
| Action | Now | Usable today · waiting for |
|---|---|---|
| Writing the manifest | Possible | Metadata elements · stage 1 checklist · catalog converter |
| Validating the manifest | Partly | Check by hand with the checklist · validator under review |
| Fixing defects · recording limitations | Possible | Fixing defects |
| Measuring quality · report | Waiting | After the diagnostic tool is released (date not set) |
| Quality-tier judgment | Waiting | Measurement results + a guideline. Organizations can build their own operating guideline |
| Preparing for a purpose | Waiting | After purpose criteria are registered (date not set) |
| Use by agents | Partly | Public Data Lens (MCP) · Fields and handling by judgment |
Schedule of the standard
Until establishment, this site explains the TTAK draft (v0.95) and the AIRD vocabulary (v0.10.5).
| When | What |
|---|---|
| 2026-03-09 | Drafting of Parts 1–3 began |
| 2026-05-13 | Parts 1–5 proposed to TTA (Telecommunications Technology Association) as a standard · under review at TTA regular meetings since then |
| December 2026 (expected) | Establishment of Parts 1–3 · release of the operating guideline provided by the standard · links to the specifications |
| During 2027 (planned) | Establishment of Part 4 (Transformation Pipeline and Governance) · Part 5 (Discovery, Exchange and Use) — follow-on parts |
Labels used across the site
Labels such as “follow-on”, “proposed”, “under review” and “in development” apply to every page.
Label meanings
| Label · topic | Meaning |
|---|---|
| follow-on | A citation of Part 4 or 5. Parts 4 · 5 are not included in the December 2026 establishment scope (Parts 1–3) and are expected to be enacted in 2027. |
| Proposed | A property proposed in a revision of the standard. It is not a current requirement. |
| Under review | A tool or material at the stage of deciding the scope and form of release. |
| In development | A tool or material being developed. The release date has not been set. |
| Results of the measurement engine (test version) | Values the site’s measurement engine computed on example files. The effect on real agents’ behavior and answer accuracy has not yet been measured. |
| Obligation | It is not an obligation under laws or regulations. Institutions and companies can cite this standard as a related standard in data management guidelines, project requirements or contract terms. |
| Explanation and specification | Requirements are set by the specification documents. Where this explanation and a specification differ, the specification prevails. |
Origins and progress
This section records, in date order, when the core decisions of the standard arose and from what problem. The 2025 entries carry over only concepts from proposals of that time, which are not the current standard.
Dated record
The source material for the 2025 entries was written and proposed by Haklae Kim (HIKE Lab, Chung-Ang University). Each entry also notes, under “Now”, how the current standard differs.
Defining the problem August–September 2025
2025-08 · Standards cover only metadata, not data values
The analysis split data into three layers: data values (Level 0), dataset metadata (Level 1), and service-level data (Level 2). International metadata standards apply to Level 1. Data values have no standard, which was judged to make linking data difficult.
Now: The standard includes both the record (Part 3) and quality measurement of data values (Part 2) — Quality indicators
2025-08 · From human-centered use to joint use by people and AI
The proposal divided the preparation process from data provision to AI use into six steps — cleansing · structuring · lineage · bias reduction · integration · accessibility — and was designed so that the results of preparation feed back into the provider’s quality management.
Now: Preparation has three stages — writing the manifest · measuring quality · preparing for a purpose — and each stage has a decision gate and outputs — Preparation overview
2025-08 · Proposed definition and maturity levels
The proposal defined AI-ready data as “data that AI can train on, reason over and use without further cleansing,” and proposed maturity levels rising from quality → training → generative AI → reasoning, with draft evaluation indicators for each level.
Now: The standard has no single maturity scale. It judges Diagnostic Maturity, quality tier and purpose tier separately and does not combine them — Judgment procedure
2025-09 · Current data compared with AI-ready data
The comparison used five axes: delivery format · quality management · quality criteria · intended users · portal functions.
| Axis | “Current data” as described in 2025 | “AI-ready data” as described in 2025 | Now |
|---|---|---|---|
| Delivery format | CSV · Excel · API | JSON · Parquet · RDF · API | Manifest and quality evidence take priority over format |
| Quality management | Metadata and some rules | All data values and semantic quality | Metadata recording and data value measurement in parallel |
| Quality criteria | No clear indicators | Managed indicators for accuracy · completeness · consistency | The standard sets measurement methods and the tier system; the operating guideline sets the threshold values |
| Intended users | Human-centered | Joint use by people and AI | Whether an agent can make judgments from the record alone |
| Portal functions | Mainly search · download | AI-oriented, such as Q&A and recommendation APIs | Outside the scope of the standard — the standard covers data and its record |
Numeric thresholds in the proposal of that time are not carried over. The standard does not set numeric thresholds. They are set by the threshold profile of the operating guideline.
Refining the definition October 2025
2025-10 · Structure · semantics · trust information
The definition was revised to “data prepared with machine-readable structure, semantics such as standard codes and relationship information, and trust information such as provenance, version and bias, so that AI can use it directly for training, reasoning and generation.”
Now: Made concrete as metadata elements and the discovery and understanding layers of the AIRD vocabulary (v0.10.5) — Metadata elements
2025-10 · From format-centered quality to semantic and value-centered quality
The proposal went beyond format checks such as date formats and missing values. It included the use of standard codes and the meaning of values in the scope of quality, and proposed alignment with international criteria (for example ISO/IEC 5259).
Now: 16 quality indicators and their correspondence with other standards — Quality indicators
Turning toward a standard November 2025
2025-11-03 · From guideline items to a standard vocabulary
A metadata proposal was put forward that made elements that directly support AI use (quality score · bias information · missing-value policy · preparation stage) required and administrative elements optional, and three follow-up tasks were recommended.
| November 2025 recommendation | Current standard · site |
|---|---|
| ① Refine the metadata specification and validation rules (valid values · format validation) | Metadata elements · Judgment procedure |
| ② Design an application model for domestic and international standard vocabularies (for example ISO/IEC 5259 · DCAT-AP-KR) | vocabulary v0.10.5 |
| ③ Develop a metadata vocabulary shared across domains | A scope that applies to any publisher · At a glance |
Standardization and public tools November 2025 onward
2026-03-09 · Drafting of Parts 1–3 of the AI-Ready Data draft standard begins
Drafting began on “AI-Ready Data – Part 1: Overview and framework,” “Part 2: Quality measurement and tiering” and “Part 3: Dataset description schema and application profile.” Transformation Pipeline and Governance (Part 4) and Discovery, Exchange and Use (Part 5) follow as follow-on parts.
Now: TTAK draft (v0.95), scope of establishment in December 2026 — What the standard does
2026-04-14 · Standard development tools released
While developing the standard, the implementation toolkit (aird-tools) was published in a public repository.
Now: Available tools and their status — Public tools
2026-05-13 · Proposed to TTA as a standard
Parts 1–5 were proposed to TTA (Telecommunications Technology Association) as a standard. Review has continued at TTA regular meetings since then.
Now: Under review — What the standard does
2026-08-03 · An MCP server that applies the draft standard
An MCP server (Public Data Lens) was released. It applies part of the draft standard’s judgments, as versioned rules, to the catalog metadata of the Korea Public Data Portal (data.go.kr).
Now: Available tools and their status — Public tools
2026-09-30 · AIRD vocabulary v0.10.5
The names, value ranges and obligation levels of metadata elements were fixed in the vocabulary.
Now: The reference vocabulary of this site — Metadata elements
2026-10 · Applies to any publisher
The policy of not limiting the standard’s scope and users to public-sector data was applied across the site. This follows the direction of November 2025 recommendation ③ (a vocabulary shared across domains).
Now: Data from public institutions, enterprises and non-profits is handled with the same procedure — At a glance
Next step: Preparation overview
Preparing data › Procedure
Overview
The procedure that makes your data usable by AI consists of a data check and three stages. You can carry out the data check and stage 1 on your own today; from stage 2 on, a diagnostic tool and an operating guideline are needed.
Stages and outputs
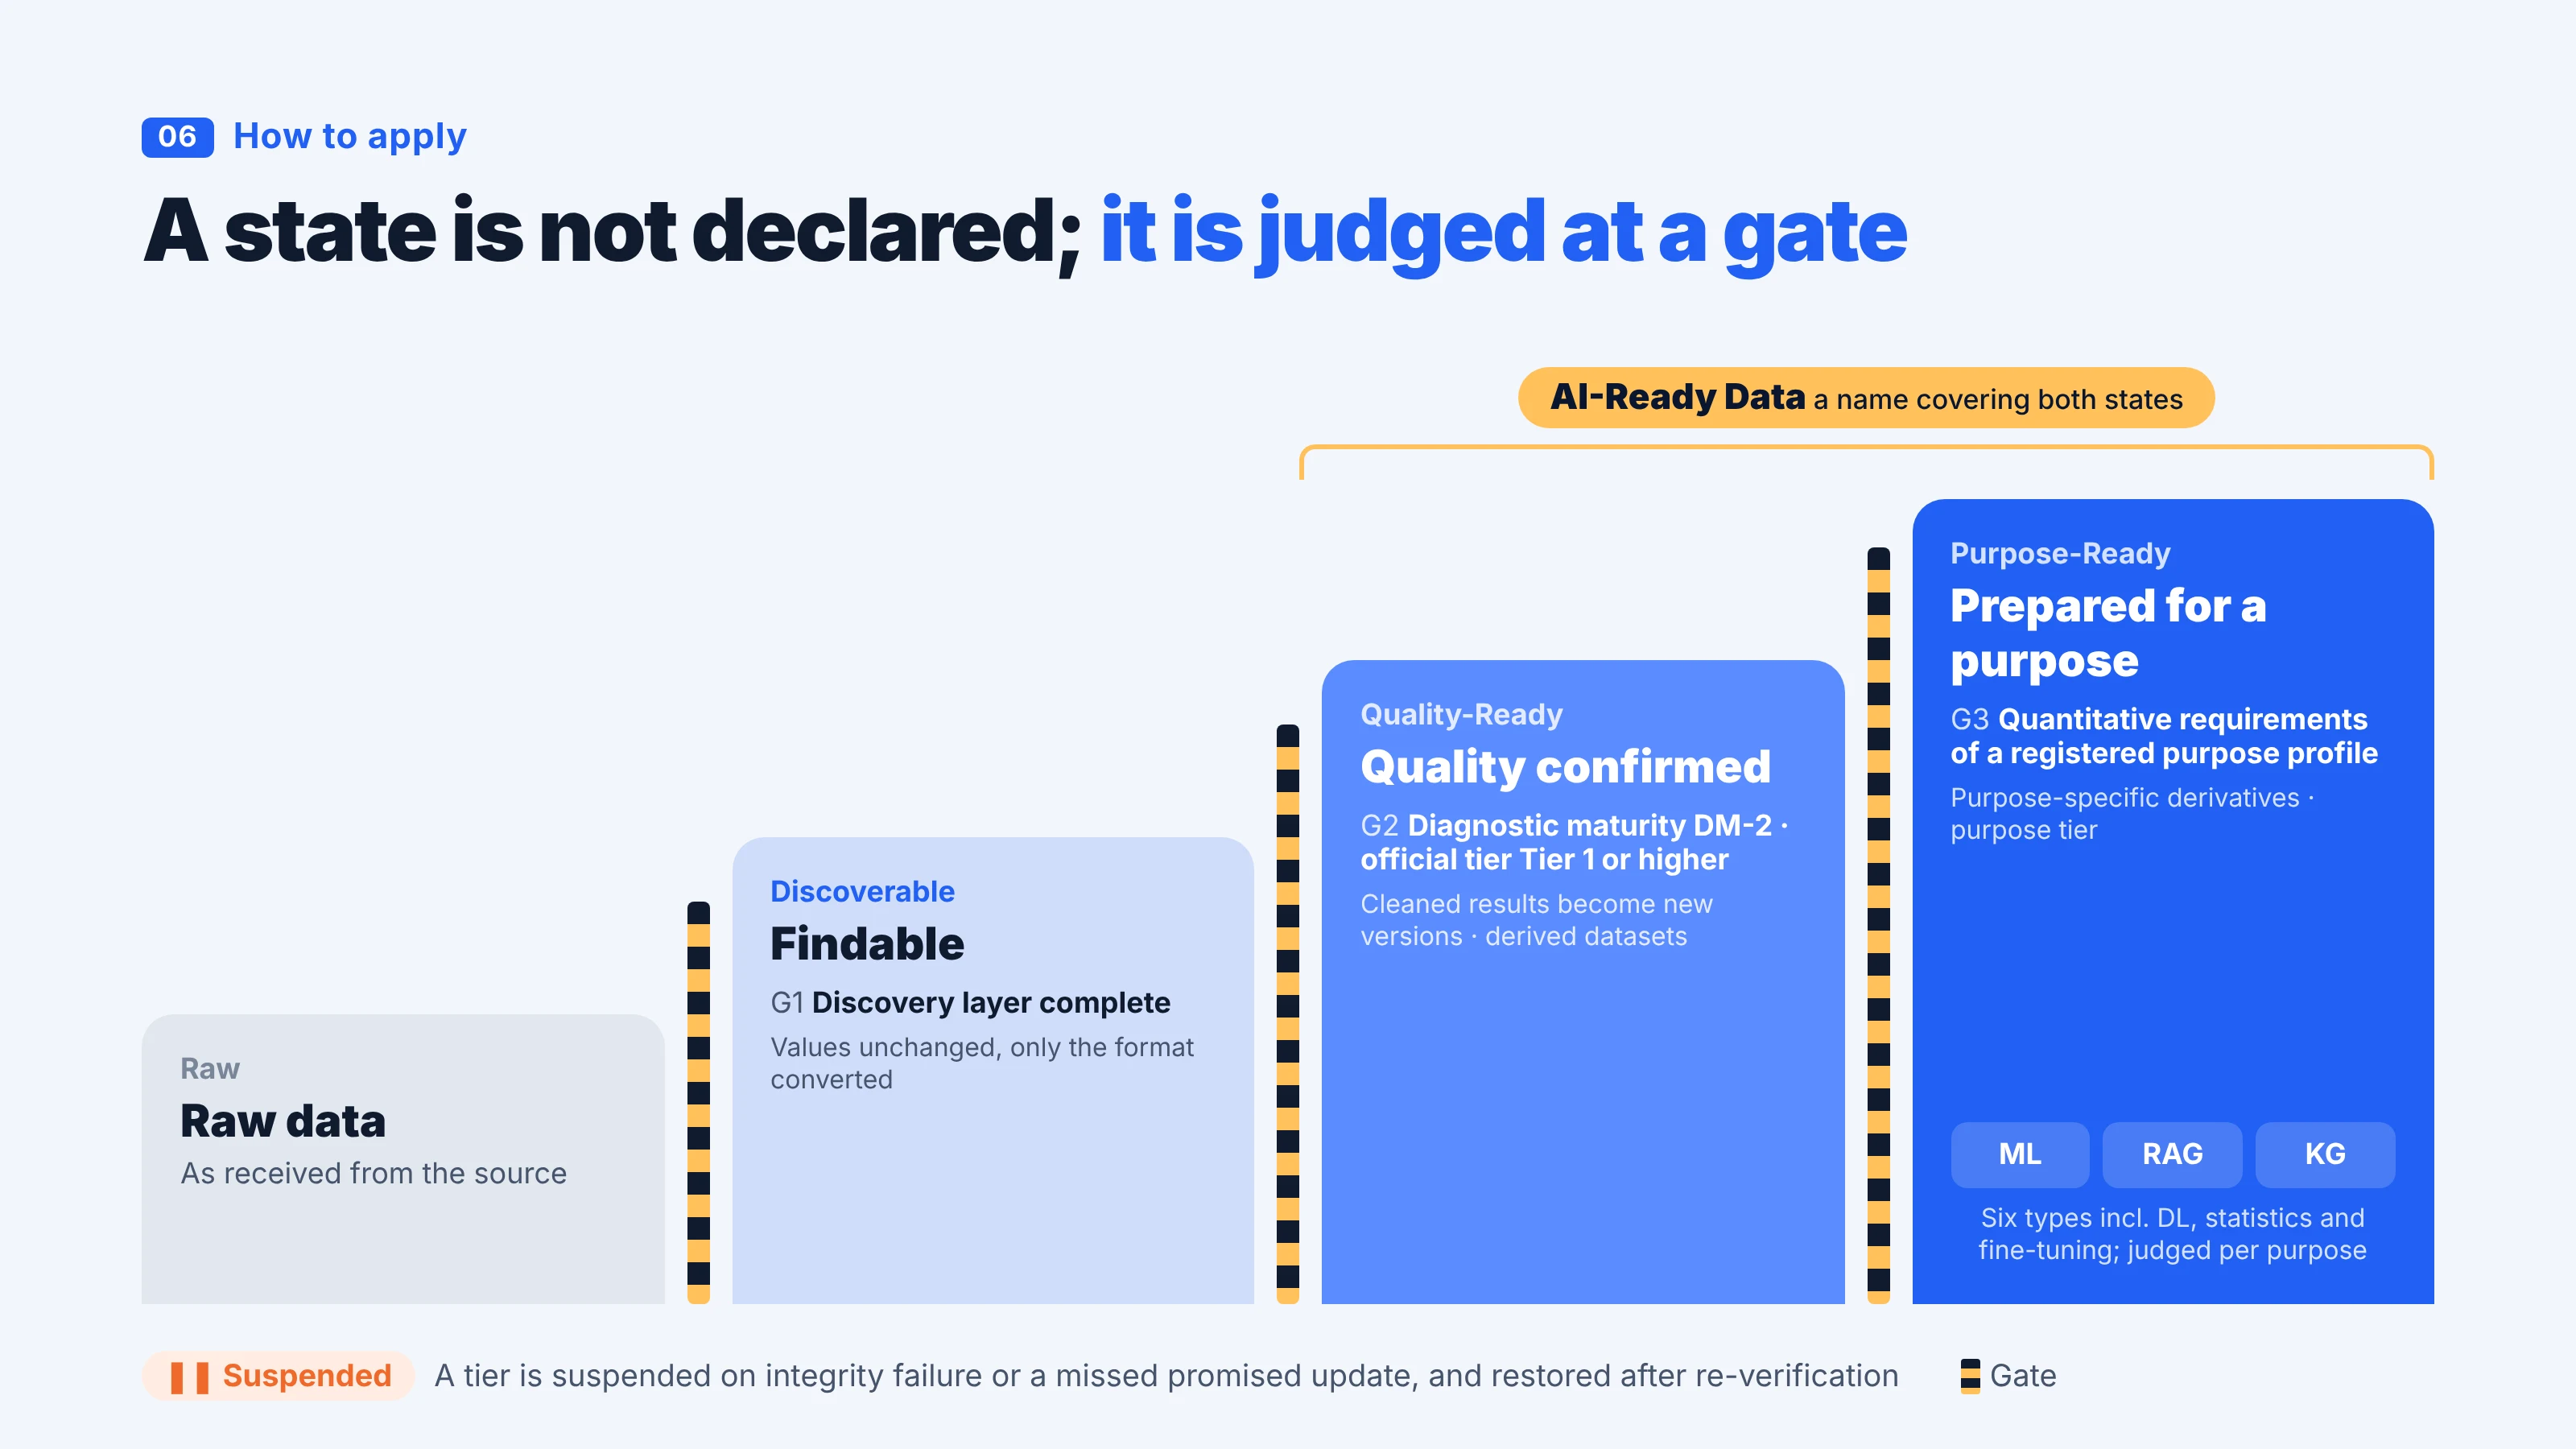
Each stage ends at a decision gate; passing it raises the data’s readiness state by one step. Items that do not pass are not failures but things to complete, so complete them and check again. In the standard, AI-ready data means data in the Quality-Ready or Purpose-Ready state that meets the common readiness requirements for AI use.
| Stage | What you do | Output | State reached |
|---|---|---|---|
| Data check | Check type, encoding, personal information | Check record | — |
| Stage 1 Writing the manifest | Write metadata elements, column schema, identifier | Manifest manifest.json | Discoverable |
| Stage 2 Measuring quality · fixing defects | Measure indicators, fix values, record limitations | Diagnostic report, cleaned data, processing history | Quality-Ready |
| Stage 3 Preparing for a purpose | Write an operation file per use purpose | Purpose-specific operation files | Purpose-Ready |
Keep the original alongside the cleaned data and follow the stages in order. You can carry out the stages separately; stage 1 alone already reduces what agents must guess. Data judged Quality-Ready or higher is distributed as a pack; before that, you publish the manifest.
Judgment conditions and output formats by stage
| State reached | Needed for the judgment | Output format |
|---|---|---|
| Discoverable | Required discovery-layer elements met | manifest.json (JSON-LD) — discovery layer and column schema |
| Quality-Ready | Diagnostic Maturity DM-2 and quality tier Tier 1 or higher, judged with the threshold profile of an operating guideline | Diagnostic report (JSON), cleaned data, processing history, limitation record, understanding layer of the manifest |
| Purpose-Ready | Purpose profile registered, required operation-layer items met | One operation file per purpose type |
A new manifest is issued for each version and points to the previous one. A pack consists of the manifest, diagnostic report, pack manifest and operation files; data files are referenced by address and checksum. The tier judgment is described in Judgment procedure.
Before and after preparation
Stage 1 does not change the content of values; it adds information about their meaning, format and source. Fixing defects at stage 2 may change values, and the target, method and reason are recorded in the processing history.
| Item | Before | After |
|---|---|---|
| Column meaning | Column names only | Name, data type, description, code values |
| Update frequency | “As needed” | URI from the standard list (e.g. …/frequency/IRREG) |
| Terms of use | “Third-party rights: N” | License value from the vocabulary (e.g. KOGL-1) |
| File information | None | Access URL, media type, file format, checksum |
| Quality | Unknown | Scores for 7 dimensions, Diagnostic Maturity, grounds |
| Limitations | None | Bias, unsuitable uses, causes of missing values |
| History | None | Change, date, reason |
What you can do now
You can carry out the data check, writing the manifest at stage 1 and computing checksums on your own. Decide the persistent identifier after checking your organization’s identifier policy.
Measuring quality and producing the diagnostic report at stage 2 need the diagnostic tool, whose release version is in development. Judging a quality tier needs an operating guideline. The guideline provided with the standard will be published when the standard is established (expected December 2026), and organizations may build their own. Today, therefore, the highest readiness state a data provider can reach is Discoverable. The schedule is in Current status and release plan.
For tabular (STRUCT) and time series (TSERIES) data, this guide goes down to action items. Text, image and instruction–response pair data follow the same procedure; type-specific items will be added in later versions.
Deciding where to start
For data that is already published, five questions decide the starting stage. The first “No” decides where you start; a later “Yes” counts only once the earlier questions are met. The questions are based on existing registration information, so if there is no manifest (manifest.json) yet, start at stage 1 even when every answer is “Yes”.
The questions and starting stages
- Do you provide the data in an open format such as CSV or JSON?
- Is there a document describing the meaning of each column (column schema)?
- Have you stated the reference time and update frequency?
- Are the terms of use recorded in a checkable form?
- Have you recorded missing values and limitations?
| First “No” | Starting stage |
|---|---|
| Question 1 or 2 | Writing the manifest (stage 1) — without an open format and column descriptions, quality cannot be measured |
| Question 3 or 4 | Metadata elements of stage 1 |
| Question 5 | Measuring quality (stage 2) — recording limitations is stage 2 work |
| None (all “Yes”) | Measuring quality (stage 2) if a manifest (manifest.json) exists; otherwise writing the manifest (stage 1) |
A “No” does not mean the provider made a mistake. Existing portal registration screens had no fields for some of the 23 elements and did not support machine-readable formats.
Materials to prepare
Before you start, gather the data file, the current registration information, column descriptions, the actual update history and the terms of use. If some are missing, begin with the elements you can write.
Where to find each material
| Material | Where to look | If missing |
|---|---|---|
| Data file | Source system, portal registration, internal data catalog | Start with the stage 1 elements |
| Current registration | Portal registration screen for public data; internal catalog or marketplace listing for enterprise data | Write new |
| Column descriptions | Column comments in the source database | Write them at stage 1 |
| Update frequency | Actual update history | Check the actual frequency first |
| Terms of use | The institution’s open-data policy for public data; terms of use and license documents (with effective date) for enterprise data | Ask the responsible department |
Requirement labels used on this site
| Label | Meaning |
|---|---|
| Required | Required by the current draft standard |
| Threshold | Set by an operating guideline (threshold profile) |
| Recommended | Recommended by this site for convenience; not a requirement of the draft standard |
| Example | A value or wording for illustration |
The Preparing data pages state these labels in words: “must” means required, “recommended” means recommended. The obligation level “recommended” (required · recommended · optional) is used only for the levels set in the vocabulary.
Completion check
- Starting stage decided (stage 1 or 2)
- Availability of the five materials checked
Next step: Checking your data
Basis: Part 1 3.1, 3.15, 5.1, 5.2, 5.5 · Part 3 5.1
Preparing data › Procedure
Checking your data
Before starting stage 1, check the data type, whether the character encoding is UTF-8, and whether the data contains personal information. This takes about 10 minutes.
1. Determine the data type
The data type decides which indicators are measured and which elements go into the manifest, so determine it first. Most administrative and business data is tabular (STRUCT), with rows and columns. Tables that accumulate over time, such as sensor readings or daily prices, are time series (TSERIES); for these, recording the reference time, measurement interval and unit is recommended.
| Example data | Type |
|---|---|
| Business registrations, permit lists, transaction records | Tabular STRUCT |
| Equipment sensor readings, daily prices | Time series TSERIES |
| Replies to civil complaints, notice texts, reports | Text TEXT |
| Facility inspection photos, satellite images | Image IMAGE |
| Consultation question–answer pairs | Instruction–response pairs PT |
If one file mixes several types, choose one representative type and also check the items for the other types. The chosen type is recorded at stage 2 in the diagnostic report and the manifest’s data type (aird:dataType).
Number of indicators by type
The number of indicators that must be measured (formally required indicators) differs by type. Of the 16 quality indicators, STRUCT has 13, TSERIES 13, TEXT 5, PT 8 and IMAGE 3. Diagnostic Maturity reaches DM-2 only when all formally required indicators are measured.
Every type measures at least the minimum measurement indicators (MMI): D5-03 (statistical plausibility), D6-01 (uniqueness), D7-01 (encoding consistency) and D7-02 (technical validity), limited to those that apply to the type.
Without reference data to compare against, accuracy indicators remain “accuracy not measured”. This is a measurement state, not a penalty. If an accuracy indicator is formally required for the type, however, Diagnostic Maturity cannot reach DM-2, so reference data is needed before the transition to Quality-Ready.
Indicator definitions are in Quality indicators; the rules for Diagnostic Maturity are in Judgment procedure. Action items for text, image and instruction–response pair data will be added in a later version.
2. Check the encoding
The reference encoding is UTF-8. Files saved in CP949 or EUC-KR are judged non-conforming, so convert them to UTF-8 at this step.
- Check: run
file -i filenamein a terminal (on macOS,file -I filename). If the result ischarset=utf-8orus-ascii, no conversion is needed. - Convert: save the file again as UTF-8 in an editor, or run the following command.
iconv -f CP949 -t UTF-8 original > converted
BOMs and line-ending characters need no adjustment. If your organization has set a different encoding rule, follow it and record the rule in the manifest.
3. Check for personal information
If the data contains no personal or pseudonymized information, proceed to stage 1. If it does, do not decide alone; check the following with the privacy officer and the responsible department.
- Purpose of processing and legal basis
- Scope of access rights
- Safeguards applied
- Whether the data may be published
Completing pseudonymization does not mean the data may be published, and restricted publication does not mean the data cannot be prepared. This procedure covers data provided publicly; whether restricted data can be prepared in a controlled environment is decided separately by the organization.
A dataset containing personal information must record its de-identification level (aird:deidentificationLevel) in the stage 1 manifest. Whether it contains personal information (aird:containsPersonalData) and the method and date of processing are recorded in the understanding layer at stage 2.
See also: Personal Information Protection Commission, “Guidelines on Processing Pseudonymized Information” (March 2026). Public institutions should also check the “Public AX Privacy Guide” (July 2026).
Completion check
- Data type determined and check record written
- UTF-8 conformance checked, converted if needed
- Presence of personal information checked
Next step: Writing the manifest (stage 1)
Basis: Part 1 5.6 Table 5-5 · Part 2 7.4, 8.1, 8.2, Annex A.1, A.2, A.4 · Part 3 Annex A.1
Preparing data › Procedure
Writing the manifest (stage 1)
Contents
ContentsThe manifest is a file that records, in machine-readable JSON-LD, what the data is, where it is and under what conditions it may be used. At stage 1 you write the metadata elements and the column schema to produce manifest.json; this file is the basis for the data reaching the Discoverable state.
1. Write the metadata elements
There are 23 elements: 19 for the dataset and 4 for each distributed file. Public data fills in all 23. For other data, theme and landing page are recommended, so 21 are required. If there are several files, fill in the 4 distribution elements for each file. A dataset containing personal information also records its de-identification level (aird:deidentificationLevel; conditionally required).
Elements with a fixed value list, such as update frequency, license and language, take a value from the list instead of free text. License, terms of use, the publication scope of personal information and the identifier policy are decided by the organization, so check them with the responsible department.
Stage 1 checklist — tick the 23 elements
Stage 1 checklist — 23 metadata elements (demo profile)
0 / 23 filled
Dataset
Distribution (per file)
Checkbox states are saved only in this browser. Source: AIRD vocabulary v0.10.5 demo profile.
Value lists (main elements)
| Element | Values |
|---|---|
Lifecycle status aird:lifecycleStatus | Discoverable · Quality-Ready · Purpose-Ready · Stale — Discoverable at stage 1 |
Creation method aird:creationMethod | collected · processed · synthetic · augmented |
Update frequency dct:accrualPeriodicity | ANNUAL · QUARTERLY · MONTHLY · DAILY · IRREG (irregular) and others (EU Frequency list) |
License dct:license | KOGL-0–KOGL-4 · KOGL-AI · NO-RESTRICTION · six CC licenses such as CC-BY-4.0 · CC0-1.0 (14 values of kr-license) |
Access rights dct:accessRights | PUBLIC · RESTRICTED · NON_PUBLIC |
Language dct:language | KOR · ENG and others (EU Language list) |
Media type dcat:mediaType | text/csv · application/json · image/jpeg and others (IANA) |
The manifest records the concept URI of each value; for example, ANNUAL is written as http://publications.europa.eu/resource/authority/frequency/ANNUAL. Values for service type, dataset structure type and theme, and the full concept URIs, are in Metadata elements. If a license is not on the list, such as a company’s own terms of use, write the name and effective date of the terms in terms of use (dct:rights).
Elements often missed or mis-filled
| Element | Rule | Common error |
|---|---|---|
| Persistent identifier | A permanent value that never changes; a resolvable URI, different from the access URL | An internal number used as is |
| Keywords | Three or more | Only one or two |
| Update frequency | URI from the standard list | Free text such as “quarterly” or “as needed” |
| License | One of the 14 kr-license values | A sentence such as “Third-party rights: N” |
| Media type | IANA notation such as text/csv | “Text” or “Image” |
| Checksum | SHA-256 for each file | Missing |
| Access URL | The actual location of this data’s file | Copied from another manifest without changing the URL — not caught by format checks |
The 23 elements follow the demo profile of vocabulary v0.10.5. The draft standard requires 19 (15 for the dataset, 4 for distributions); the demo profile adds dataset structure type, theme, landing page and maintaining department.
2. Write the manifest
Record the elements in JSON-LD. Replace the <…> parts of the skeleton below with your values and save it as manifest.json. Once the diagnostic tool is released, you can also edit the draft it produces.
manifest.json skeleton (23 elements)
{
  "@context": "https://datahub.kr/ns/aird-context-3.0.jsonld",
  "@id": "<dataset identifier>/manifest/1.0.0",
  "@type": "dcat:Dataset",
  "dct:identifier": "<dataset identifier — see Choosing persistent identifiers>",
  "dct:title": "<title>",
  "dct:description": "<description>",
  "dcat:version": "1.0.0",
  "dcat:keyword": ["<keyword1>", "<keyword2>", "<keyword3>"],
  "dct:type": [
    "http://vocab.datahub.kr/def/dcat-ap-kr/service-type/FILE",
    "http://vocab.datahub.kr/def/aird/dataset-type/Structured"
  ],
  "dct:language": ["http://publications.europa.eu/resource/authority/language/KOR"],
  "aird:lifecycleStatus": "http://vocab.datahub.kr/def/aird/lifecycle-status/Discoverable",
  "dcat:theme": ["http://vocab.datahub.kr/def/dcat-ap-kr/data-theme/<theme>"],
  "dcat:landingPage": "<data detail page URL>",
  "dct:creator": ["<creator URI or organization name>"],
  "dct:publisher": "<publisher URI or organization name>",
  "dcatkr:maintainer": { "@type": "foaf:Agent", "foaf:name": "<maintaining department>" },
  "dcat:contactPoint": { "@type": "vcard:Contact", "vcard:fn": "<name>", "vcard:hasEmail": "mailto:<email>" },
  "aird:creationMethod": "http://vocab.datahub.kr/def/aird/creation-method/collected",
  "dct:accrualPeriodicity": "http://publications.europa.eu/resource/authority/frequency/ANNUAL",
  "dct:license": "http://vocab.datahub.kr/def/dcat-ap-kr/license/KOGL-1",
  "dct:rights": "<notice on the scope of use>",
  "dct:accessRights": "http://publications.europa.eu/resource/authority/access-right/PUBLIC",
  "csvw:tableSchema": {
    "columns": [
      { "name": "<column name>", "datatype": "string", "dc:description": "<description>", "required": true },
      { "name": "<numeric column>", "datatype": { "base": "integer", "minimum": 0, "maximum": 100000 }, "dc:description": "<description and unit>" },
      { "name": "<code column>", "datatype": "string", "dc:description": "<code table and edition>. 01=open, 02=suspended, 03=closed" }
    ],
    "primaryKey": "<record key column>"
  },
  "dcat:distribution": [{
    "@type": "dcat:Distribution",
    "dcat:accessURL": "<file URL>",
    "dcat:mediaType": "text/csv",
    "dct:format": "http://publications.europa.eu/resource/authority/file-type/CSV",
    "spdx:checksum": { "spdx:algorithm": "SHA-256", "spdx:checksumValue": "<SHA-256 value>" }
  }]
}
- Checksum: compute it with
sha256sum filenameon Linux orshasum -a 256 filenameon macOS. - Syntax check: run
python3 -m json.tool manifest.jsonand confirm there are no errors. The manifest validator is under review, so check that the elements are met by opening the “Stage 1 checklist” in section 1.
Put the finished manifest at a public address where users and agents can download it; for public data, link it from the portal detail page (landing page). For now, check whether the stage 1 decision gate (G1) is met with the checklist; the G1 judgment record is written by the diagnostic tool. A complete example with values is in Manifest example. A new manifest is issued for each version and points to the previous one with dcat:previousVersion.
3. Write the column schema
Tabular data must have a column schema (csvw:tableSchema). Column descriptions in the source database are often lost when exported to CSV, and a name such as mkt_nm alone does not tell what the values mean. For each column, record the name, data type, description and whether it is required, and the meaning of each code value if there are codes.
Value ranges, cross-field relations, derivation rules and code tables with their editions are recommended by this site, but they are inputs to measurement at stage 2. Without them the diagnostic tool cannot measure the related indicators and records the reason in the report. Value ranges are used for measurement only when written as the data type’s minimum and maximum (minimum, maximum), not in the description text, as in the numeric column of the skeleton. There is currently no dedicated property for code meanings, so write them in the column description, and put the column that identifies a record (record key) in primaryKey. The column schema can also be kept as a separate document that the manifest points to by address and hash.
Column items and related indicators
| Item | Status | Example | Indicator that uses it |
|---|---|---|---|
| Name | Required | bizr_no | — |
| Data type | Required | string | — |
| Description | Required | Business registration number issued by the National Tax Service, without hyphens | — |
| Required or not | Required | Required (must not be empty) | D1-01 required field completeness |
| Value range | Recommended | employeeCount 0 to 100000 | D5-02 numeric range validity |
| Cross-field relation | Recommended | If closed is 1, a closing date exists | D2-01 cross-field consistency |
| Derivation rule | Recommended | Total = male + female | D2-03 derived value accuracy |
| Code table and edition | Recommended | Korean Standard Industrial Classification (revision stated); 01=open · 02=suspended · 03=closed | D2-02 referential integrity |
| Display name · unit | Recommended | Business registration number · KRW · ㎡ · ℃ | — |
| Empty-value notation | Recommended | Empty cell | — |
Empty-value notation is not a requirement of the standard, but use one notation. Mixing empty cells, -, N/A and 0 makes it impossible to tell a real 0 from a missing value.
4. Tidy the file format
Convert formats that open only in a specific program to open formats. CSV (UTF-8) is recommended for tables, with Parquet alongside for large files. Remove merged cells, subtotal rows and multi-row headers, and split workbooks that hold several tables into one file per table. Format conversion and table tidying change only the container, not the content of the values.
Recommended formats by kind of data
| Kind of data | Recommended format | Reason |
|---|---|---|
| Tabular | CSV (UTF-8) | Readable by general tools |
| Tabular, large | Parquet alongside | Faster download and processing |
| Hierarchical data | JSON | Flattening loses the hierarchy |
| Geographic data | GeoJSON | Includes the coordinate system |
| Documents | Original format + extracted text | The original alone is not machine-readable |
| Images | Standard image formats | Proprietary formats are unreadable by general tools |
Image labels, train/validation splits, instruction–response pairing and document chunking are not stage 1 requirements. Unlabelled photos can also be Discoverable.
Completion check
- Metadata elements written (23 for public data, at least 21 otherwise)
- Name, data type, description and required flag recorded for each column
- Checksum recorded for each file
manifest.jsonsyntax checked
Next step: Choosing persistent identifiers — decide the value of the dataset identifier.
Basis: Part 1 5.2 · Part 3 5.1, Annex A.1, A.2 · vocabulary v0.10.5 demo profile
Preparing data › Procedure
Choosing persistent identifiers
The dataset identifier (dct:identifier) is a permanent value that points to the dataset; once set, it does not change. Check your organization’s identifier policy first; if there is none, decide the URI with the interim rules on this page.
1. Check how to decide
If the organization has an issuing policy, apply it. If not, and the organization controls a domain, set a fixed path under that domain; if there is no domain either, check whether a parent organization or a common namespace can be used.
| Situation | Decision |
|---|---|
| Organization has a policy | Apply the policy (takes precedence over the interim rules) |
| No policy · organization domain exists | https://data.<organization domain>/id/dataset/<name> |
| No policy · no domain | Check a parent organization (parent agency, group company) or a common namespace |
| None of these | Assign an identifier that is guaranteed unique, and record that it does not resolve as a limitation |
Do not leave the identifier empty; without it, the stage 1 decision gate cannot be passed.
2. Write the identifier
An identifier consists of a fixed namespace controlled by the organization and a dataset name. Leave out anything that changes over time, such as version, year, file format or department name, and record these in the version (dcat:version), temporal coverage and file format (dct:format) elements. A meaningless serial number can serve as the dataset name.
https://data.example.go.kr/id/dataset/biz-registry
└──────── namespace ──────────┘└ dataset name ┘
Portal listing keys and portal detail-page URLs change when data is re-registered, so do not use them as identifiers. Put the portal detail-page URL in the landing page (dcat:landingPage) and the download URL in the access URL (dcat:accessURL). The persistent identifier, landing page and access URL are three different values.
Suitable and unsuitable examples
| Judgment | Value | Reason |
|---|---|---|
| Suitable | https://data.example.go.kr/id/dataset/biz-registry | Fixed namespace · stable name |
| Suitable | https://data.example.go.kr/id/dataset/d-00417 | Meaningless serial number |
| Suitable | https://data.example.com/id/dataset/sales-daily | Fixed path under a company domain |
| Unsuitable | https://data.example.go.kr/file/biz_2025_v3.csv | Contains year, version, format. Belongs in the access URL |
| Unsuitable | BIZ-2025-001 | Not a URI · contains a year |
| Unsuitable | 15029008 | Portal listing key · changes on re-registration |
| Unsuitable | https://www.data.go.kr/data/15029008/fileData.do | Portal detail page. Belongs in the landing page |
| Unsuitable | https://market.example.com/products/48213 | Marketplace product page. Belongs in the landing page |
3. Keep the identifier
Changing an identifier breaks every reference to the data, so keep it when you clean values, issue a new version or add a file format. When data is re-registered or moved, update only the landing page and access URL. Purpose-specific operation files also use the original dataset’s identifier. Only when datasets are merged or split do you treat the result as a different dataset with a new identifier.
What to pass on when requesting a policy
- Whether the organization controls a domain — to decide the namespace
- Whether the domain is guaranteed to be maintained — for persistence
- Whether an existing dataset numbering scheme exists — to reflect it in the URI path
- Who issues and retires identifiers — to prevent duplicates
The rules on this page are interim rules. Once the organization’s policy or higher-level guidance exists, it takes precedence, and identifiers already assigned are kept.
Completion check
- Dataset identifier decided as a URI
- No year, version, file format, department name or portal listing key in it
- Identifier, landing page and access URL are different values
Next step: write the identifier into the manifest’s dct:identifier, finish the completion check of Writing the manifest, then go on to Measuring quality and the diagnostic report (stage 2).
Basis: Part 3 Annex A.1 · the interim rules are this site’s recommendation
Preparing data › Procedure
Measuring quality and the diagnostic report (stage 2)
Contents
ContentsAt stage 2 the diagnostic tool measures the quality indicators and produces a diagnostic report. You prepare the materials measurement needs and read Diagnostic Maturity and the reasons for unmeasured indicators in the report. The release version of the diagnostic tool is in development, so to learn how to read a report, refer to the reports of the public data examples.
1. Prepare the inputs
How many indicators can be measured depends on the data type and the materials you provide. The tabular example file had 6 of 13 formally required indicators measured from the file alone, and 7 after the stage 1 manifest was added. The rest need external materials, so prepare those that apply to your data in advance.
- The data file and the stage 1 manifest (with column schema)
- Code tables and their editions
- Reference time and update history
- Value ranges per column and cross-field rules
The diagnostic tool computes scores and Diagnostic Maturity; you do not apply the formulas yourself. Results stage by stage are in Walkthrough with example data.
2. Scores are not tiers
The standard measures quality with 16 indicators in 7 dimensions: completeness (D1), consistency (D2), accuracy (D3), timeliness (D4), validity (D5), uniqueness (D6) and machine readability (D7). If the file cannot be opened, the other dimensions cannot be measured, so the tool checks machine readability first.
Scores and quality tiers are different values. The tool computes indicator and dimension scores; the quality tier is judged with the threshold profile of an operating guideline. The judgment starts from the lowest of the 7 dimension scores, not the average, and the same scores can lead to different tiers under different guidelines. A report without an operating guideline records the quality tier as “not judged: no operating guideline applied”.
Measurement results without an operating guideline
Results measured without a guideline are still valid baseline material, so keep the scores and reasons. When a guideline is applied, indicators whose measurement depends on it (for example, the dummy-value patterns of D5-03) are measured again and a new report is issued.
The example threshold profile in Part 2 Appendix I has the status EXAMPLE; it is used only for provisional calculation and tool development, never for tier judgments. The guideline provided with the standard will be published when the standard is established (expected December 2026), and organizations can build their own. How the same scores become different tiers under different thresholds is shown in the simulation in Building an operating guideline.
Definitions and formulas of the 16 indicators are in Quality indicators; actions for low scores are in Fixing defects.
3. Check Diagnostic Maturity
Separately from scores, the report records Diagnostic Maturity (DM): how far the required indicators were measured. It reaches DM-2 only when all formally required indicators for the type are measured. Even with a guideline applied, below DM-2 the quality tier is “not judged: below DM-2”, whatever the scores. If the file is empty (0 records) or broken and cannot be opened, both Diagnostic Maturity and the tier are recorded as not judged.
Without an operating guideline, the tool measures D5-03 (statistical plausibility), one of the minimum measurement indicators, provisionally with the example patterns of Part 2 Appendix I and records the assessment status as PROVISIONAL. The tabular and time series data in the example file and public data examples are DM-0 (provisional), because some formally required indicators could not be measured without external materials such as code tables.
The five applicability values and what to do
| Applicability | Meaning | What to do |
|---|---|---|
APPLIED | Measured; score recorded | Nothing |
PARTIALLY_APPLIED | Only targets with reference data measured; no score (null) | Obtain reference data for the rest |
PRECONDITION_UNMET | Not measured for lack of reference data (e.g. a code table) | Obtain it and remeasure |
NOT_APPLICABLE | Does not apply to the type or condition; not a gap | Nothing |
OPTIONAL_SKIPPED | Optional indicator not measured | Nothing |
A single PARTIALLY_APPLIED among the required indicators rules out DM-2. The decision table rows are in Judgment procedure; all status values are in Status and judgment values.
Diagnostic Maturity of the public data examples
| Example | Required indicators measured (cleaned) | Diagnostic Maturity | Remaining cause |
|---|---|---|---|
STRUCT × KG | 11 / 13 | DM-0 (provisional) | 2 not measured — code tables not obtained (D2-02 partially measured) and 1 other |
TSERIES × Stats | 10 / 13 | DM-0 (provisional) | 3 not measured |
TEXT × RAG | 5 / 5 | DM-2 | None |
PT × FineTuning | 7 / 8 | DM-0 | D3-02 (label accuracy) — expert review results needed |
D5-03 does not apply to text, so the text example measured all 5 required indicators and reached DM-2 without a guideline. Images (IMAGE) also need expert review for D3-02. DM-1 depends on whether measurement coverage meets the guideline’s lower bound, so without a guideline it is not judged.
4. Read the report
When you receive a report, check Diagnostic Maturity first; below DM-2, check which indicators were not measured and why. Next, find the lowest dimension score — that dimension is what to fix. The weighted average is for reference and not used for tier judgments. If a tier is given, check the identifier and version of the operating guideline applied.
Sort unmeasured indicators into three types by what they need.
- Do now: work that needs nothing extra, such as setting a record key or entering elements
- After obtaining materials: with code tables, D2-02 (referential integrity) and D3-01 (standard name consistency) can be measured
- Outside the provider’s scope: tier judgment after an operating guideline is applied; record the reason and wait
The six values in a report
| Value | Question it answers | Form |
|---|---|---|
| Applicability | Was the indicator measured? | Five values such as APPLIED |
| Indicator score | What is the measured value? | 0 to 1 |
| Reason not measured | Why was it not measured? | A sentence recorded with the applicability value |
| Diagnostic Maturity | How far were the required indicators measured? | DM-0 · DM-1 · DM-2 · not judged |
| Quality tier | What level is the measured quality? | Tier 0–4 · not judged (needs a guideline) |
| Readiness state | What state is the data in? | Discoverable · Quality-Ready · Purpose-Ready |
Quality tier and readiness state
All four public data examples have the quality tier “not judged: no operating guideline applied”, including the text example at DM-2. This site does not assign tiers with the example threshold profile. An organization that judges a tier with its own guideline records the guideline’s identifier and version with the tier and publishes the guideline.
The transition to Quality-Ready requires all three: Diagnostic Maturity DM-2, an operating guideline applied, and quality tier Tier 1 or higher. The four examples are therefore Discoverable.
Completion check
- Materials for measurement prepared
- Diagnostic Maturity and reasons for unmeasured indicators checked
- Unmeasured indicators sorted into three types
Next step: Fixing defects (stage 2)
Basis: Part 1 5.1, 5.2 · Part 2 5.1, 5.2, 7.3, 8.1, Annex A.4.1, B.2, B.5 Table B.4, Appendix I
Preparing data › Procedure
Fixing defects (stage 2)
Contents
ContentsOnce the diagnostic report shows indicators with low scores, fix the values you can fix in a cleaned copy and record the limitations you cannot fix. Do not overwrite the original file; keep it separate from the cleaned data and the report.
1. Fix values
Start with the dimension that has the lowest score, because the tier judgment starts from the lowest dimension score. Most work consists of unifying column names and notation, aligning values with identifiers, classifications and standard codes, and adding measurement results and limitations to the manifest.
| Low-scoring dimension | First action |
|---|---|
| Completeness (D1) | Check empty values in key columns. If they cannot be filled, unify the empty-value notation and record the fact |
| Consistency (D2) | Check for different names for the same concept; unify date and code notation |
| Accuracy (D3) | Compare with source records. Without reference data, leave it as “accuracy not measured” and record why |
| Timeliness (D4) | Align the stated update frequency with the actual update history; state only a frequency you can keep |
| Validity (D5) | Define data type, allowed-value and required-value rules and find violating rows |
| Uniqueness (D6) | Define a record key; without one, record-level duplicate detection is uncertain |
| Machine readability (D7) | If not tidied at stage 1, convert to an open format and remove merged cells, subtotal rows and multi-row headers |
Record each change, its date, the version change and the reason in the processing history; without it, users cannot verify the cleaning. For example: “2026-08-14, filled missing district values, original v1.0.0 → cleaned v1.1.0”.
2. Record limitations
Limitations that cannot be fixed must be recorded. Users decide whether and how far to use the data based on recorded limitations, and constraints that are not recorded cannot be seen. A limitation record is not a defect judgment but information for judging the scope of use.
- Known bias: nationwide in scope, but over 90% of records are from the capital region
- Unsuitable use: based on resident registration, so unsuitable for analysing the population actually present
- Causes of missing values: sensor maintenance (2.1%) and communication errors (1.1%)
- Reason not measured: no source records to compare, so accuracy not measured
3. Manage files and remeasure
Cleaned data is not a different dataset, so it keeps the persistent identifier; it is distinguished from the original by its distribution and SHA-256 checksum. After cleaning or remeasuring, produce a new diagnostic report and issue a new manifest version that points to it by address and checksum. Remeasuring cleaned data requires the diagnostic tool, whose release version is in development.
How each file is distinguished, and when a report can be reused
| What | Distinguished by |
|---|---|
| Original and cleaned files | Distribution and SHA-256 checksum |
| Released version | Version number |
| Manifest | A new one per version, pointing to the previous one |
| Diagnostic report | A new one for each measurement |
| Operation files | A separate file per purpose type |
An existing report is reused only when the measured version, the measurement rules, the operating guideline applied and the validity of the measurement time are all the same.
Common errors
| Wrong | Right |
|---|---|
| Summarizing dimension scores as a weighted average of 0.925 and judging the tier | Start the candidate tier from the lowest dimension score (D4 0.86); an average dilutes a low dimension |
| Publishing a tier computed with the example threshold profile without an operating guideline | Record scores and Diagnostic Maturity only; quality tier is “not judged: no operating guideline applied” |
| Keeping the old report after cleaning | Produce a new report and update the manifest to point to it |
Quality scores and tiers are requirements the standard adds for AI use; the international FAIR principles do not require them.
Completion check
- Cleaned data produced and processing history recorded
- Unfixable limitations recorded
- Original kept (a different file and checksum from the cleaned data)
Next step: Packaging and distribution
Basis: Part 3 5.1
Preparing data › Procedure
Packaging and distribution
Contents
ContentsA pack is the unit for distributing prepared data, assembled from Quality-Ready onwards. The manifest points to the diagnostic report and operation files by address and SHA-256 hash; the data files themselves are not put in the pack. At the Discoverable state you publish the manifest instead of a pack.
1. Principles
The dataset is the thing described (the entity) and the manifest is the document that describes it, so their identifiers differ. The manifest points to the report, operation files and data files by address and hash, and summarizes some report values in the understanding layer. The report is the original of the quality judgment; if a summary value differs from the report, the report prevails and validation fails.
The file layout and bundle format of a pack are set by the operating guideline. The guideline provided with the standard will be published when the standard is established (expected December 2026); all file names and addresses on this page are examples.
2. Files needed by readiness state
Each higher state adds new items to the files and coverage of the state below. Choose a state below to see the files it needs, and choose a file to see its basis in the standard and how it points to other files.
Choose a state to highlight only the files that state requires. Choose a file to see its basis in the standard and how it points to other files. All file names · addresses · hashes · scores are fictional values for illustration.
As a table
| Readiness state | Files needed | Transition judgment |
|---|---|---|
| Discoverable | One manifest (plus the column schema if kept as a separate document) | Decision gate ① (G1) — required discovery-layer elements met |
| Quality-Ready | Manifest · diagnostic report · pack manifest | Decision gate ② (G2) — Diagnostic Maturity DM-2, tier Tier 1 or higher under an operating guideline |
| Purpose-Ready | Quality-Ready pack + one operation file per purpose type | Decision gate ③ (G3) — required operation-layer items of a registered purpose profile met |
Report values and their summary elements in the manifest
The summarized items are set by Part 2 Table 9-2. The manifest properties are the quality assessment (aird:QualityAssessment) elements of vocabulary v0.10.5; this mapping does not appear in the body of the draft standard. The example tier applies a fictitious organizational guideline.
| Part 2 Table 9-2 item | Report key | Manifest property | Example |
|---|---|---|---|
| Minimum dimension score | qualityIndex.minDimensionScore | aird:qualityIndexMin | 0.82 |
| Weighted average | qualityIndex.weightedAverage | aird:qualityIndexAvg | 0.91 |
| MMI score | qualityIndex.mmiScore | aird:qualityIndexMMI | 1.0 |
| Quality tier and label | qTier.tier · qTier.label | aird:qualityTier · aird:qualityTierLabel | Tier2 · Silver |
| Diagnostic Maturity | diagnosticMaturity | aird:diagnosticMaturity | DM-2 |
| Data type | dataType | aird:dataType | STRUCT |
| Diagnosis time | generatedAt | prov:generatedAtTime | 2026-…T…+09:00 |
| Threshold profile identification | thresholdProfile | aird:thresholdProfile | identifier · 1.0 · hash · OFFICIAL |
| Rule and schema versions | diagnosticInfo.ruleVersion · schemaVersion | aird:ruleVersion · aird:schemaVersion | … |
| Transition eligibility | qTier.qualityReadyEligible | aird:qualityReadyEligible | true |
3. Validate before distribution
Every file a pack contains or references carries a SHA-256 hash; a single mismatch fails validation and is a reason for Stale. Before distribution, check the following five points.
- Report reference: the report the manifest points to has a valid address and matching hash
- Summary values match: summary values in the manifest match the report
- Understanding layer complete: required items and referential integrity of the declared state are all present
- State matches coverage: the declared state matches the layers actually filled (too wide or too narrow both fail)
- Derivative version matches: the base data version of operation files matches the dataset version in the report
Passing validation does not by itself move data to Quality-Ready; the transition requires passing decision gate ② (G2).
4. Distribute and publish
Keep data files at their original location (the public data portal or an internal repository) and provide the manifest and pack files at a public address where users and agents can download them. For public data, put the portal detail-page URL in the landing page (dcat:landingPage). When data is changed or remeasured, issue a new manifest version and leave the files of earlier versions unchanged. Discovery, exchange and use are covered in a follow-on part (Part 5).
The four public data examples have no operating guideline applied and are Discoverable, so they are not distributed as packs. A full manifest example is in Manifest example.
Completion check
- All files needed for the declared state present
- SHA-256 hash recorded for every referenced file
- No data files inside the pack
- Summary values match the report
Next step: Walkthrough with example data
Basis: Part 1 3.15, 5.5 · Part 2 9.2, Table 9-2 · Part 3 5.1, 5.2, 5.3, 9.2, 9.3, Table 9-3
Preparing data › Examples
Walkthrough with example data
Contents
ContentsThis page applies the procedure step by step to one example file (20 business registration records) and shows what was recorded and how the measurement changed at each stage. After stage 1, the formally required indicators measured rise from 6 to 7 of 13, and the judgments an agent must guess fall from 10 to 2. The data values are not changed along the way.
The example file is fictitious and does not refer to any real organization or data; the figures were measured with this site’s measurement engine (trial version). The effect on real agents’ behaviour and answer accuracy has not yet been measured.
① Check the data
The original file example.csv is a UTF-8 CSV with 20 rows and 8 columns; at the start there is only the file, with no description. It has rows and columns with a data type per column, so its type is tabular (STRUCT). Business names are corporate information, but a sole proprietor’s business name may be personal information, so check with the privacy department.
| bizId | bizName | industryCode | regionCode | employeeCount | revenueBand | registeredOn | closedFlag |
|---|---|---|---|---|---|---|---|
| B-2019-0001 | 가온정밀 | C29294 | 11680 | 42 | B3 | 2019-03-11 | 0 |
| B-2019-0014 | 대성포장 | C22240 | 41135 | 17 | B2 | 2019-05-02 | 0 |
| B-2019-0033 | 한별전자 | C26429 | 28185 | 133 | B4 | 2019-07-19 | 0 |
② Write the manifest
The provider filled in the 23 elements and the column schema. The example organization has no identifier policy, so the default form from Choosing persistent identifiers was used: https://data.example.go.kr/id/dataset/biz-registry. The measurement engine computed the checksum and media type from the file.
Values of the 23 elements
| Element | Value |
|---|---|
| Dataset identifier | https://data.example.go.kr/id/dataset/biz-registry |
| Title · description | Example business registrations · Registration information and business status of businesses by region |
| Keywords | business · industry classification · region · business status (4) |
| Service type · structure type | FILE · Structured |
| Language · lifecycle status | KOR · Discoverable |
| Theme · landing page | INDUSTRY_EMPLOYMENT · https://data.example.go.kr/dataset/biz-registry |
| Creator · publisher | Example agency |
| Maintaining department · contact | Example agency data management team · data@example.go.kr |
| Creation method · update frequency | collected · ANNUAL |
| License · terms of use | KOGL-1 · KOGL Type 1: commercial use and modification allowed with attribution |
| Access rights | PUBLIC |
| Access URL · file format | https://data.example.go.kr/aird/.../example.csv · CSV |
| Media type · checksum | text/csv · 7ad8add25d7a6383… (SHA-256, computed by the engine) |
Value-list elements are chosen by their labels and written in the manifest as concept URIs from the vocabulary. The finished file is in Manifest example.
Column schema, 8 columns
| Column | Type | Description |
|---|---|---|
bizId | string | Unique registration number, format B-YYYY-NNNN. Required column |
bizName | string | Business name |
industryCode | string | Korean Standard Industrial Classification sub-class code |
regionCode | string | Administrative standard code, legal-dong city/county/district |
employeeCount | integer | Number of regular employees, 0 to 100000 |
revenueBand | string | Revenue band code, B1 to B4 |
registeredOn | date | First registration date, ISO 8601-1 |
closedFlag | integer | Closed or not: 0 open, 1 closed |
Two pieces of information in the column schema affected the measurement result. Marking bizId as required made D1-01 (required field completeness) measurable. The value range of employeeCount, by contrast, was written only in the description and not as the data type’s minimum and maximum, so D5-02 (numeric range validity) stayed unmeasured. The meaning of each revenueBand band is also missing, so this column schema does not yet meet the code-value rule. Both are completed under “Remaining work” below.
③ Measure quality
The example file was measured twice with the measurement engine: first with the file alone, then after stage 1 with bizId set as the record key.
| Item | File only | After stage 1 |
|---|---|---|
| Metadata elements | 1 / 23 | 23 / 23 |
| Column descriptions | 0 / 8 | 8 / 8 |
| Required indicators measured | 6 / 13 | 7 / 13 |
| Diagnostic Maturity | DM-0 (provisional) | DM-0 (provisional) |
| Quality tier | Not judged: no operating guideline applied | Not judged: no operating guideline applied |
| Judgments an agent must guess | 10 | 2 |
The agent judgment count uses the 16 items the measurement engine (trial version) checks in this example file for the four judgments (fitness, reliability, joinability, usability); 2 of them are not answered by the standard. The 24 items in What agents read are a different basis: the full list of information agents need, mapped to the standard. The one element met with the file alone is the checksum computed by the engine. After stage 1 one more indicator, D1-01, was measured, and the four minimum measurement indicators were measured both times. Without an operating guideline, D5-03 was measured provisionally with the example patterns of Part 2 Appendix I. With only 7 of 13 required indicators measured, Diagnostic Maturity does not reach DM-2, and with no guideline applied the tier is not judged even though every score is 1.0000. This results from the missing guideline, not from a defect in the data.
Scores by indicator
| Indicator | File only | After stage 1 |
|---|---|---|
| D1-01 required field completeness | Not measured | 1.0000 |
| D1-02 required metadata completeness | 0.0435 | 1.0000 |
| D5-01 format validity | 1.0000 | 1.0000 |
| D5-03 statistical plausibility · MMI | 1.0000 (provisional) | 1.0000 (provisional) |
| D6-01 uniqueness · MMI | 1.0000 (all columns combined) | 1.0000 (by bizId) |
| D7-01 encoding consistency · MMI | 1.0000 | 1.0000 |
| D7-02 technical validity · MMI | 1.0000 | 1.0000 |
The example file was generated without format errors, so there was nothing to fix. Real data can score below 1.0000 on D5-01, D7-01 and others; results for real public data are in Public data examples.
Six unmeasured indicators and what they need
| Indicator | Material needed |
|---|---|
| D2-01 cross-field consistency | Relation rules defined in the column schema or manifest |
| D2-02 referential integrity | Actual values of the master code table (an address or reference alone is not enough) |
| D2-03 derived value accuracy | Definition of derivation rules |
| D3-01 standard name consistency | An authoritative code–name reference; the data must contain both code and name |
| D4-01 currency | Reference time and update history |
| D5-02 numeric range validity | Allowed numeric ranges per column (data type minimum and maximum) |
Under the standard’s precondition, D2-03 is not applicable (NOT_APPLICABLE) for data without stored derived values. The example file has none, so D2-03 is not applicable, but the measurement engine (trial version) counted it as unmeasured. Following the standard, the coverage in the report below is 7/12 (about 0.58), not 7/13 (0.5385).
Report excerpt
generatedAt              2026-10-05T...
datasetFile              example.csv
fileChecksum             SHA-256 7ad8add2...
dataType                 STRUCT
recordCount              20
indicators               D1-01 1.0 (required) · D5-01 1.0 (required) · D5-03 1.0 (required · provisional) · ...
notMeasured              D2-02 (required): compare with actual master code table values
                         D3-01 (required): an authoritative reference is needed
formalAssessmentCoverage 0.5385
diagnosticMaturity       DM-0
assessmentStatus         PROVISIONAL
thresholdProfile         (none — no operating guideline applied)
note                     D5-03 measured provisionally with the Appendix I example patterns. Not for official disclosure or comparison between organizations.
formalAssessmentCoverage0.5385 means 7 of 13 required indicators were measured; it is not a quality score or tier.assessmentStatusPROVISIONALmeans D5-03 was measured provisionally with the example patterns.thresholdProfileis empty because no operating guideline was applied — the same state asaird:thresholdProfile: nullin the Manifest example.
④ Prepare for a purpose
The purposes the example data can support are machine learning (ML, label candidate closedFlag) and knowledge graphs (KG, standard code columns industryCode and regionCode). Statistics, RAG, deep learning and fine-tuning do not apply for lack of matching data. No purpose profile is registered, so the purpose tier is recorded as “not judged” with the reason PROFILE_NOT_REGISTERED. Stage 3 is carried out after a purpose is fixed, by writing an operation file per purpose type.
Remaining work
The example file has completed stage 1 and the stage 2 measurement; Diagnostic Maturity DM-2, a quality tier and operation files remain. Record the remaining work by reason, without mixing gaps in the data with the missing guideline.
- Do now: add the meaning of each
revenueBandband and the value range (minimum, maximum) ofemployeeCountto the column schema → D5-02 becomes measurable. Record unfixable limitations (e.g. “closures may be reflected inclosedFlaglater than they occur, due to late reporting”) - After obtaining materials: industry and legal-dong code tables → D2-02; a code–name reference → D3-01; reference time and update history → D4-01
- Outside the provider’s scope: apply an operating guideline and remeasure → a new report and a tier under that guideline. Needs the guideline provided with the standard (expected December 2026) or one built and published by the organization
Next step: Public data examples — measurements of four real public datasets
Basis: Part 1 5.6 Table 5-5 · Part 2 Appendix I · reasons are listed in Status and judgment values
Preparing data › Examples
Public data examples
Contents
ContentsThese are measurements of four real public datasets. Stage 1 alone increased the number of indicators that could be measured, and the defects measurement revealed differed by data type. The measurements were taken on 6 October 2026; no operating guideline was applied, so no quality tier was judged.
1. The examples
Each example pairs one data type with one representative use purpose, built from real public data.
| Example | Type × purpose | Size |
|---|---|---|
| Commercial district store information — Sejong sample | STRUCT × KG | 15,816 rows |
| Hourly national electricity demand (2025) | TSERIES × Stats | 8,760 time points |
| Corpus of the Public Data Act and the AI Data Administration Act | TEXT × RAG | 4 editions · 209 articles · 673 units |
| Statutory interpretation Q&A pairs | PT × FineTuning | 51 cases → 45 pairs |
Source data
- Store information: Small Enterprise and Market Service · public data portal 15083033 (June 2026 edition)
- Electricity demand: Korea Power Exchange · public data portal 15065266
- Act corpus: PDF texts saved from the National Law Information Center, Ministry of Government Legislation (current and forthcoming editions)
- Interpretations: Ministry of Government Legislation Open API target=expc (51 selected from 8,881 listed by title and text search), plus 7 interpretations by the national statistics agency (target=kostatCgmExpc) for comparison
2. Indicators measured before and after stage 1
Each example was measured three times: the original before stage 1, the same original after stage 1, and the cleaned data with defects fixed. At stage 1, required fields, formats, value ranges, cross-field relations, derivation rules and code tables were written into the column schema. From the original before to after stage 1 the values did not change, yet more indicators were measured, because the definitions written at stage 1 are inputs to measurement at stage 2.
| Example | Original · before stage 1 | Original · after stage 1 | Cleaned |
|---|---|---|---|
STRUCT × KG | 5 / 13 | 11 / 13 | 11 / 13 |
TSERIES × Stats | 5 / 13 | 10 / 13 | 10 / 13 |
TEXT × RAG | 3 / 5 | 4 / 5 | 5 / 5 |
PT × FineTuning | 4 / 8 | 7 / 8 | 7 / 8 |
Diagnostic Maturity by type is in Reading the report.
3. Defects revealed by measurement
Tabular data mainly showed mismatches between names and codes; time series showed encoding and empty-row problems; text and Q&A pairs showed edition and duplication issues. A score of 1.0 does not rule out defects: identifier-based D6-01 (uniqueness), for example, cannot find rows that differ only in identifier, so such defects are handled at stage 3, preparation for a purpose.
Defects and handling by type (13)
| Type | Defect | Indicator | Handling |
|---|---|---|---|
STRUCT | Commas in sub-category names turned into semicolons (61 cells) | D3-01 standard name consistency | Replaced with code table names → 1.0 |
STRUCT | 82 rows identical in 38 columns except the store number | D6-01 1.0 (by identifier) | Treated as entity candidates in KG preparation |
STRUCT | Legal-dong names omit the village — 26 legal-dong codes under one name | — | Legal-dong code used as the KG entity identifier |
STRUCT | Industry and legal-dong code table values not obtained | D2-02 partially measured (coverage 0.6) | Obtain the code table files and measure |
TSERIES | CP949 encoding | D7-01 0.0 | Saved again as UTF-8 → 1.0 |
TSERIES | Trailing empty row (portal 366 rows, actual 365) | D1-01 below 1 | Empty row removed |
TSERIES | Unit only in the description text | — | Unit added to the column description |
TEXT | PDF headers and footers mixed into the text; effective date only in one header line | D7-01 | Split by article; effective date recorded at the source location |
TEXT | Current and forthcoming editions of the same act | — | Editions separated with valid_from and valid_to |
TEXT | Update frequency “as needed” | D4-01 not measured | Update commitment recorded as a frequency value |
PT | 6 pairs of interpretations identical except for case number | D6-01 1.0 | One kept per pair in the operation file |
PT | 7 empty requesting-agency names | D1-01 0.983 → 1.0 | Restored from the case title and source recorded |
PT | A 2018 interpretation cites an article deleted in 2022 | — | Marked “deleted article”, not linked to the current text |
4. Catalog observation case
Data already registered on a portal still needs separate preparation for AI use. Comparing the listing metadata of one industrial-complex company dataset (379 rows, 9 columns, CSV) with the 19 elements required by the draft standard found 6 elements already on the portal, 3 needing only format conversion, and 10 to be written new.
Elements by category and observations
| Category | Elements |
|---|---|
| On the portal (6) | Title · publisher · file format · access URL · description · keywords |
| Format conversion (3) | Update frequency · media type · service type |
| Write new (10) | Dataset identifier · language · lifecycle status · creator · contact · creation method · license · terms of use · access rights · checksum |
| Not classified (4) | Dataset structure type · theme · landing page · maintaining department — added to the demo profile after the observation |
If the portal provides column structure, a draft column schema can be made without the file; here a draft for 9 columns was built from observed names, data types and distinct-value counts, and the provider adds a description for each column. The observation also flags items needing a privacy check — here, a phone number column whose publication scope must be confirmed with the responsible department. The institution is not named.
Completion check
- Example with the same type as your data found
- Increase in measured indicators after stage 1 checked for that example
- Your data checked for the same defects (CP949 encoding, trailing empty rows, units only in descriptions)
Next step: start with Checking your data for your own data.
Basis: measured with this site’s measurement engine (trial version) · observation baseline Part 3 Annex A.1
What agents read
Contents
ContentsWe checked the 24 pieces of information an agent needs for the four judgments it makes before using data against the clauses and metadata elements of the standard: the standard requires 9, covers 10 partially and leaves 5 as gaps.
Agents judge from structured fields and measurement evidence, not from a single score. The coverage tables below are based on tabular data (STRUCT); documents, images and instruction–response pairs (PT) need different information for these judgments.
Scope and goal of the standard
The standard is not limited to public data; it covers all data published or provided by public institutions, enterprises and non-profit organizations. Its goal is to let AI agents access data, understand it, trust it and judge whether they may use it. The design started from observations of public data.
How the standard covers each judgment
Required required by the standard · Partial conditionally required, optional or recommended, or measured but not exposed as a field · Gap not in required elements or indicators
Fitness — fit to the question
Judgment question · Does it fit my question?
Fitness — fit to the question — expand 7-row table
| Information needed | Standard | How the standard covers it |
|---|---|---|
| Temporal coverage | Gap | None The vocabulary term exists in DCAT-AP-KR (DCAT). It is not a required element of the AIRD discovery · understanding layers. Reference time and measurement interval for time series are recommended. Fill rate of “temporal coverage” in the portal catalog: 5.2% (Korea Public Data Portal catalog observation, 2026-08-31) |
| Spatial coverage | Gap | None Same as temporal coverage. Fill rate of “spatial coverage” in the portal catalog: 6.4% |
| Units | Partial | Unit in the column schema (recommended) · time series unit (recommended) |
| Population covered | Partial | Preparation item for the Stats (statistical analysis) purpose (recommended) · rai:dataBiases (known biases, required) |
| Column meaning | Required | Column schema (csvw:tableSchema) (conditionally required for structured data) |
| Data type | Required | dct:type · aird:dataType |
| Unsuitable uses | Required | rai:dataLimitations |
Reliability — grounds for trust
Judgment question · Can it be trusted?
The quality tier recorded in a manifest is judged not by the standard but by the threshold profile of an operating guideline. Whoever judges the tier records the operating guideline’s identifier and version with the tier and publishes that guideline, so an agent reads the tier together with the guideline used to judge it. The conditions for using a tier as evidence are in Fields and handling by judgment.
Reliability coverage table (6 rows)
| Information needed | Standard | How the standard covers it |
|---|---|---|
| Actually updated | Partial | D4-01 Currency (required) · D4-02 Update fidelity (optional for STRUCT) Update frequency is a required metadata element. Checking against the actual update history is an optional indicator |
| File integrity | Required | spdx:checksum · D7-02 Technical validity · suspension of validity (Stale) |
| API availability | Gap | Interface conformance of the providing system is a level separate from data-side conditions [Part 1 Table 6-1] The 16 quality indicators are file-based. Availability is not exposed as a fact attached to the data |
| API responses match the spec | Gap | None No API-side indicator corresponds to D7-02 for files |
| Values meet format · range | Required | D5-01 · D5-02 · D5-03 |
| Diagnostic Maturity | Required | Diagnostic Maturity (DM) · 5 indicator applicability values |
Joinability — ability to join
Judgment question · Can it be joined with other data?
Joinability coverage table (4 rows)
| Information needed | Standard | How the standard covers it |
|---|---|---|
| Persistent identifier | Required | dct:identifier |
| Record key | Required | D6-01 Uniqueness (when identifier columns are designated) |
| Standard codes checked by value | Partial | D2-02 Referential integrity · D3-01 Standard name conformance The standard requires checking against the actual values of the code list (an address alone is not enough). Per-column results (code system and match rate) are only in the diagnostic report and are not exposed as metadata fields |
| Entity IDs and code list source | Partial | Preparation item for the KG (knowledge graph) purpose (recommended) |
Usability — conditions of use
Judgment question · May it be used?
Usability — conditions of use — expand 7-row table
| Information needed | Standard | How the standard covers it |
|---|---|---|
| Machine-readable license | Partial | dct:license (14 values in the vocabulary’s kr-license list — KOGL · CC · CC0) The value list is closed. There is no value for an enterprise’s own terms of use or for MIT · Apache · ODbL licenses. Extending the value list is a candidate for a vocabulary revision proposal |
| AI training permitted | Partial | odrl:hasPolicy (optional) · KOGL AI type (kr-license) The place for a machine-readable usage policy is an optional element. For data outside KOGL, no license value means training is permitted |
| Automated collection permitted | Partial | odrl:hasPolicy (optional) Even data that people can download and use may have terms that prohibit automated collection (for example, web crawling). There are cases where the terms of data provided free by enterprises include such a clause |
| Version of the terms of use | Gap | dct:rights notice (string) Own terms change with each revision. No field records which version (effective date) of the terms applies |
| Fee · contract terms | Partial | dcatkr:fee (recommended) · sc:offers (conditionally required when fee=true) Price · currency · unit can be recorded. There is no place for pay-as-you-go after a free quota or for terms limited to contracted customers |
| Access conditions | Required | dct:accessRights (eu-access: PUBLIC · RESTRICTED · NON_PUBLIC) |
| Contains personal data | Partial | aird:deidentificationLevel (conditional) · aird:containsPersonalData (conditional) |
Summary of the coverage tables
Joinability has no gaps. Because the standard requires checking against the actual values of the code list, what remains is exposing the per-column check results as metadata fields.
The 5 gaps are in fitness, reliability and usability. Of the information agents use as conditions when selecting data, temporal and spatial coverage are not required elements, and whether AI training is permitted appears only in an optional element. In addition, the 16 quality indicators target files, so the availability and spec conformance of data provided through an API do not appear as facts recorded with the data.
Proposal for exposing verified facts
Of the 7 facts in the “Standard status by fact” table below, the standard already measures 5, but the results are recorded only in the diagnostic report, and the manifest records only dimension scores. This site proposes a way to expose the measurement results in the manifest as facts.
Standard status by fact — expand 7-row table
| Fact | Judgment | Where the standard produces it | Standard status |
|---|---|---|---|
update_delay_days | Reliability | D4-01 (days elapsed − update frequency) | Measured, not exposed |
api_availability_7d | Reliability | Outside the standard | Not measured |
response_matches_spec | Reliability | Outside the standard | Not measured |
pk_uniqueness | Joinability | D6-01 | Measured, not exposed |
code_columns_matched | Joinability | D2-02 (per column) | Measured, not exposed |
encoding | Reliability | D7-01 | Measured, not exposed |
required_fields_nonnull | Fitness | D1-01 | Measured, not exposed |
Proposed exposure method
dqv:QualityMeasurement without a new vocabulary. One fact is one measurement and holds the following.
- Indicator (
dqv:isMeasurementOf) and value (dqv:value) - Measured object (
dqv:computedOn) and target column - Time (
prov:generatedAtTime) and validity period - Reference basis (for example, a code list and its version)
Next step: Fields and handling by judgment
Basis: Part 1 Table 6-1
Fields and handling by judgment
Contents
ContentsThis page shows in pseudocode which fields an agent reads from the manifest for each judgment and how it judges them. The fields and judgment values follow the standard; the judgment rules are this site’s recommendations.
Reading principle: the standard aims to let agents judge without guessing, so agents never replace a missing field with a guessed value. Without evidence, the agent states “no evidence” in its result; when a human judgment is needed, it hands the case over to human review.
Fitness — fit to the question
To judge whether the data fits the question, the agent reads dct:description · csvw:tableSchema · dct:type · rai:dataLimitations · rai:dataBiases.
schema = m.get("csvw:tableSchema")
if schema is None:
    return no_evidence("column meanings are not recorded")   # do not guess from column names
for col in columns_used_by_question:
    if not column(schema, col).get("dc:description"):
        return no_evidence(f"meaning of {col} is not recorded")
# rai:dataLimitations · rai:dataBiases are lists of human-written sentences.
# Do not filter them by string matching; present them as-is with the answer.
caveats = m.get("rai:dataLimitations", []) + m.get("rai:dataBiases", [])
return fit(caveats=caveats)
When the field is missing: if the column schema (csvw:tableSchema) has no column description, the agent does not infer the meaning from the column name and states “column meaning not recorded” in the answer.
Reliability — grounds for trust
To judge whether the data can be trusted, the agent reads aird:lifecycleStatus · dcat:distribution[].spdx:checksum · dct:modified · dct:accrualPeriodicity · aird:diagnosticMaturity · aird:qualityTier · aird:thresholdProfile · aird:diagnosticReport.
# local_name: last segment of the concept URI (…/lifecycle-status/Stale → Stale)
if local_name(m["aird:lifecycleStatus"]) == "Stale":
    return exclude("validity suspended")
d = distribution(m, downloaded_url)               # each distribution has its own checksum
if sha256(downloaded_file) != d["spdx:checksum"]["spdx:checksumValue"]:
    return exclude("checksum mismatch — not the file the manifest points to")
dm = m.get("aird:diagnosticMaturity")
if dm is None:
    # null has two meanings. Tell them apart by the diagnosis status in the diagnostic report.
    if diagnosis_status(m) in ("SCHEMA_ONLY", "FILE_BROKEN"):
        return exclude("file could not enter diagnosis")
    return caution("Diagnostic Maturity not established — insufficient quality evidence")   # do not read as 0
# A tier is judged by the threshold profile of an operating guideline. Check all four conditions.
profile = threshold_profile(m.get("aird:thresholdProfile"))   # None if absent
guideline = operating_guideline(m)                 # identifier · version · URL — None if absent
tier_evidence = (
    dm == "DM-2"                                              # (a) Diagnostic Maturity DM-2
    and profile is not None
    and profile["aird:profileStatus"] == "OFFICIAL"                        # (b) EXAMPLE is not tier evidence
    and evaluation_status(m) != "PROVISIONAL"                 # (c) not a provisional evaluation
    and guideline is not None and guideline.identifier and guideline.version
    and accessible(guideline.url)                             # (d) the published operating guideline can be checked
)
if not tier_evidence:
    return caution(f"Diagnostic Maturity {dm} · no tier evidence", score=m.get("aird:qualityIndexMin"))
return trusted(tier=m.get("aird:qualityTier"),
               guideline=(guideline.identifier, guideline.version),
               profile=(profile["aird:profileId"], profile["aird:profileVersion"]))
When the field is missing: if Diagnostic Maturity (DM) is missing, the agent treats it as “insufficient measurement evidence”, not as “low”.
The agent reads a quality tier as evidence only when all four of the following conditions are met.
| Condition | Value checked |
|---|---|
| (a) Diagnostic Maturity | DM-2 |
| (b) Status of the threshold profile | OFFICIAL (not EXAMPLE) |
| (c) Evaluation status | Not PROVISIONAL |
| (d) Operating guideline | The identifier and version of the operating guideline used for the judgment are known, and the published document is accessible |
If any condition is not met, the agent sets the result to “caution (… no tier evidence)” and reads the score only for reference. The structure and publication requirements of operating guidelines are in Building an operating guideline.
How to check the operating guideline
The standard does not yet have a manifest property that points to the operating guideline, so condition (d) is checked through the threshold profile identification (aird:thresholdProfile) and the operating guideline information recorded alongside the tier.
Joinability — ability to join
To judge whether the data can be joined with other data, the agent reads dct:identifier · csvw:tableSchema.primaryKey · csvw:tableSchema.columns[].dc:description and the D2-02 result in the diagnostic report.
a, b = join_columns_of_the_two_datasets
# The manifest has no dedicated field for a column’s code system (today it appears only in the column description text).
# Value-level check results are in the diagnostic report and are not exposed in the manifest — the verified-facts proposal fills this gap.
ra, rb = d2_02_result(report(a)), d2_02_result(report(b))   # None if the report cannot be read
if ra is None or rb is None:
    return candidate("value-level check results unavailable — do not join just because names match")
if ra.applicability != "APPLIED" or rb.applicability != "APPLIED":
    return candidate("values were not checked against a code list")
if ra.code_list != rb.code_list:
    return exclude("checked against different code lists")
return join(evidence=[ra.match_rate, rb.match_rate, ra.code_list_version])
When the field is missing: if there is no value-level check result from D2-02 (Referential integrity), the agent keeps the join only as a “candidate” and states in the result that there is no evidence for the join.
Usability — conditions of use
To judge whether the data may be used, the agent reads dct:license · dct:rights · dct:accessRights · aird:containsPersonalData · aird:deidentificationLevel · odrl:hasPolicy.
if local_name(m["dct:accessRights"]) != "PUBLIC":
    return human_review("access-restricted data")
lic = m["dct:license"]
if lic not in KR_LICENSE:                      # value list kr-license in the vocabulary
    return human_review("license outside the value list — machines cannot read its conditions")
conditions = license_conditions(lic)
# No required element covers AI training permission — read only the optional odrl:hasPolicy; do not guess from dct:rights text
policy = m.get("odrl:hasPolicy")
training_allowed = permitted_actions(policy) if policy else "unconfirmed"
return usable(conditions=conditions, training_allowed=training_allowed)
When the field is missing: whether AI training is permitted is not a required element of the standard; it can be expressed in the optional usage policy (odrl:hasPolicy). If there is no usage policy, the agent does not infer it from the rights (dct:rights) text and records it as “unconfirmed”.
Handling information the standard does not define
The following four kinds of information are not required elements of the standard, so this site recommends the following handling on the agent side.
| Information not in the required elements | Recommendation for agents |
|---|---|
| Temporal coverage · spatial coverage | Read DCAT dct:temporal · dct:spatial if present. Otherwise, mark “coverage not recorded”. If the question requires coverage, hand over to human review. |
| Whether AI training is permitted | If there is an ODRL policy (odrl:hasPolicy), read the permitted · prohibited actions. Otherwise, record it as “unconfirmed”. For training use, hand over to human review. |
| Whether automated collection is permitted · version of the terms of use | If the ODRL policy has a prohibited action (odrl:prohibition), follow it. If there is no policy and the conditions of use exist only as a terms document, do not collect automatically and record it as “unconfirmed”. If the effective date of the terms cannot be confirmed, hand over to human review. |
| API availability · response conformance to the spec | The agent checks these directly before calling. It keeps the check time and result as evidence for its judgment. It does not substitute values from the manifest. |
See also: the shape of a manifest is in Manifest example and the list of properties in Metadata elements.
Basis: Part 3
Other paths · Preparing data — Writing the manifest (stage 1) · Operating guidelines — Adoption brief
Adoption brief
Contents
ContentsThis page summarizes the scope of the standard, operating guidelines and the adoption steps for organizations considering adoption (public institutions, companies, industry associations, data platforms). The standard is not mandatory; an adopting organization starts with stage 1 documentation and builds an operating guideline or adopts the one the standard provides.
Overview
The AI-Ready Data (AIRD) standard specifies how to record, with the data and in machine-readable form, the grounds for the four judgments an AI agent makes before using data: fitness (Does it fit the question?), reliability (Can it be trusted?), joinability (Can it be joined?) and usability (May it be used?). Parts 1–3 are the TTAK draft (v0.95); Parts 4–5 are follow-on parts expected to be enacted in 2027.
Background
The users of data are expanding from people to AI agents, and an agent cannot verify facts that are not recorded with the data, so it guesses. We observed one public dataset with relatively complete catalog metadata: of the 19 required metadata elements in the draft standard (15 for the dataset, 4 for the distribution), 10 had to be newly written. Registering data on a portal and preparing it for AI use are separate tasks. Data that companies provide free of charge may have its own terms of use that prohibit redistribution or automated collection; a person reads the terms and decides, but an agent cannot check the conditions of use (Why it is needed, with cases).
Obligation to apply
This standard is not an obligation under any law or regulation, and it does not define a method for ranking organizations. The Part 1–3 draft standard is in scope for establishment in December 2026; once the established standard is published, it takes precedence. The content may change before establishment. Parts 4–5 are follow-on parts expected to be enacted in 2027. When the established standard is published, this site will be updated accordingly.
Tasks by role
| Who | Tasks |
|---|---|
| Data provider | Stage 1: write metadata elements and column descriptions · Stage 2: fix the values that can be fixed and record limitations · Stage 3: only for data with a defined use purpose |
| Diagnostic tool · system | Compute scores · draft the manifest and the diagnostic report · compute checksums |
| Guideline publisher | Build an operating guideline or adopt the standard-provided operating guideline · publish the operating guideline and threshold profile (judgment threshold values) |
| Organization that buys or procures data | Requiring a manifest and machine-readable conditions of use in contract and procurement terms is recommended |
This site recommends preparing data in this order: data with usage requests, data used in combination with other data, then the rest (FAQ).
Decisions
Judgment criteria are set by an operating guideline that is separate from the standard, so an adopting organization decides whether to build its own operating guideline or adopt the standard-provided one. The standard-provided operating guideline is published when the standard is established (expected December 2026), and organizations, institutions and domains can build operating guidelines independently. Results without an applied operating guideline get no tier judgment (not judged: no operating guideline applied; see Judgment procedure).
Division of roles between the standard and the operating guideline
Tier elements (the tier scheme Tier 0–4, tier names, label format, judgment procedure) follow the standard; operational elements (threshold profile, diagnosis cycle, result validity period, appeal procedure, tool certification) are set by the operating guideline. The operating guideline includes the threshold profile (judgment threshold values).
An organization that judges and publishes tiers publishes the operating guideline it applied, makes it accessible, and states the guideline’s identifier and version with the tier. Measurement and writing the diagnostic report are possible without an operating guideline. How to build an operating guideline and the publication requirements are in Building an operating guideline.
Information not covered by the standard
Temporal and spatial coverage, whether AI training is permitted, and API availability are not required elements. A company’s own terms of use are not in the vocabulary’s list of license values (kr-license), so they are recorded in the conditions of use (dct:rights) (What agents read).
Cost and benefit
Stage 1 records descriptive information without changing data values, and it can start without special tools. Checksums are computed with common tools such as sha256sum. If the existing registration system does not support entering required properties, version management, checksum generation and manifest publication, those functions must be added.
This site’s measurement engine (experimental) shows that a manifest reduces the number of items an agent must guess. The effect on actual agent behavior and answer accuracy has not been measured yet, and the effect study has not been run.
Adoption steps
- Select the target data and write the stage 1 metadata elements: write the manifest from the data file and existing catalog information (Writing the manifest (stage 1)).
- Learn how the diagnostic report is structured and how to read reasons for not measured (Reading the report)
- Build an operating guideline or adopt the standard-provided operating guideline (Building an operating guideline)
Next step: Building an operating guideline
Basis: Part 1 7.1
Building an operating guideline
Contents
Contents- Roles of the operating guideline and the standard
- Same scores, different thresholds
- Ways to build an operating guideline
- Structure of the threshold profile
- Tier labels and publication requirements
- Example threshold profile (Part 2 Appendix I)
- Purpose-specific criteria
- Measurement before an operating guideline is applied
An operating guideline is a document that holds judgment threshold values and operational matters, built separately from the standard. The tier system, tier names, label format and judgment procedure follow the standard; threshold values and operational matters are set by the operating guideline.
Roles of the operating guideline and the standard
The numbers used for judgment (the threshold profile) and operational matters such as the diagnosis cycle and result validity period are set by the operating guideline; tier elements such as the tier system, judgment procedure, quality indicator definitions and tier label format are specified by the standard.
List of operational and tier elements
Each column is a separate list; items on the same row are not paired.
| Set by the operating guideline (operational elements) | Specified by the standard (tier elements) |
|---|---|
| Tier band boundaries in the threshold profile | Tier scheme Tier 0–4 and tier names (Unqualified · Bronze · Silver · Gold · Platinum) [Part 2 7.1] |
| Per-dimension required pass lines, dimension weights, and weight adjustment ranges in the threshold profile | Judgment procedure: candidate tier from the minimum dimension score → pass line check → demotion by one tier if any dimension falls short [Part 2 6 · 7] |
| DM-1 evaluation coverage lower bound and indicator parameters (D3-02 (label accuracy) label match criterion · D5-03 dummy value patterns) in the threshold profile | Definitions, measurement formulas, and the Diagnostic Maturity decision table for the 16 quality indicators [Part 2 Annex B.5] |
| Identifier, version, and activation procedure of the threshold profile | Element structure of the threshold profile [Part 2 Annex D · Table 9-3] |
| Operational matters: diagnosis cycle · result validity period · appeal procedure · tool certification [Part 1 7.1] | Tier label format Gold (Tier 3, STRUCT) [Part 1 Annex A] |
| Judgment criteria for purpose tiers · detailed pack structure | Readiness states and pack composition [Part 1 5.1 · 5.5] |
Same scores, different thresholds
The same dimension scores can yield different quality tiers depending on the threshold values of the applied operating guideline. The thresholds in the simulation below are hypothetical values generated at random; they are not values proposed by this site.
Ways to build an operating guideline
The standard-provided operating guideline is published when the standard is established (expected December 2026). There is more than one guideline publisher: organizations, institutions and domains can build operating guidelines independently. A guideline publisher chooses one of the following three approaches.
- Adopt: apply the standard-provided operating guideline as is, and state that guideline’s identifier and version with the tier.
- Adjust: adjust the threshold profile and operational matters based on the standard-provided operating guideline, and publish the adjusted guideline under your own identifier and version.
- Build your own: set the threshold profile and operational matters directly, and publish the guideline under your own identifier and version.
In every approach, tier elements follow the standard.
Structure of the threshold profile
The threshold profile (judgment threshold values) is a machine-readable file within the operating guideline. It holds the numbers adjusted during operation, such as tier bands, pass lines and weights, with an identifier and a version. The operating guideline sets the identifier, version and activation procedure; Part 2 Annex D specifies the structure of the elements. The machine representation is aird-threshold-profile-1.0.schema.json.
Threshold profile elements — expand table (10 rows)
| Element | Obligation | Value range | Value it sets |
|---|---|---|---|
profileId | Required | URI | Profile identifier |
version | Required | SemVer | Profile version |
status | Required | OFFICIAL or EXAMPLE | Profile status |
digest | Required | SHA-256 | Hash of the profile file |
tierThresholds | Required | 4 values in 0.0–1.0 | Tier bands (Part 2 7.1) |
passLines | Required | 7 dimensions × 4 tiers | Per-dimension required pass lines (7.2) |
dimensionWeights | Required | 7 values summing to 1.00 | Dimension weights (6.3) |
weightAdjustmentRange | Required | Lower and upper bound per dimension | Weight adjustment range (6.3) |
dm1Coverage | Required | 0.0–1.0 | DM-1 evaluation coverage lower bound (8.1) |
indicatorParameters | Conditionally required | Object per indicator | D3-02 image label match criterion · D5-03 dummy value patterns |
Tier labels and publication requirements
Whoever judges and publishes tiers observes the following four requirements.
- Tier label in the standard format: write the tier in the form
Gold (Tier 3, STRUCT). The data type must always be included; Diagnostic Maturity (DM) is left out of the tier label. - Operating guideline identifier and version alongside: state the identifier and version of the operating guideline applied in the judgment together with the tier.
- Publication of the operating guideline and threshold profile: publish the applied operating guideline and threshold profile so that anyone can access them.
- Hash record: record the identifier, version and hash of the threshold profile in the diagnostic report. Data users can use the hash to verify the file used in the judgment.
Example threshold profile (Part 2 Appendix I)
Example Example threshold profile · status EXAMPLE · not used for tier judgment · source: TTAK draft (v0.95)
The numbers in Part 2 Appendix I are not values with an established academic basis. The example threshold profile records these numbers in the Annex D structure and has the status EXAMPLE and is used only for provisional calculation and tool development, never for tier judgments; all values in the tables below are example values.
Tier bands (minimum dimension score) — example
| Tier | Tier name | Minimum dimension score |
|---|---|---|
| Tier 4 | Platinum | 0.95 or higher |
| Tier 3 | Gold | 0.85 or higher, below 0.95 |
| Tier 2 | Silver | 0.70 or higher, below 0.85 |
| Tier 1 | Bronze | 0.50 or higher, below 0.70 |
| Tier 0 | Unqualified | Below 0.50, or a pass line not met |
Tier 0 applies when the minimum dimension score is below 0.50, and when the candidate tier was Tier 1 but a dimension fell short of the Tier 1 pass line, so the result was demoted by one tier.
Per-dimension required pass lines — example
Per-dimension required pass lines — expand table (7 rows)
| Dimension | Tier 1 | Tier 2 | Tier 3 | Tier 4 |
|---|---|---|---|---|
| D1 Completeness | 0.60 | 0.75 | 0.85 | 0.95 |
| D2 Consistency | 0.50 | 0.70 | 0.80 | 0.90 |
| D3 Accuracy | 0.65 | 0.80 | 0.90 | 0.95 |
| D4 Timeliness | 0.40 | 0.60 | 0.75 | 0.85 |
| D5 Validity | 0.60 | 0.75 | 0.85 | 0.95 |
| D6 Uniqueness | 0.60 | 0.75 | 0.85 | 0.95 |
| D7 Machine readability | 0.80 | 0.90 | 0.95 | 1.00 |
Dimension weights — example
Dimension weights — expand table (7 rows)
| Dimension | Example weight | Adjustment range |
|---|---|---|
| D1 Completeness | 0.18 | 0.10 – 0.25 |
| D2 Consistency | 0.10 | 0.07 – 0.18 |
| D3 Accuracy | 0.24 | 0.17 – 0.32 |
| D4 Timeliness | 0.10 | 0.05 – 0.18 |
| D5 Validity | 0.13 | 0.08 – 0.20 |
| D6 Uniqueness | 0.12 | 0.08 – 0.18 |
| D7 Machine readability | 0.13 | 0.08 – 0.20 |
Other values — example
| Item | Example value |
|---|---|
| DM-1 evaluation coverage lower bound (DM-1 is not judged with the example threshold profile) | 0.50 |
| D3-02 (label accuracy) label match criterion: image overlap ratio | 0.5 or higher |
| D5-03 dummy value patterns | 999999, 99999999, 9999, -1, -9, 0000 |
Purpose-specific criteria
The judgment criteria for the purpose tier are set by the operating guideline. A purpose tier is judged only when an operation-layer profile in registered status (Registered) exists for the use purpose type; for a type without a registered profile, no purpose tier is judged (PROFILE_NOT_REGISTERED). In that case, data prepared for a purpose (Purpose-Ready) is not reached either. There are four profile statuses: Draft, Candidate, Registered and Deprecated.
Measurement before an operating guideline is applied
Measurement and writing the diagnostic report are possible without an operating guideline. In that case the diagnostic tool measures D5-03 (Statistical plausibility) provisionally with the example patterns in Part 2 Appendix I and records the evaluation status as PROVISIONAL, and no tier is judged (not judged: no operating guideline applied).
Re-measurement after an operating guideline is applied
If, after an operating guideline is applied, its D5-03 patterns differ from the example, measure again and issue a new diagnostic report. Reuse an existing diagnostic report as is only when the target version, measurement rules, threshold profile and measurement time are all the same.
The steps for Diagnostic Maturity and tier judgment are in Judgment procedure.
Basis: Part 1 3.20, 3.21, 5.1, 5.5, 5.6 Table 5-3, 7.1, Annex A · Part 2 6, 7.1, 7.3, 9.1, Table 9-3, Annex B.5, Annex D Table D.1, Appendix I Tables I.1–I.4 · Part 3 8.2, Annex C.19
Other paths · Preparing data — Writing the manifest (stage 1) · For agents — What agents read
Key concepts
This page defines four groups of concepts needed to read the standard: readiness states and decision gates, the three judgments, outputs, and roles. Diagnostic Maturity, the quality tier and the purpose tier answer different questions, so they are recorded separately and never combined.
Readiness states and decision gates
Data is prepared in three stages. At the end of each stage, a decision gate (G1 · G2 · G3) judges whether the data can transition to the next readiness state. Passing G1, G2 and G3 makes the data Discoverable (findable data), Quality-Ready (quality-checked data) and Purpose-Ready (purpose-prepared data) respectively; G2 requires Diagnostic Maturity DM-2, an operating guideline applied and quality tier Tier 1 or higher. AI-ready data is data in the Quality-Ready or Purpose-Ready state that meets the common readiness requirements for AI use.
Data that does not pass a decision gate is not rejected; it is improved and checked again. A state already reached is suspended (Stale) when an update is delayed or a checksum does not match, and it is restored after update and revalidation. The details of the Quality-Ready transition conditions are in Judgment procedure.
Readiness state conditions and terms
| Plain term | Standard term | Explanation |
|---|---|---|
| Findable data | readiness state Discoverable | The state of having the required metadata elements of the discovery layer. The result of stage 1. |
| Quality-checked data | readiness state Quality-Ready | The state in which quality has been measured and the transition conditions at G2 (DM-2 · Tier 1 or higher · operating guideline applied) are met. The result of stage 2. |
| Purpose-prepared data | readiness state Purpose-Ready | The state of being prepared to the criteria of a specific use purpose. The result of stage 3. |
| Suspended state | readiness state Stale | The state in which a readiness state is suspended because of an update delay or a checksum mismatch. Restored after update and revalidation. |
| Checkpoint | decision gate Decision Gate (G1 · G2 · G3) | The point at the end of each stage where it is judged whether data can transition to the next state. |
- What it means
- Data right after it is provided by the source. Data in this state is not AI-ready data.
- Verified layers
- None
- Quality tier
- —
- Purpose tier
- —
- Diagnostic Maturity
- —
- Relation to raw data
- Raw dataset
- What it means
- Contents and location are recorded, so the data can be searched and accessed.
- Verified layers
- Discovery
- Quality tier
- —
- Purpose tier
- —
- Diagnostic Maturity
- DM-0 · DM-1 · DM-2 if measured
- Relation to raw data
- Keeps the raw dataset’s values · converts only the format if needed
- Entry path
- Stage 1 — collection · conversion to an open format · writing the discovery layer
- G1 judges
- Completeness of the discovery layer
- Files proving the state
- manifest.json (discovery layer) · G1 judgment record
- What it means
- Quality is measured and judged with an operating guideline, and the transition conditions are met. If it meets the common readiness requirements, it is AI-ready data.
- Verified layers
- Discovery · understanding
- Quality tier
- Tier 1 (Bronze) or higher
- Purpose tier
- —
- Diagnostic Maturity
- DM-2
- Relation to raw data
- Reflects cleaning results · same dataset as the raw data
- Entry path
- Stage 2 — measuring quality · fixing defects · writing the understanding layer
- G2 judges
- Whether a transition to Quality-Ready is possible (DM-2 · Tier 1 or higher · applying the operating guideline’s threshold profile)
- Files proving the state
- manifest.json (discovery · understanding layers) · diagnostic report · G2 judgment record
- What it means
- The quantitative requirements of a specific use purpose are also met.
- Verified layers
- Discovery · understanding · operation
- Quality tier
- Kept
- Purpose tier
- Assigned per purpose
- Diagnostic Maturity
- DM-2
- Relation to raw data
- Purpose-specific derivatives · exist alongside the raw data
- Entry path
- Stage 3 — purpose-specific conversion · writing the operation layer
- G3 judges
- Fulfillment of the purpose requirements
- Files proving the state
- manifest.json · diagnostic report · operation files (per purpose) · G3 judgment record
- What it means
- The checksum does not match or the recorded update frequency was not kept, so the assigned tiers are suspended. Passing revalidation returns the data to its previous state.
- Verified layers
- Previous state kept
- Quality tier
- Suspended
- Purpose tier
- Suspended
- Diagnostic Maturity
- Kept
- Relation to raw data
- Relation of the previous state kept
Three judgments — not combined
Quality judgment is split into three values. Each answers a different question on a different basis, so the diagnostic tool records the three results separately. Diagnostic Maturity (DM) shows how far the required indicators have been measured, as DM-0 · DM-1 · DM-2, and is decided with a decision table. The quality tier (Q-Tier) shows the level of measured quality as Tier 0–4 and is judged from the minimum dimension score and the threshold profile of the operating guideline. The purpose tier (P-Tier) is the level of preparation for a specific purpose and is decided with the purpose profile registered for that purpose.
Even with high measured scores, the quality tier is not judged unless Diagnostic Maturity is DM-2, and the two values cannot replace each other. When a judgment cannot be made, the diagnostic tool records “not judged” and the reason, and does not substitute a score of 0 or the lowest tier (Status and judgment values).
Comparison of the three judgments
| Judgment | Question it answers | Form | Basis for the decision |
|---|---|---|---|
| Quality tier (Q-Tier) | Level of measured quality | Tier 0–4 · e.g. Gold (Tier 3, STRUCT) | Minimum dimension score · threshold profile of the operating guideline |
| Diagnostic Maturity (DM) | How much of the required indicators is measured | DM-0 · DM-1 · DM-2 | Diagnostic Maturity decision table (Judgment procedure) |
| Purpose tier (P-Tier) | Level of preparation for a specific purpose | e.g. P-Tier 2 (KG) | The purpose profile registered for that purpose |
Quality judgment terms
| Plain term | Standard term | Explanation |
|---|---|---|
| 7 dimensions | quality dimension Quality Dimension (D1–D7) | Completeness · consistency · accuracy · timeliness · validity · uniqueness · machine readability. |
| Quality tier | quality tier Q-Tier (aird:qualityTier, Tier 0–4) | The quality level judged with the threshold profile of the operating guideline. Not judged without an applied operating guideline. |
| Measurement completeness | Diagnostic Maturity Diagnostic Maturity (DM-0 · DM-1 · DM-2) | A graded judgment, decided with a decision table, of how far the required indicators have been measured. Not combined with quality scores. |
| Measured share | evaluation coverage Evaluation Coverage | A value from 0 to 1: the sum of statusFactor over applicable required formal indicators divided by the number of those indicators. Used for the DM-1 judgment. |
| Minimum indicators | minimum measurable indicator Minimum Measurable Indicator (MMI) | The four indicators that are the entry requirement for diagnosis (D5-03 · D6-01 · D7-01 · D7-02). The indicators with the lowest input requirements. |
| Lowest score | minimum dimension score Minimum Dimension Score | The lowest of the seven dimension scores. The starting point for finding the candidate tier. The average is not used for tier judgment. |
| One tier down | demotion Demotion | Lowering the candidate tier by one when a dimension falls short of the per-dimension required pass line set by the threshold profile of the operating guideline. |
| Ready for the next stage | transition eligibility Transition Eligibility | The state of having both Diagnostic Maturity DM-2 and a quality tier of Tier 1 or higher judged under an operating guideline. |
Outputs
Judgment results are kept as documents separate from the data. The manifest describes a dataset in machine-readable form; a new one is issued for each version and points to the previous version. The diagnostic report is a quality measurement document (JSON) created anew for each measurement, and an operation file is a preparation output made for each use purpose type.
The unit of distribution is the pack. A Quality-Ready pack consists of the manifest, the diagnostic report and the pack manifest; a Purpose-Ready pack adds the operation files. Data files are not put in the pack; the manifest points to them by address and SHA-256 checksum. The detailed structure is set by the operating guideline and explained in Pack structure and distribution.
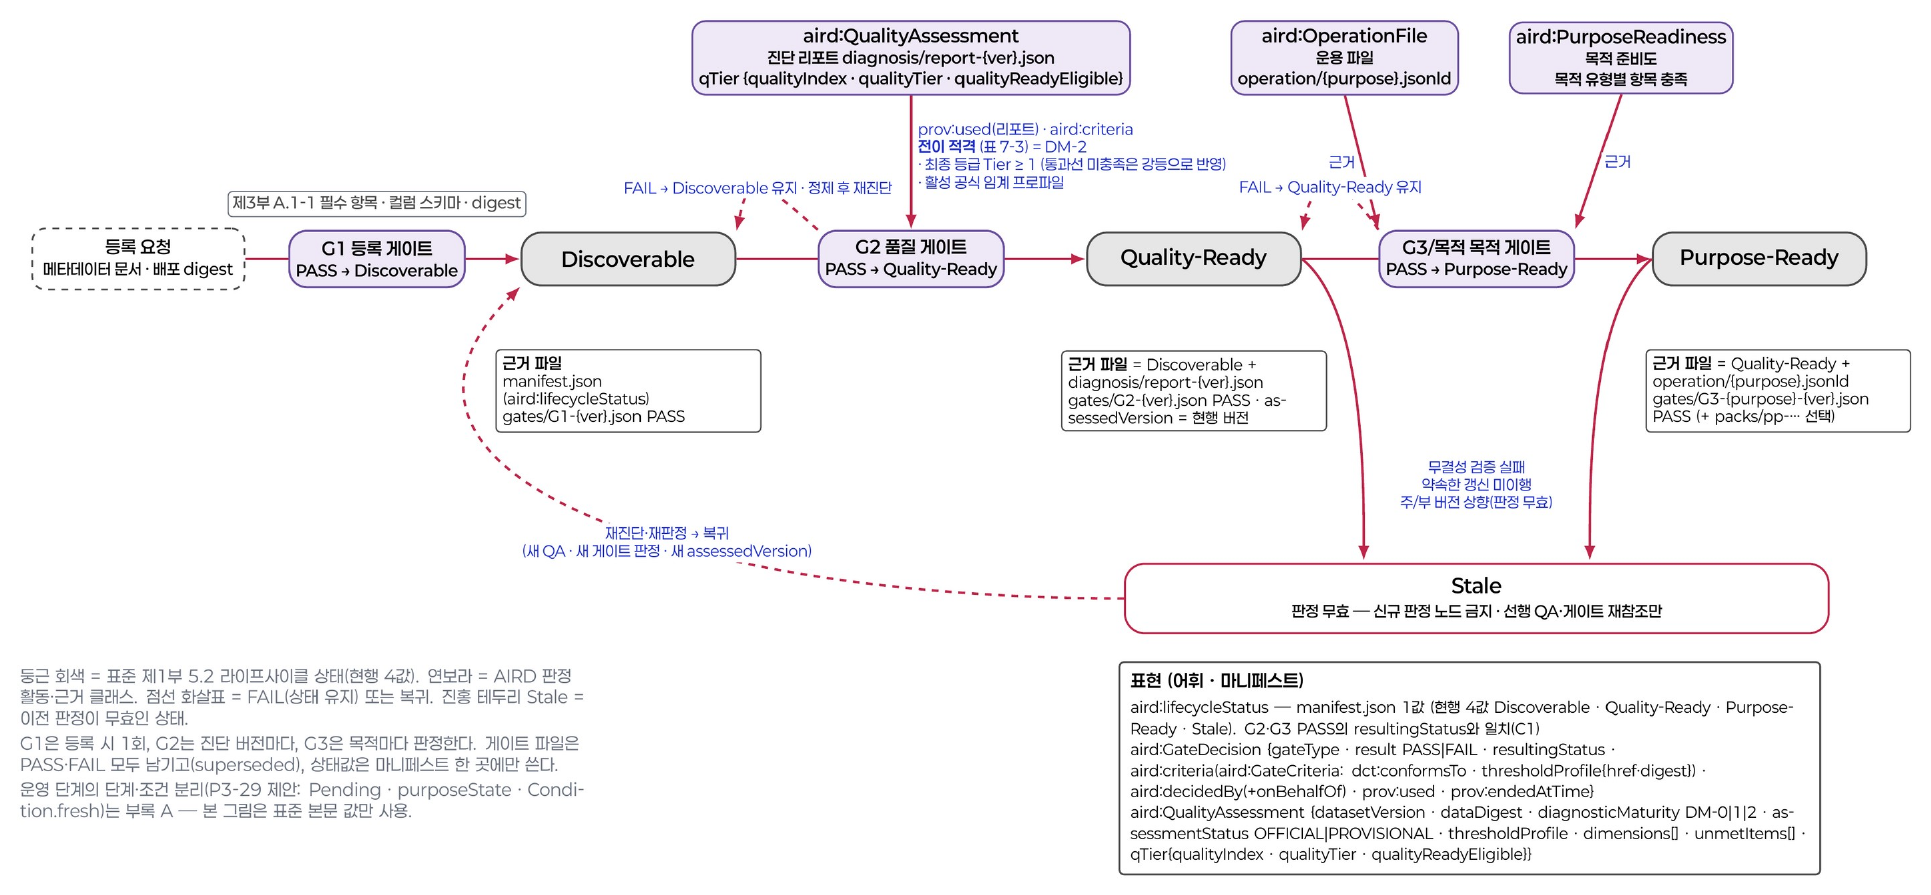
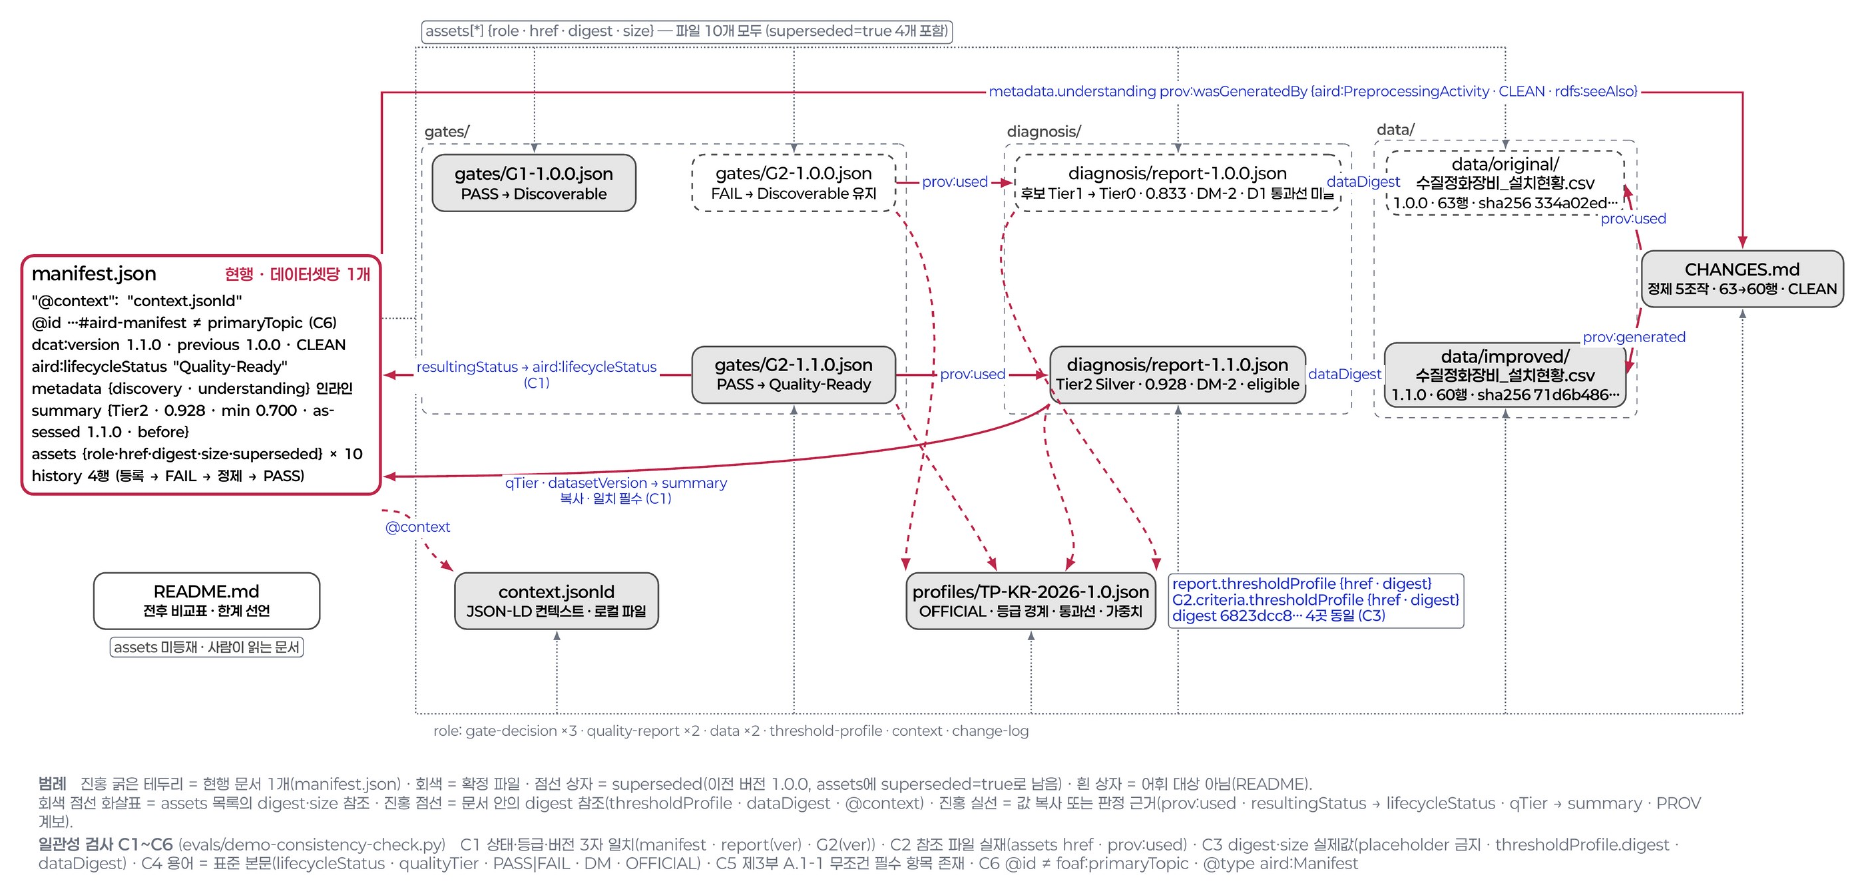
Roles
The work is shared by three parties. The data provider prepares and checks the materials, corrects values that can be corrected, and records limits that cannot. The diagnostic tool calculates scores, calculates tiers with the threshold profile of the operating guideline, drafts the diagnostic report and manifest, and calculates checksums. The operating guideline publisher builds, publishes and updates operating guidelines and threshold profiles, and publishes the tiers and transition judgments made under the applied guideline. Neither the data provider nor the diagnostic tool decides the judgment criteria.
There is more than one operating guideline publisher. The standard publishes the operating guideline provided with the standard when it is established (expected December 2026), and organizations, institutions and domains can build operating guidelines independently. The division of work by stage is in the workflow of each guide page (for example, Quality measurement and diagnostic report (stage 2)).
Division of work by party
| Party | Does | Does not |
|---|---|---|
| Data provider | Prepares and checks materials · corrects values that can be corrected · records limits that cannot be corrected | Calculate scores · calculate tiers · decide judgment criteria |
| Diagnostic tool | Calculates scores · calculates tiers with the threshold profile of the operating guideline · drafts the diagnostic report and manifest · calculates checksums | Decide judgment criteria · judge limits |
| Operating guideline publisher (guideline provided with the standard · organizations · institutions · domains) | Builds, publishes and updates operating guidelines and threshold profiles · publishes tiers and transition judgments under the applied guideline | Create data · correct values |
Next step: Judgment procedure
Basis: Part 1 3.1, 3.15, 5.1, 5.2, 5.5 · Part 2 5.2, 6.2, 7.1, 7.3, 7.5, 8.1, 9, Annex A.2, A.3, B.5 · Part 3 5.1, 8, C.6
Judgment procedure
Contents
ContentsThis page explains the rules for judging Diagnostic Maturity and the quality tier. The diagnostic tool does the calculation and an operating guideline separate from the standard sets the criteria, so data providers do not perform this procedure themselves.
Diagnostic Maturity decision table
Diagnostic Maturity (DM) shows how far the required indicators have been measured. The diagnostic tool applies the table below from the top and ends the judgment at the first row that is met.
| Order | Condition | Judgment |
|---|---|---|
| 1 | Diagnosis status exception: SCHEMA_ONLY (empty file) or FILE_BROKEN (corrupted file) | Not judged |
| 2 | All applicable required formal indicators are APPLIED | DM-2 |
| 3 | All applicable minimum measurable indicators (MMI) are APPLIED · evaluation coverage is at or above the operating guideline’s lower bound | DM-1 |
| 4 | All applicable MMIs are APPLIED | DM-0 |
| 5 | All other cases | DM-0 not met |
There are four MMIs, D5-03 · D6-01 · D7-01 · D7-02, and only those that apply to the data type are counted. If any required formal indicator is only partially measured (PARTIALLY_APPLIED), DM-2 is not met.
Evaluation coverage
Evaluation coverage is a value from 0 to 1 used to judge DM-1. It is calculated as follows.
Σ statusFactor(applicable required formal indicators) / n(required formal indicators excluding NOT_APPLICABLE)
statusFactor is a value fixed for each applicability status of an indicator (see the indicator applicability table in Status and judgment values), and NOT_APPLICABLE indicators are excluded from the denominator. The lower bound for DM-1 is set by the threshold profile (judgment criteria) of the operating guideline.
Evaluation coverage example
Example STRUCT (tabular) data has 13 required formal indicators. If one of them is NOT_APPLICABLE, the denominator is 12. If the statusFactor sum is 7 (for example, 7 APPLIED and the rest PRECONDITION_UNMET), evaluation coverage is 7/12 ≈ 0.58. Whether DM-1 is met is judged by comparing this value with the operating guideline’s lower bound.
Measurement without an operating guideline
Measurement works even without an operating guideline. D5-03 (Statistical plausibility) takes its dummy-value patterns from the threshold profile of the operating guideline, so without a guideline the diagnostic tool measures D5-03 provisionally with the example patterns in Part 2 Appendix I and records the evaluation status as PROVISIONAL. D6-01 (Uniqueness) has no precondition; if there is no identifying column, fully identical records are counted across the combination of all columns. All four MMIs can therefore be measured from the file alone, and DM-0 in row 4 of the decision table is met.
DM-1 can only be judged with the operating guideline’s lower bound for evaluation coverage, so without a guideline DM-1 is not judged. The quality tier is also judged only when an operating guideline is applied. The operating guideline provided with the standard is to be published when the standard is established (expected December 2026), and organizations, institutions and domains can build their own operating guidelines and judge with them. The status of the example threshold profile (Appendix I) is EXAMPLE; it is used for provisional calculation and tool development, not for tier judgment.
Reach by data type
The table below shows the Diagnostic Maturity each data type reaches without an operating guideline. In that case the quality tier is “Not judged: no operating guideline applied” regardless of Diagnostic Maturity, and because there is no lower bound for evaluation coverage, DM-1 is not judged for any data type.
| Data type | Required formal indicators | Diagnostic Maturity without an operating guideline | Reason |
|---|---|---|---|
STRUCT tabular | 13 | at least DM-0 (provisional) | Row 4 met by measuring the 4 MMIs. The examples lacked external data, so some required indicators were not measured |
TSERIES time series | 13 | at least DM-0 (provisional) | Row 4 met by measuring the 4 MMIs. The examples lacked external data, so some required indicators were not measured |
TEXT documents | 5 | DM-2 (when all 5 required formal indicators are measured) | If all 5 required formal indicators are APPLIED, row 2 of the decision table is met |
PT instruction–response pairs | 8 | DM-0 | D3-02 (Label accuracy) needs expert review results |
IMAGE images | 3 | DM-0 | D3-02 (Label accuracy) needs expert review results |
Tier judgment steps
The diagnostic tool first checks two preconditions. If they are not met, it does not judge a tier and records the reason below.
| Precondition | Record when not met |
|---|---|
| Operating guideline applied | Not judged: no operating guideline applied |
| Diagnostic Maturity DM-2 | Not judged: below DM-2 |
When both preconditions are met, the candidate tier is set from the lowest dimension score and lowered by one tier if any dimension misses its pass line.
- Find the minimum dimension score: take the lowest of the seven dimension scores in the diagnostic report.
- Set the candidate tier: the tier band of the threshold profile that contains the minimum dimension score becomes the candidate tier.
- Check the per-dimension pass lines: compare the seven dimension scores with the per-dimension required pass lines of the threshold profile and list the dimensions that fall short.
- Demotion: if any dimension falls short, lower the candidate tier by one and record the reason for demotion.
- Record the final tier: record the final tier (for example,
Gold (Tier 3, STRUCT)) and the identifier · version of the operating guideline applied.
Averages (simple or weighted) are not used in tier judgment. Tier bands and per-dimension required pass lines are set by the threshold profile of the operating guideline; its items are listed in Building an operating guideline. The tier names are Tier 0 Unqualified, Tier 1 Bronze, Tier 2 Silver, Tier 3 Gold and Tier 4 Platinum.
Quality-Ready transition conditions
At decision gate G2, data transitions to the Quality-Ready state (quality-checked data) when all of the conditions below are met. States and decision gates are defined in Key concepts.
- Diagnostic Maturity DM-2
- Quality tier Tier 1 or higher
- Threshold profile of an operating guideline applied
- Transition judged at decision gate G2
Tier labels
| Kind | Format | Example |
|---|---|---|
| Quality tier | <tier name> (Tier N, <data type>[, additional status]) | Gold (Tier 3, STRUCT) |
| Purpose tier | P-Tier N (<use purpose type>) | P-Tier 2 (KG) |
A quality tier must always state the data type with the tier name, and a purpose tier always carries the P- prefix. Diagnostic Maturity (DM) is not part of the tier label; it is recorded as a separate item in the diagnostic report. A tier is recorded together with the identifier · version of the operating guideline applied.
Basis: Part 1 7.1, Annex A · Part 2 5.1, 6, 6.2, 7, 7.3, 7.5, Annex A.3, A.4.1, B.5 Table B.4, Appendix I
Glossary
Contents
ContentsA lookup table that pairs the standard’s terms with the plain terms used on this site. The explanations are not normative definitions; normative definitions follow the “Terms and definitions” clause of each part.
Readiness states and decision gates
| Standard term | Plain term | Explanation | Clause |
|---|---|---|---|
| AI-Ready Data (AIRD) Korean: AI 레디 데이터 | AI-ready data (AIRD, pronounced “aird”) | Data in the Quality-Ready (quality-checked) or Purpose-Ready (prepared for a purpose) state that meets the common readiness requirements for AI use. The abbreviation AIRD is pronounced “aird”. | [Part 1 3.1] |
| Discoverable Korean: 디스커버러블 | Findable data | The state in which the required metadata elements of the discovery layer are in place. The result of stage 1. | [Part 1 5.2] |
| Quality-Ready Korean: 퀄리티 레디 | Quality-checked data | The state with Diagnostic Maturity DM-2 and a tier of Tier 1 or higher judged with an operating guideline. The result of stage 2. | [Part 1 5.2] |
| Purpose-Ready Korean: 펄포즈 레디 | Data prepared for a purpose | The state of being prepared to the criteria of a specific use purpose. The result of stage 3. | [Part 1 5.2] |
| Stale Korean: 스테일 | Suspended state | The state in which a readiness state is suspended because of an update delay or a checksum mismatch. The data returns to its state after it is updated and revalidated. | [Part 1 5.2] |
| Decision gate (G1 · G2 · G3) Korean: 결정 게이트 | Checkpoint | The point at the end of each stage where it is judged whether the data can transition to the next state. | [Part 1 5.2] |
Outputs
| Standard term | Plain term | Explanation | Clause |
|---|---|---|---|
| Manifest Korean: 마니페스트 | Data description | A document that describes a dataset in machine-readable form. A new one is issued for each version and points to the previous version. | [Part 3] |
| Diagnostic report Korean: 진단 리포트 | Results report | A JSON document created anew at each measurement. This site calls it the “diagnostic report”. | [Part 2 9] |
| Operation file Korean: 운용 파일 | Per-purpose operation file | A preparation output created separately for each use purpose. | [Part 3 8] |
| Pack Korean: 팩 | Bundle | The unit of distribution. A Quality-Ready pack consists of the manifest · diagnostic report · pack manifest; a Purpose-Ready pack adds operation files. Data files are not put in the pack; they are referenced by address and SHA-256 checksum. | [Part 1 3.15 · 5.5 · Part 3 5.1] |
Quality judgment
| Standard term | Plain term | Explanation | Clause |
|---|---|---|---|
| Quality dimension (D1–D7) Korean: 품질 차원 | Seven dimensions | Completeness · Consistency · Accuracy · Timeliness · Validity · Uniqueness · Machine readability. | [Part 2 5.2] |
| Quality tier (Q-Tier, aird:qualityTier, Tier 0–4) Korean: 품질 등급 | Quality tier | The quality level judged with the threshold profile of an operating guideline. Not judged when no operating guideline is applied. | [Part 2 7.1 · Part 3 C.6] |
| Diagnostic Maturity (DM-0 · DM-1 · DM-2) Korean: 진단 성숙도 | Measurement completeness | A graded judgment, made with a decision table, of how far the required indicators have been measured. It is not added to quality scores. | [Part 2 8.1 · Annex B.5] |
| Diagnostic Maturity decision table Korean: 측정 완성도 결정표 · Table B.4 | Decision table | A five-row table that determines Diagnostic Maturity. Reading from the top, the first row that is met is the result. The full table is in Judgment procedure. | [Part 2 Annex B.5 Table B.4] |
| Evaluation coverage Korean: 평가 범위 | Measurement coverage | A value from 0 to 1: the sum of statusFactor over the applicable required formal indicators divided by the number of indicators. For DM-1 it is compared with the operating guideline’s lower bound. | [Part 2 Annex A.3 · B.5] |
| Minimum measurable indicator (MMI) Korean: 최소 측정 가능 지표 | Minimum indicators | The four indicators that are the entry requirement for diagnosis (D5-03 · D6-01 · D7-01 · D7-02). They need the least input. Only those that apply to the data type are measured. | [Part 2 Annex A.2] |
| Minimum dimension score Korean: 최소 차원 점수 | Lowest score | The lowest of the seven dimension scores. The starting point for finding the candidate tier. Averages are not used in tier judgment. | [Part 2 6.2] |
| Demotion Korean: 강등 | One-tier drop | Moving down one tier from the candidate tier because a dimension falls below its required pass line in the threshold profile. | [Part 2 7.3] |
| Transition eligibility Korean: 전이 적격성 | Ready to move on | The state of having both Diagnostic Maturity DM-2 and a tier of Tier 1 or higher judged with an operating guideline. | [Part 2 7.5] |
Use purposes
| Standard term | Plain term | Explanation | Clause |
|---|---|---|---|
| Purpose tier (P-Tier, aird:purposeTier, P-Tier 1–3) Korean: 목적 등급 | Purpose tier | The readiness level judged against the criteria registered for each use purpose. | [Part 3 C.7] |
Operating guidelines
| Standard term | Plain term | Explanation | Clause |
|---|---|---|---|
| Operating guideline | Judgment criteria document | A document that holds the judgment criteria. The standard provides one, and organizations, institutions and domains can build their own independently. The operating guideline provided with the standard is to be published when the standard is established (expected December 2026). It holds the threshold profile and operational matters (diagnosis cycle · result validity period · objection procedure · tool certification). | [Part 1 7.1] |
| Threshold profile Korean: 임계 프로파일 | Judgment thresholds | The values that set weights · tier bands · pass lines · lower bounds · indicator parameters. Part of an operating guideline. Its status is OFFICIAL or EXAMPLE; EXAMPLE is not used for tier judgment. | [Part 2 Annex D · Table 9-3] |
| Guideline publisher | Organization that builds and issues a guideline | The organization, institution or domain that builds and issues an operating guideline. There is more than one publisher. Whoever judges and publishes a tier also publishes the operating guideline applied and states its identifier · version with the tier. | — |
| Registered profile Korean: 등록 상태 프로파일 | Per-purpose criteria | The judgment criteria registered for each use purpose. A purpose tier is not judged before the criteria are registered. | [Part 3 8.2] |
Standard documents
| Standard term | Plain term | Explanation | Clause |
|---|---|---|---|
| Draft standard (TTAK draft · v0.95) Korean: 표준 초안 | TTAK draft (v0.95) | The draft standard comprising Part 1 “Overview and framework” · Part 2 “Quality measurement and tiering” · Part 3 “Dataset description schema and application profile”. Parts 1–5 were proposed to TTA as a standard on 2026-05-13, and review is under way at regular TTA meetings. It focuses on the required elements. | — |
| AIRD vocabulary (v0.10.5) Korean: 어휘표 | AIRD vocabulary v0.10.5 | The full list of elements, including external vocabularies. It matches the draft standard: the draft standard focuses on the required elements, and the vocabulary is the full list. | — |
Data types
| Standard term | Plain term | Explanation | Clause |
|---|---|---|---|
| Structured (STRUCT) Korean: 정형 | Tabular | Data with rows and columns and a defined data type for each column | [Part 1 5.6 Table 5-5] |
| Time series (TSERIES) Korean: 시계열 | Time series | Data that records values in time order. A special case of tabular data | [Part 1 5.6 Table 5-5] |
| Text (TEXT) Korean: 텍스트 | Documents | Data made of natural-language sentences and documents | [Part 1 5.6 Table 5-5] |
| Image (IMAGE) Korean: 이미지 | Images | Image files (for example, photos · drawings) | [Part 1 5.6 Table 5-5] |
| Paired text (PT) Korean: 페어형 텍스트 | Instruction–response pairs | Text data made of instruction–response pairs or preference pairs | [Part 1 5.6 Table 5-5 (draft standard)] |
Publishers and provision modes (site classification)
| Standard term | Plain term | Explanation | Clause |
|---|---|---|---|
| Public-sector data Korean: 공공 데이터 · publisher_sector: public | Data issued by public institutions | Data issued or provided by public institutions as defined in the Korean Public Data Act. It is classified by publisher, not by the subject the data covers. One of the targets of the standard | — |
| Enterprise data Korean: 기업 데이터 · publisher_sector: enterprise | Data issued by companies | Data that companies create or provide. If a company creates it and a public platform publishes it, it is classified by its creator (dct:creator, the company) | — |
| Non-profit data Korean: 민간 비영리 데이터 · publisher_sector: nonprofit | Data from associations · foundations · communities | Data issued by industry associations · foundations · communities | — |
| Open Korean: 개방 · provision_mode: open_license | Open under an open license | Provision that states its conditions of use with a standard license value (for example, KOGL · CC). Machines can read the conditions of use | — |
| Free access Korean: 무료 제공 · provision_mode: free_access | Free, but with its own terms | No charge, but its own terms of use apply. The terms may restrict redistribution or automated collection, and machines cannot read the conditions of use. Different from open | — |
| Commercial Korean: 유상 제공 · provision_mode: commercial | Contract · sale | Provided by contract · pay-per-use · sale on a data exchange. The price is recorded with dcatkr:fee · sc:offers | [vocabulary 1.4.5 · 1.4.6] |
Tier label rules
| Kind | Format | Example |
|---|---|---|
| Quality tier | <tier name> (Tier N, <data type>[, additional status]) | Gold (Tier 3, STRUCT) |
| Purpose tier | P-Tier N (<use purpose type>) | P-Tier 2 (KG) |
The quality tier names are Tier 0 Unqualified · Tier 1 Bronze · Tier 2 Silver · Tier 3 Gold · Tier 4 Platinum. Write tier labels according to the following rules.
- Always state the data type with the tier name.
- Always keep the P- prefix on a purpose tier.
- Record Diagnostic Maturity (DM) as a separate item in the diagnostic report, not in the tier label.
- State the identifier · version of the operating guideline applied next to the tier label, outside the label format (for example, Gold (Tier 3, STRUCT) · operating guideline example-guideline 1.0).
Basis: Part 1 Annex A (tier label rules) · clauses for each term are in the Clause column of each table
Metadata elements
Contents
ContentsA lookup table of the elements recorded in the manifest. There are 23 required discovery-layer elements (19 for the dataset + 4 per distribution), and distribution elements are recorded for each file.
The 23 follow the demo profile of AIRD vocabulary v0.10.5: the 19 required in the draft standard (15 for the dataset + 4 per distribution) plus 4 more, namely dataset structure type · theme · landing page · maintaining department. Theme and landing page are required for public-sector data and recommended for other data. The discovery layer is written in stage 1 and the understanding layer in stage 2.
Draft standard and vocabulary
The draft standard and the vocabulary are consistent. The draft standard focuses on the required elements, while the vocabulary is the complete list, including external vocabularies.
Discovery layer · 19 required dataset elements
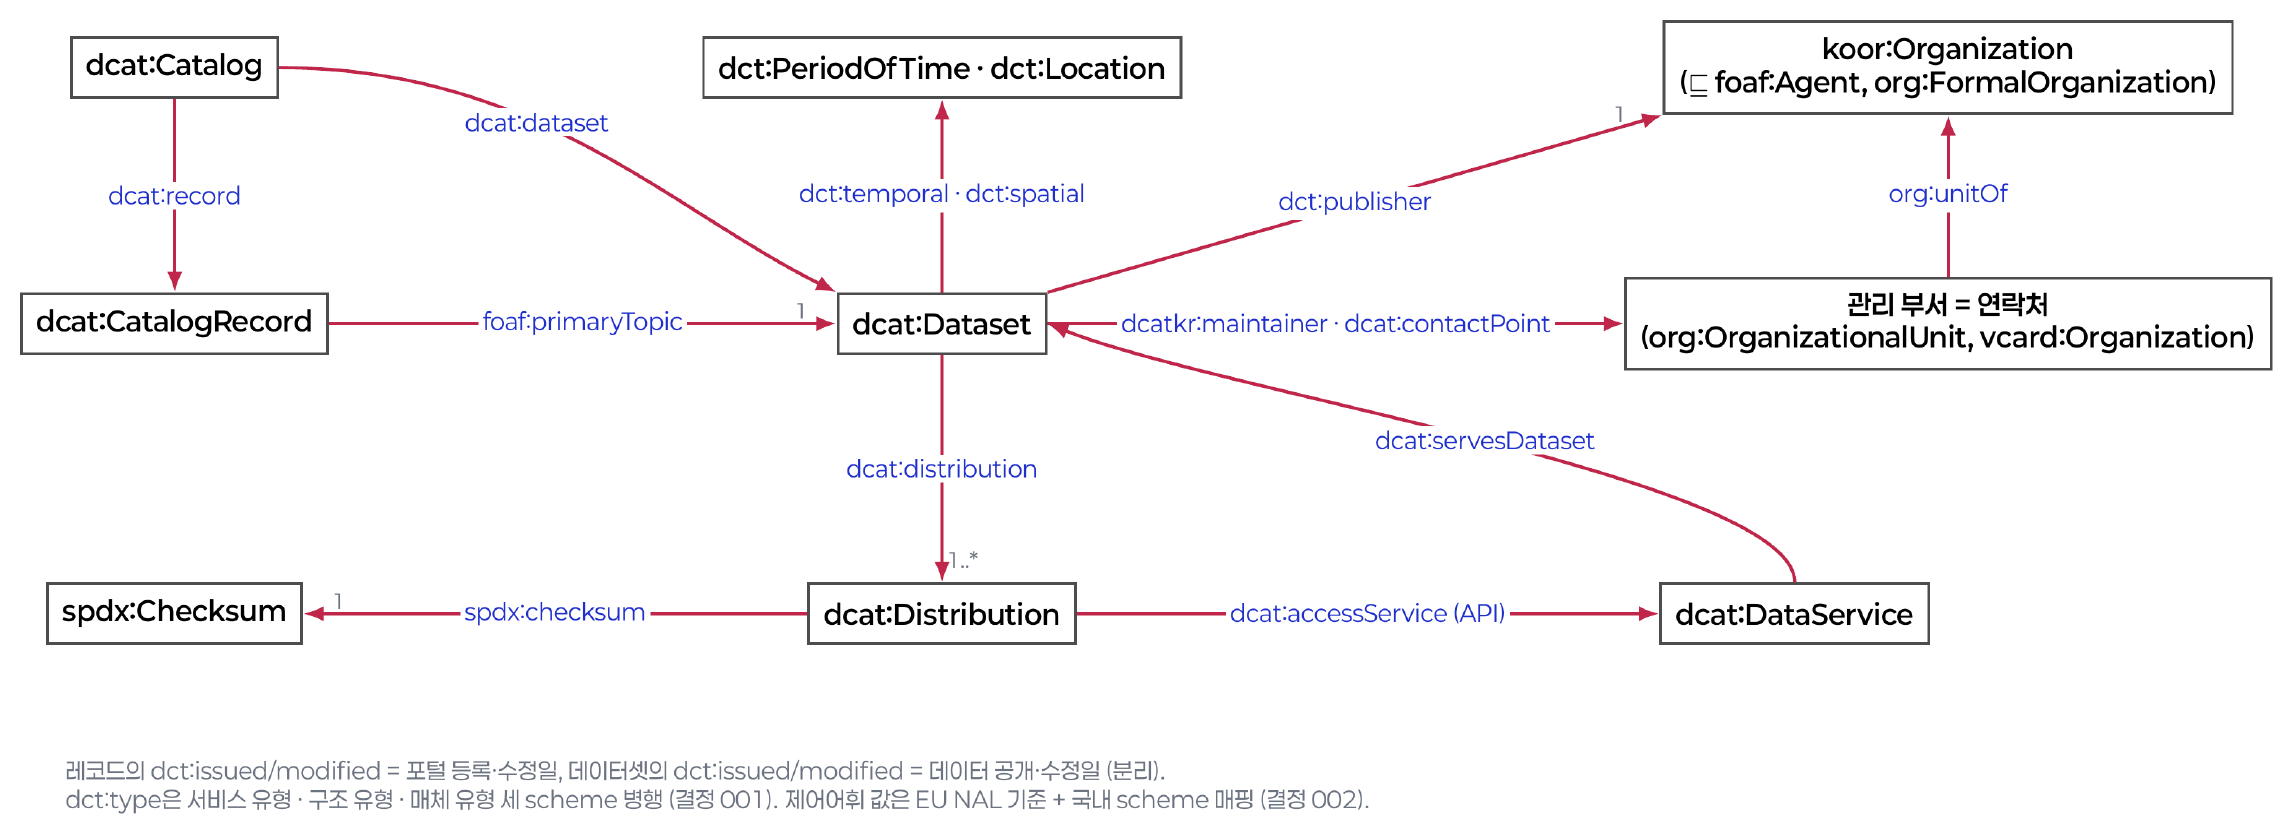
| # | Element | Property | Cardinality | Value range · criteria | Filled in by |
|---|---|---|---|---|---|
| 1 | Dataset identifier | dct:identifier | 1 | Persistent identifier URI · immutable | Organizational policy |
| 2 | Title | dct:title | 1 | String (@ko) | Data provider |
| 3 | Description | dct:description | 1 | String | Data provider |
| 4 | Keyword | dcat:keyword | 3..* | 3 or more | Data provider |
| 5 | Data service type | dct:type | 1 | Controlled vocabulary http://vocab.datahub.kr/def/dcat-ap-kr/service-type/ | Data provider |
| 6 | Dataset structure type | dct:type | 1 or more | Controlled vocabulary http://vocab.datahub.kr/def/aird/dataset-type/ | Data provider |
| 7 | Language | dct:language | 1 or more | Controlled vocabulary http://publications.europa.eu/resource/authority/language/ | Data provider |
| 8 | Lifecycle status | aird:lifecycleStatus | 1 | Controlled vocabulary http://vocab.datahub.kr/def/aird/lifecycle-status/ | Data provider |
| 9 | Theme Required · public sector (recommended otherwise) | dcat:theme | 1 | Controlled vocabulary http://vocab.datahub.kr/def/dcat-ap-kr/data-theme/ | Data provider |
| 10 | Landing page Required · public sector (recommended otherwise) | dcat:landingPage | 1 | URL of the dataset detail page | Data provider |
| 11 | Creator | dct:creator | 1 or more | URI or organization name | Data provider |
| 12 | Publisher | dct:publisher | 1 | URI or organization name | Data provider |
| 13 | Maintaining department | dcatkr:maintainer | 1 or more | Department name | Data provider |
| 14 | Contact point | dcat:contactPoint | 1 or more | Name and email | Data provider |
| 15 | Creation method | aird:creationMethod | 1 | Controlled vocabulary http://vocab.datahub.kr/def/aird/creation-method/ | Data provider |
| 16 | Update frequency | dct:accrualPeriodicity | 1 | Controlled vocabulary http://publications.europa.eu/resource/authority/frequency/ | Data provider |
| 17 | License | dct:license | 1 | Controlled vocabulary http://vocab.datahub.kr/def/dcat-ap-kr/license/ | Data provider |
| 18 | Rights | dct:rights | 1 | Notice of the scope of use | Data provider |
| 19 | Access rights | dct:accessRights | 1 | Controlled vocabulary http://publications.europa.eu/resource/authority/access-right/ | Data provider |
Discovery layer · 4 required elements per distribution
If the data is distributed in several forms, each distribution (dcat:Distribution) is described separately, so the number of discovery-layer values is 19 + 4 × (number of distributions).
| Element | Property | Value range | Filled in by |
|---|---|---|---|
| Access URL | dcat:accessURL | URI | Data provider |
| Media type | dcat:mediaType | IANA Media Type | Diagnostic tool |
| File format | dct:format | EU File Type code (e.g., CSV) | Data provider |
| Checksum | spdx:checksum | SHA-256 (computed from the file) | Diagnostic tool |
Conditionally required
| Element | Property | Condition |
|---|---|---|
| Column schema | csvw:tableSchema | Structured data |
| De-identification level | aird:deidentificationLevel | Contains personal data |
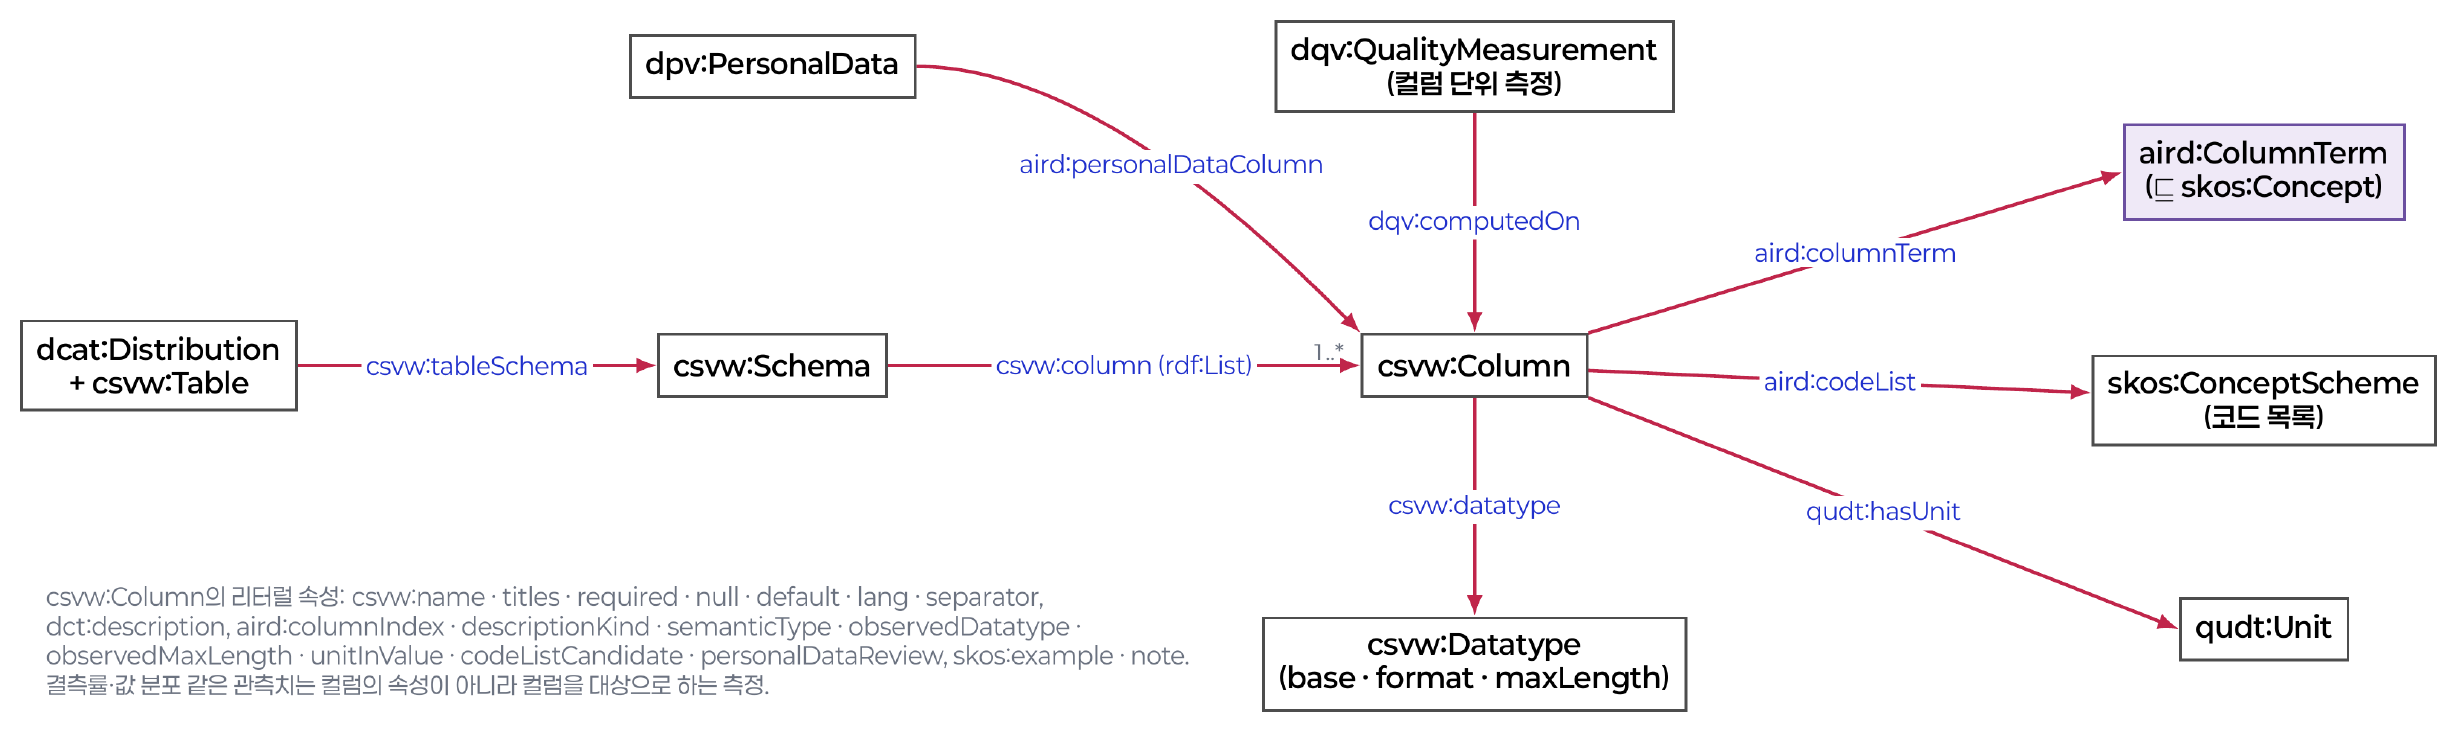
csvw:tableSchema) of structured data is described on the distribution (csvw:Table). Each column has a name, a datatype and a description, and AIRD extends the elements (for example, unit and code system).Source: AIRD information model v0.10.5, page 22 · click for full sizeUnderstanding layer · key elements
Grouping and cardinalities follow vocabulary v0.10.5. Within a group such as the quality assessment (aird:QualityAssessment) or the decision gate record, “required” applies when that group is written. Elements the data provider fills in directly are shown in bold.
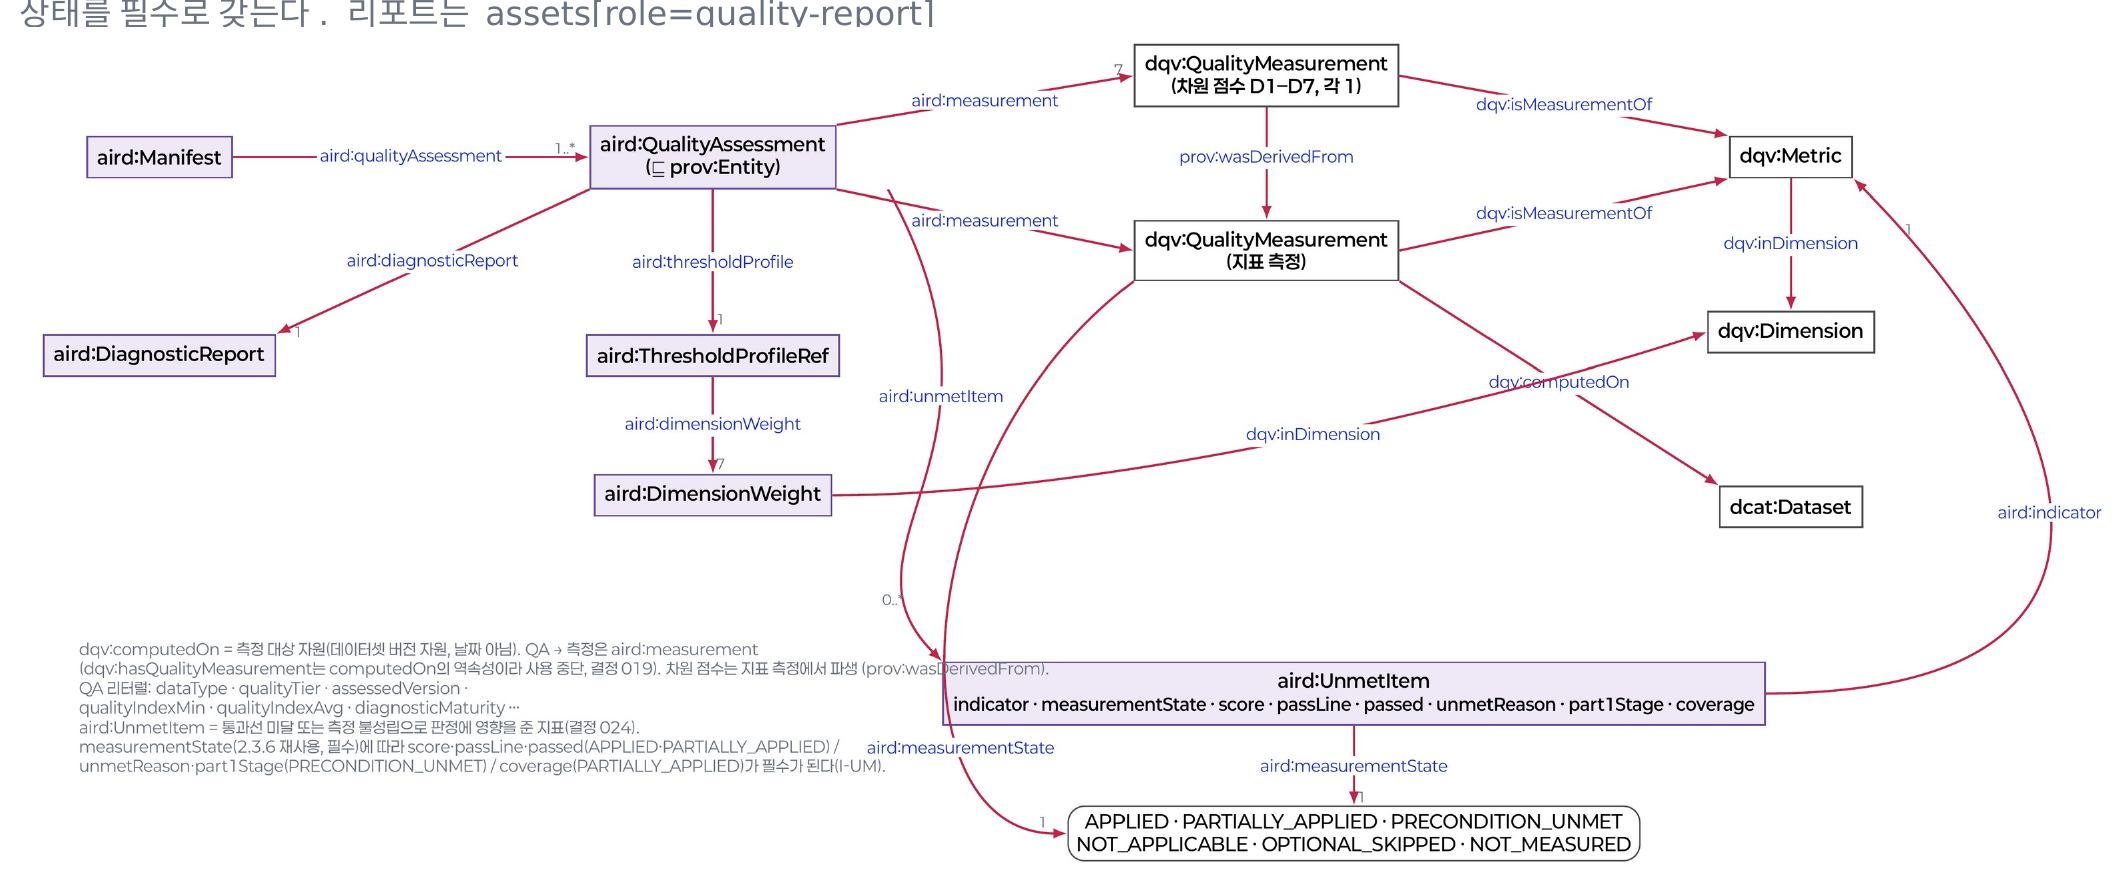
Version · history
| Element | Property | Vocabulary (number · obligation · cardinality) | Filled in by |
|---|---|---|---|
| Version number | dcat:version | 2.1.1 · required · 1..1 | Diagnostic tool |
| Issue date | dct:issued | 1.2.16 · conditionally required · Quality-Ready or higher · 0..1 | Diagnostic tool |
| Last modified date | dct:modified | 1.2.17 · conditionally required · Quality-Ready or higher · 0..1 | Diagnostic tool |
| Version notes | adms:versionNotes | 2.1.2 · required · 1..1 (per language) | Data provider |
| Previous version | dcat:previousVersion | 2.1.3 · conditionally required · rule A new version · 0..1 | Diagnostic tool |
Quality assessment — 2.2.1 conditionally required · lifecycleStatus = Quality-Ready
| Element | Property | Vocabulary (number · obligation · cardinality) | Filled in by |
|---|---|---|---|
| Data type | aird:dataType | 2.2.2 · required · 1..1 | Diagnostic tool |
| Quality tier | aird:qualityTier | 2.2.3 · required · 1..1 | Diagnostic tool |
| Minimum dimension score | aird:qualityIndexMin | 2.2.9 · required · 1..1 | Diagnostic tool |
| Weighted average | aird:qualityIndexAvg | 2.2.10 · required · 1..1 | Diagnostic tool |
| Minimum measurable indicator score | aird:qualityIndexMMI | 2.2.11 · conditionally required (at DM-0) · 0..1 | Diagnostic tool |
| Diagnostic Maturity | aird:diagnosticMaturity | 2.2.12 · conditionally required · 0..1 | Diagnostic tool |
| Transition eligibility | aird:qualityReadyEligible | 2.2.14 · conditionally required · when judging Quality-Ready · 0..1 | Diagnostic tool |
| Diagnosis time | prov:generatedAtTime | 2.2.15 · required · 1..1 | Diagnostic tool |
| Judgment rule version | aird:ruleVersion | 2.2.17 · required · 1..1 | Diagnostic tool |
| Schema version | aird:schemaVersion | 2.2.18 · required · 1..1 | Diagnostic tool |
| Diagnostic report | aird:diagnosticReport | 2.2.19 · required · 1..1 | Diagnostic tool |
| Threshold profile | aird:thresholdProfile | 2.2.20 · required · 1..1 | Diagnostic tool |
Dimension scores — 2.3.1 quality measurement · required · one each for D1–D7
| Element | Property | Filled in by |
|---|---|---|
| Completeness | dqv:QualityMeasurement · dimension D1 (Completeness) | Diagnostic tool |
| Consistency | dqv:QualityMeasurement · dimension D2 (Consistency) | Diagnostic tool |
| Accuracy | dqv:QualityMeasurement · dimension D3 (Accuracy) | Diagnostic tool |
| Timeliness | dqv:QualityMeasurement · dimension D4 (Timeliness) | Diagnostic tool |
| Validity | dqv:QualityMeasurement · dimension D5 (Validity) | Diagnostic tool |
| Uniqueness | dqv:QualityMeasurement · dimension D6 (Uniqueness) | Diagnostic tool |
| Machine readability | dqv:QualityMeasurement · dimension D7 (Machine readability) | Diagnostic tool |
Structural · semantic readiness
| Element | Property | Vocabulary (number · obligation · cardinality) | Filled in by |
|---|---|---|---|
| Feature completeness index | aird:featureCompletenessIndex | 2.4.1 · recommended · 0..1 | Diagnostic tool |
| Schema conformance rate | aird:schemaConformanceRate | 2.4.2 · recommended · 0..1 | Diagnostic tool |
| Label conformance rate | aird:labelConformanceRate | 2.4.3 · conditionally required · supervised learning · 0..1 | Diagnostic tool |
Trust · ethics
| Element | Property | Vocabulary (number · obligation · cardinality) | Filled in by |
|---|---|---|---|
| Known biases | rai:dataBiases | 2.5.1 · required · 1..* | Data provider |
| Known limitations | rai:dataLimitations | 2.5.2 · required · 1..* | Data provider |
| Missing data information | rai:dataCollectionMissingData | 2.5.3 · required · 1..1 | Data provider |
| Synthetic data flag | aird:isSynthetic | 2.5.9 · required · 1..1 | Data provider |
Provenance
| Element | Property | Vocabulary (number · obligation · cardinality) | Filled in by |
|---|---|---|---|
| Source data | prov:wasDerivedFrom | 2.6.1 · conditionally required · rule B derived dataset · 0..* | Data provider |
| Collection method | aird:collectionMethod | 1.2.12 · conditionally required · Quality-Ready or higher · 0..1 | Data provider |
| Preprocessing activity | prov:wasGeneratedBy | 2.6.2 · conditionally required · preprocessingLevel ≠ NONE or derived dataset: 1..*; otherwise 0..* · 0..* | Diagnostic tool |
| Transformation history | prov:wasGeneratedBy | 2.6.3 · conditionally required · purposeState = ready · 0..* | Diagnostic tool |
Decision gate judgment record
| Element | Property | Vocabulary (number · obligation · cardinality) | Filled in by |
|---|---|---|---|
| Gate type | aird:gateType | 2.7.2 · required · GD · 1..1 | Diagnostic tool |
| Gate result | aird:gateResult | 2.7.3 · required · GD · 1..1 | Diagnostic tool |
| Judgment time | prov:endedAtTime | 2.7.4 · required · GD · 1..1 | Diagnostic tool |
| Resulting status | aird:resultingStatus | 2.7.5 · conditionally required · G1·G2 PASS · 0..1 | Diagnostic tool |
Purpose readiness
| Element | Property | Vocabulary (number · obligation · cardinality) | Filled in by |
|---|---|---|---|
| Purpose readiness | aird:purposeReadiness | 2.8.1 · conditionally required · a purpose with purposeState = ready exists · 0..* | Diagnostic tool |
| Purpose assessment status | aird:purposeAssessmentStatus | 2.8.8 · conditionally required · an unjudged type exists · 0..* | Diagnostic tool |
Security · privacy
| Element | Property | Vocabulary (number · obligation · cardinality) | Filled in by |
|---|---|---|---|
| Contains personal data | aird:containsPersonalData | 2.9.1 · required · 1..1 | Data provider |
| Contains sensitive data | aird:containsSensitiveData | 2.9.3 · conditionally required · if it contains personal data · 0..1 | Data provider |
| De-identification level | aird:deidentificationLevel | 1.4.8 · conditionally required · contains personal data · 0..1 | Data provider |
Value lists
Values for the following elements are chosen from a fixed list rather than written as free strings.
| Element | Values | Source |
|---|---|---|
data_type | STRUCT · TEXT · IMAGE · TSERIES · PT | [Part 1 5.6 Table 5-5] |
lifecycle_status | Discoverable · Quality-Ready · Purpose-Ready · Stale | |
creation_method | collected collected · processed processed · synthetic synthetic · augmented augmented | |
access_rights | PUBLIC public · RESTRICTED restricted · NON_PUBLIC non-public | EU Publications Office · Access right authority table |
language | e.g., KOR Korean · ENG English | EU Publications Office · Language authority table |
media_type | e.g., text/csv · application/json · image/jpeg | IANA Media Types |
license | KOGL-0 · KOGL-1 · KOGL-2 · KOGL-3 · KOGL-4 · KOGL-AI · NO-RESTRICTION · CC-BY-4.0 · CC-BY-SA-4.0 · CC-BY-ND-4.0 · CC-BY-NC-4.0 · CC-BY-NC-SA-4.0 · CC-BY-NC-ND-4.0 · CC0-1.0 | vocabulary v0.10.5 1.4.1 · kr-license (DCAT-AP-KR integrated vocabulary · proposed) — reference vocabulary KOGL-THIRD-PARTY (includes third-party rights) is a rights status, not a license, so the vocabulary removed it from the dct:license values (deprecated) — state it in the dct:rights notice. The draft standard and the vocabulary are consistent. The draft standard focuses on the required elements, while the vocabulary is the complete list, including external vocabularies. Enterprise terms of use, MIT, Apache and similar licenses have no value in this list — extending the value space is a proposed revision of the vocabulary |
frequency | e.g., ANNUAL · QUARTERLY · MONTHLY · DAILY · IRREG | EU Publications Office · Frequency authority table |
Update frequency — data provider input and manifest value
| Data provider input | Manifest value |
|---|---|
| Updated once a year | http://publications.europa.eu/resource/authority/frequency/ANNUAL |
| Updated quarterly | http://publications.europa.eu/resource/authority/frequency/QUARTERLY |
| Updated once a month | http://publications.europa.eu/resource/authority/frequency/MONTHLY |
| Updated daily | http://publications.europa.eu/resource/authority/frequency/DAILY |
| As needed · irregular | http://publications.europa.eu/resource/authority/frequency/IRREG |
Other values
| Data provider input | Manifest value |
|---|---|
| KOGL Type 1 (Korea Open Government License) | KOGL-1 |
| CC BY 4.0 | CC-BY-4.0 |
| Enterprise terms of use (redistribution · automated collection restricted) | No value in the list — write the name and effective date of the terms in rights (dct:rights) |
| CSV file | text/csv |
| JSON file | application/json |
| Anyone can view | http://publications.europa.eu/resource/authority/access-right/PUBLIC |
| Approved organizations · contract customers only | http://publications.europa.eu/resource/authority/access-right/RESTRICTED |
| Data produced by survey or measurement | collected |
| Processed from existing data | processed |
| Korean | http://publications.europa.eu/resource/authority/language/KOR |
Basis: Part 3 Annex A.1, A.2, Annex C
Quality indicators
Contents
ContentsA lookup table of how the 16 formal quality indicators apply to each data type, with their preconditions and formulas. All scores range from 0 to 1, and weights and tier bands follow the threshold profile of the operating guideline.
Application by data type
● means required formal · ○ optional · — not applicable. MMI is a minimum measurable indicator, an entry requirement for diagnosis.
| ID | Indicator | Dimension | STRUCT | TEXT | IMAGE | TSERIES | PT | |
|---|---|---|---|---|---|---|---|---|
D1-01 | Required field completeness | D1 Completeness | ● | ○ | ○ | ● | ● | |
D1-02 | Required metadata completeness | D1 Completeness | ● | ● | ● | ● | ● | |
D2-01 | Inter-field consistency | D2 Consistency | ● | — | — | ● | — | |
D2-02 | Referential integrity | D2 Consistency | ● | — | — | ● | — | |
D2-03 | Derived value accuracy | D2 Consistency | ● | — | — | ● | — | |
D3-01 | Standard name conformance | D3 Accuracy | ● | ○ | — | ○ | — | |
D3-02 | Label accuracy | D3 Accuracy | — | ○ | ● | — | ● | |
D4-01 | Currency | D4 Timeliness | ● | ● | ○ | ● | ● | |
D4-02 | Update fidelity | D4 Timeliness | ○ | ○ | — | — | ○ | |
D4-03 | Time series completeness | D4 Timeliness | — | — | — | ● | — | |
D5-01 | Format validity | D5 Validity | ● | ● | — | ● | ● | |
D5-02 | Numeric range validity | D5 Validity | ● | — | — | ● | — | |
D5-03 | Statistical plausibility | D5 Validity | MMI | ● | — | — | ● | — |
D6-01 | Uniqueness | D6 Uniqueness | MMI | ● | ○ | — | ● | ● |
D7-01 | Encoding consistency | D7 Machine readability | MMI | ● | ● | ○ | ● | ● |
D7-02 | Technical validity | D7 Machine readability | MMI | ● | ● | ● | ● | ● |
| Number of required formal indicators | 13 | 5 | 3 | 13 | 8 |
Preconditions and formulas by indicator
D1-01 Required field completeness — share of non-missing values in required columns
Precondition The list of required fields is defined in the column schema (csvw:tableSchema), in the metadata specification applied to the dataset, or in an equivalent document approved by the organization
Formula
(1 / |Freq|) × Σ_{f∈Freq} [ n(f ≠ NULL ∧ f ≠ '') / N ]Symbols Freq set of required fields · |Freq| number of required fields · N total number of records
D1-02 Required metadata completeness — share of required metadata elements filled in
Precondition The metadata specification applied to the dataset names the list of elements that serves as the denominator of this indicator. For a specification that does not name such a list, all required elements of that specification form the denominator
Formula
n(required metadata elements filled in) / n(all required metadata elements)D2-01 Inter-field consistency — compliance with relationship rules between two columns
Precondition The relationship rules are defined in one of the column schema (csvw:tableSchema), the metadata specification applied to the dataset, or an equivalent document approved by the organization
Formula
1 − ( n(records violating a rule) / N )D2-02 Referential integrity — whether code values appear in the code table
Precondition Values are checked against the actual values of the master code table. If only an address or reference exists and the values cannot be obtained, the judgment is precondition unmet (PRECONDITION_UNMET)
Formula
1 − ( n(unmapped code cells) / n(valid code cells) )Prerequisite indicator D5-01
D2-03 Derived value accuracy — whether stored derived values match the calculation rule
Precondition The calculation rule for derived values is defined in the schema, the column schema (csvw:tableSchema), or the metadata specification applied to the dataset. If there are no stored derived values, the judgment is not applicable (NOT_APPLICABLE)
Formula
1 − ( n(computed value ≠ stored value) / n(values checked) )D3-01 Standard name conformance — whether codes and names match the authoritative reference
Precondition An authoritative reference is available as a code-to-name mapping, and the data contains both codes and names
Formula
1 − ( n(code cells not matching the reference) / n(matched code cells) )Prerequisite indicator D2-02
D3-02 Label accuracy — share of labels matching the ground-truth labels
Precondition A set of ground-truth labels reviewed by experts exists. Automated measurement is not possible; the review results are used as input
Formula
n(matches) / n(items reviewed). For text and paired text, only an exact match counts as a matchD4-01 Currency — whether the data was updated within the stated update frequency
Precondition The update date and update frequency are recorded in the metadata
Formula
1.0 if days elapsed ≤ update interval. Otherwise max(0, 1 − (days elapsed − update interval) / grace period). The grace period equals the update interval in daysD4-02 Update fidelity — share of scheduled updates carried out
Precondition The update frequency and update history are stated in the metadata
Formula
n(updates carried out) / n(updates scheduled)D4-03 Time series completeness — whether time series measurement points are missing
Precondition The expected measurement points are stated in the metadata
Formula
n(actual measurement points) / n(expected measurement points)D5-01 Format validity — whether values follow the defined format
Precondition None. Columns without a defined format are excluded from measurement
Formula
1 − ( n(cells with format mismatch) / n(cells checked for format) )D5-02 Numeric range validity — whether numbers stay within the allowed range
Precondition An allowed range is defined for each column. If no column has a defined range, the judgment is precondition unmet (PRECONDITION_UNMET)
Formula
1 − ( n(out-of-range cells) / n(cells with a defined range) )D5-03 Statistical plausibility — whether dummy values or obviously wrong values are present
Precondition Dummy value patterns (indicator parameters in the threshold profile). Without an operating guideline, measurement is provisional using the example patterns in Part 2 Appendix I (Judgment procedure).
Formula
1 − ( n(cells with obviously wrong values) / n(numeric cells evaluated) )D6-01 Uniqueness — whether records are duplicated
Precondition None
Formula
n(unique keys) / N. If identifier columns are defined, duplicates of the same entity are measured; if not, the combination of all columns is used as the key and fully identical duplicate records are measuredD7-01 Encoding consistency — whether file encodings match the reference encoding
Precondition None
Formula
n(files using the reference encoding) / n(all files)D7-02 Technical validity — whether files open normally and have a valid structure
Precondition None
Formula
n(files that open normally ∧ meet the specification) / n(all files). A file meets the specification when parsing completes under the official specification of its file format and the required structure is validCalculation
| Value | Formula |
|---|---|
| Dimension score | Di = Σk (wk × Sk) / Σk wk |
| Minimum dimension score | min(Di) |
| Weighted average | Σi (Wi × Di) |
| Minimum measurable indicator score | Σ score(MMI) / n(MMI) |
| Weight redistribution | Wi′ = Wi / (1 − Wj) # Wj is the sum of the weights of the dimensions that could not be measured |
| Evaluation coverage | Σ statusFactor(applicable required formal indicators) / n(required formal indicators excluding NOT_APPLICABLE) |
Sk is the score of each required formal indicator for that data type whose measurement is complete. Optional and incomplete indicators are excluded from both numerator and denominator, and if a dimension has no completed formal indicator, Di is recorded as null.
Tier judgment starts from the minimum dimension score, not from the weighted average (Judgment procedure). Evaluation coverage is compared with the lower bound set in the operating guideline when judging Diagnostic Maturity DM-1.
Partial measurement
Partial measurement (PARTIALLY_APPLIED) applies to D2-02 · D3-01 · D5-02, and coverage = n(measurable targets) / n(identified measurement targets). Only targets that meet the precondition form the population, and targets that could not be measured are excluded from both numerator and denominator. The score is not multiplied by coverage again.
If any measurement is partial, DM-2 cannot be reached, and the upper limit of Diagnostic Maturity (DM) is DM-1.
Exclusivity — no double counting of the same defect across indicators
Each defect is counted only under the responsible indicator in the table below.
| Defect type | Responsible indicator |
|---|---|
| Format violation in a single field | D5-01 |
| Out-of-range value in a single field | D5-02 |
| Relationship violation between two fields | D2-01 |
| Mismatch in a calculation across multiple fields | D2-03 |
| Empty cell | D1-01 |
| Unmapped code | D2-02 |
Reference encoding
| Reference | Non-conforming | Not measured |
|---|---|---|
UTF-8 | EUC-KR · CP949 | Presence of a byte order mark · differences in line break characters |
Basis: Part 2 Annex A.1–A.4, B.1–B.6
Status and judgment values
Contents
ContentsThe judgment values recorded in the diagnostic report and the manifest. A result that cannot be judged is recorded as “Not judged” with a reason, not as a zero score or the lowest tier.
Layers
Diagnosis status · indicator applicability · Diagnostic Maturity (DM), as defined by the standard, are the base layers; the display layer only puts them into human-readable words and creates no new judgment.
| Layer | Question it answers | Normative | Clause |
|---|---|---|---|
| Diagnosis status | Can diagnosis begin? | Normative | [Part 2 Annex B.1 Table B.1] |
| Indicator applicability | Was the indicator measured, and if not, why? | Normative | [Part 2 Annex B.2 Table B.2] |
| Check result display | A single display value for the check result of each item (indicator · metadata element · requirement) | Display layer | — |
| Reasons for not judging | Why no judgment was made | Display layer (purpose tier reasons are standard codes) | [Part 3 Annex C.22] |
| Diagnostic Maturity judgment | How far the required indicators have been measured | Normative | [Part 2 Annex B.5 Table B.4] |
| Evaluation status | Is the evaluation final or provisional? | Normative | [Part 3 Annex C.20] |
| Decision gate judgment | Did the data pass the decision gate? | Normative | [Part 3 Annex C.21] |
Diagnosis status
| Value | Meaning |
|---|---|
DIAGNOSED | The diagnosis procedure was performed |
SCHEMA_ONLY | There are no records, so only the schema exists |
FILE_BROKEN | The file cannot be opened or its structure cannot be parsed |
For SCHEMA_ONLY and FILE_BROKEN, Diagnostic Maturity and the tier are recorded as null. SCHEMA_ONLY is resolved when the first instance is loaded.
Indicator applicability · normative contract
| Applicability | Meaning | Indicator score | statusFactor | Data provider action |
|---|---|---|---|---|
APPLIED | Measured | Score | 1 | None |
PARTIALLY_APPLIED | Only part of the targets measured | null | coverage | Obtain reference data for the remaining targets |
PRECONDITION_UNMET | Not measured because a precondition (such as reference data) is missing | null | 0 | Measure after obtaining the reference data |
NOT_APPLICABLE | Does not apply to this type or condition | null | Excluded from the calculation | None |
OPTIONAL_SKIPPED | An optional indicator was skipped | null | Excluded from the calculation | None |
The quality index and the tier under an operating guideline use only the APPLIED results of the applicable formally required indicators, so optional indicators are not included even when APPLIED. To judge a tier, all applicable formally required indicators must be APPLIED (Diagnostic Maturity DM-2).
Check result display
| Display | Meaning | Base layer mapping |
|---|---|---|
| Met | Measured or checked, and meets the criterion | APPLIED + criterion met |
| Not met | Measured or checked, but below the criterion | APPLIED + criterion not met |
| Not measured | Applicable but not yet measured | PRECONDITION_UNMET · PARTIALLY_APPLIED |
| Not applicable | Does not apply to the data type or purpose, or an optional indicator was skipped | NOT_APPLICABLE · OPTIONAL_SKIPPED |
| Not judged | The conditions needed for judgment are not met | Recorded together with the reason for not judging |
A score of 0 means “measured and low”, so keep it separate from not measured, not applicable and not judged. “Not judged” also differs from judging and falling short, so record it separately from the lowest tier and from not applicable. OPTIONAL_SKIPPED is displayed as “Not applicable”, with the skipped optional indicator recorded as the reason.
Reasons for not judging
Display format: Not judged: <reason>
| Target | Reason | Meaning | Clause |
|---|---|---|---|
| Quality tier | No operating guideline applied | Scores exist, but no operating guideline has been applied to turn them into a tier | — |
| Quality tier | Below DM-2 | Diagnostic Maturity is not DM-2 | — |
| Purpose tier | PROFILE_NOT_REGISTERED purpose profile not registered | No profile has been registered for that use purpose | [Part 3 Annex C.22] |
| Purpose tier | THRESHOLD_NOT_PUBLISHED thresholds not published | A purpose profile exists, but its thresholds have not been published | [Part 3 Annex C.22] |
| Purpose tier | PRECONDITION_UNMET precondition not met | The conditions of the previous stage are not met | [Part 3 Annex C.22] |
The purpose tier code PRECONDITION_UNMET is the same code as PRECONDITION_UNMET in indicator applicability, but it applies to a different target.
Diagnostic Maturity display
| Decision table result | Display |
|---|---|
DM-2 | DM-2 |
DM-1 | DM-1 |
DM-0 | DM-0 |
null (row 5) | DM-0 not met |
null (row 1) | Not judged (diagnosis status exception) |
Each row of the decision table is in Judgment procedure.
Evaluation status and decision gate judgment
| Kind | Value | Meaning | Clause |
|---|---|---|---|
| Evaluation status | OFFICIAL | Evaluation that applies the OFFICIAL threshold profile of an operating guideline | [Part 3 Annex C.20] |
| Evaluation status | PROVISIONAL | Provisional evaluation (for example, D5-03 (Statistical plausibility) measured without an operating guideline using the example patterns of Part 2 Appendix I) | [Part 3 Annex C.20] |
| Decision gate judgment | PASS | The transition conditions of the decision gate (G1 · G2 · G3) are met | [Part 3 Annex C.21] |
| Decision gate judgment | FAIL | The transition conditions of the decision gate are not met | [Part 3 Annex C.21] |
Decision gates are defined in Part 1 5.2; judgment is covered by Part 2.
Basis: Part 1 5.2 · Part 2 Annex B.1 Table B.1, B.2 Table B.2, B.5 Table B.4 · Part 3 Annex C.20, C.21, C.22
Manifest example
Contents
ContentsThe complete manifest of the example data (20 business registration records). It shows how discovery-layer and understanding-layer properties are recorded in a single JSON-LD document.
Properties read for each judgment
With a single manifest, an agent starts the four judgments.
| Judgment | Properties read in this manifest |
|---|---|
| Fitness | dct:description · csvw:tableSchema · dct:type |
| Reliability | aird:lifecycleStatus · dct:accrualPeriodicity · spdx:checksum |
| Joinability | dct:identifier · csvw:tableSchema |
| Usability | dct:license · dct:rights · dct:accessRights |
Discovery layer — a manifest that has completed stage 1
This reproduces the sample entry from the example file (meta.json), with only the identifiers replaced by this site’s example identifiers. All 23 required discovery-layer metadata elements and the column schema (csvw:tableSchema) are filled in, and the checksum is the actual SHA-256 of example.csv.
Simplified notation and prefix declaration
This example uses a simplified notation that merges the manifest and the dataset into one node. The standard gives the dataset (the resource) and the manifest (the description document) separate identifiers; the separated structure appears in the manifest excerpt in Packaging and distribution — files needed for each readiness state.
The column descriptions use dc:description on the assumption that an external context declares the dc prefix; the local context of this document does not contain that declaration.
{
  "@context": [
    "https://datahub.kr/ns/aird-context-3.0.jsonld",
    {
      "dct": "http://purl.org/dc/terms/",
      "dcat": "http://www.w3.org/ns/dcat#",
      "aird": "http://vocab.datahub.kr/def/aird/",
      "aird-ml": "http://vocab.datahub.kr/def/aird-ml/",
      "aird-kg": "http://vocab.datahub.kr/def/aird-kg/",
      "csvw": "http://www.w3.org/ns/csvw#",
      "dqv": "http://www.w3.org/ns/dqv#",
      "prov": "http://www.w3.org/ns/prov#",
      "spdx": "http://spdx.org/rdf/terms#",
      "adms": "http://www.w3.org/ns/adms#",
      "vcard": "http://www.w3.org/2006/vcard/ns#",
      "rai": "http://mlcommons.org/croissant/RAI/",
      "dpv": "https://w3id.org/dpv#",
      "cr": "http://mlcommons.org/croissant/",
      "sc": "https://schema.org/",
      "void": "http://rdfs.org/ns/void#",
      "dcatkr": "http://vocab.datahub.kr/def/dcat-ap-kr/",
      "foaf": "http://xmlns.com/foaf/0.1/"
    }
  ],
  "@id": "https://data.example.go.kr/id/dataset/biz-registry/manifest/1.0.0",
  "@type": "dcat:Dataset",
  "aird:lifecycleStatus": "http://vocab.datahub.kr/def/aird/lifecycle-status/Discoverable",
  "dct:identifier": "https://data.example.go.kr/id/dataset/biz-registry",
  "dct:title": "예시 사업장 등록 정보",
  "dct:description": "지역별 사업장의 등록 정보와 영업 상태를 수록한 예시 데이터셋이다. 이 표준의 적용 절차를 보이기 위하여 작성하였다.",
  "dcat:keyword": [
    "사업장",
    "산업분류",
    "지역",
    "영업상태"
  ],
  "dct:type": [
    "http://vocab.datahub.kr/def/dcat-ap-kr/service-type/FILE",
    "http://vocab.datahub.kr/def/aird/dataset-type/Structured"
  ],
  "dct:language": [
    "http://publications.europa.eu/resource/authority/language/KOR"
  ],
  "csvw:tableSchema": {
    "columns": [
      {
        "name": "bizId",
        "datatype": "string",
        "dc:description": "사업장 고유 등록번호. B-YYYY-NNNN 형식",
        "required": true
      },
      {
        "name": "bizName",
        "datatype": "string",
        "dc:description": "사업장 명칭"
      },
      {
        "name": "industryCode",
        "datatype": "string",
        "dc:description": "한국표준산업분류 세세분류 코드"
      },
      {
        "name": "regionCode",
        "datatype": "string",
        "dc:description": "행정표준코드 법정동 시군구 코드"
      },
      {
        "name": "employeeCount",
        "datatype": "integer",
        "dc:description": "상시 종업원 수. 0 이상 100000 이하"
      },
      {
        "name": "revenueBand",
        "datatype": "string",
        "dc:description": "매출 구간 코드. B1부터 B4까지"
      },
      {
        "name": "registeredOn",
        "datatype": "date",
        "dc:description": "최초 등록일. ISO 8601-1 날짜"
      },
      {
        "name": "closedFlag",
        "datatype": "integer",
        "dc:description": "폐업 여부. 0은 영업, 1은 폐업"
      }
    ],
    "primaryKey": "bizId"
  },
  "dct:creator": [
    "https://data.example.go.kr/org/example-agency"
  ],
  "dct:publisher": "https://data.example.go.kr/org/example-agency",
  "dcat:contactPoint": {
    "@type": "vcard:Contact",
    "vcard:fn": "예시기관 데이터관리팀",
    "vcard:hasEmail": "mailto:data@example.go.kr"
  },
  "aird:creationMethod": "http://vocab.datahub.kr/def/aird/creation-method/collected",
  "dct:accrualPeriodicity": "http://publications.europa.eu/resource/authority/frequency/ANNUAL",
  "dct:license": "http://vocab.datahub.kr/def/dcat-ap-kr/license/KOGL-1",
  "dct:rights": "공공누리 제1유형. 출처를 표시하면 상업적 이용과 변형을 허용한다.",
  "dct:accessRights": "http://publications.europa.eu/resource/authority/access-right/PUBLIC",
  "dcat:distribution": [
    {
      "@type": "dcat:Distribution",
      "dcat:accessURL": "https://data.example.go.kr/aird/example-registry/data/example.csv",
      "dcat:mediaType": "text/csv",
      "dct:format": "http://publications.europa.eu/resource/authority/file-type/CSV",
      "spdx:checksum": {
        "spdx:algorithm": "SHA-256",
        "spdx:checksumValue": "7ad8add25d7a638322dd869f08b2fc7d64a4b12a3755c58ca9a10ee8646d78ea"
      }
    }
  ],
  "dcat:theme": [
    "http://vocab.datahub.kr/def/dcat-ap-kr/data-theme/INDUSTRY_EMPLOYMENT"
  ],
  "dcat:landingPage": "https://data.example.go.kr/dataset/biz-registry",
  "dcatkr:maintainer": {
    "@type": "foaf:Agent",
    "foaf:name": "예시기관 데이터관리팀"
  }
}
Understanding layer — what stage 2 adds Example
This example records the measurement results for the same data. No operating guideline was applied, so the quality tier (aird:qualityTier) and the threshold profile (judgment reference values, aird:thresholdProfile) are empty, which is a normal result. An agent interprets the empty values not as a score of 0 but as “Not judged: no operating guideline applied”.
D5-03 (Statistical plausibility) was measured provisionally with the example patterns in Part 2 Appendix I. Only 7 of the 13 formally required indicators were measured, so the Diagnostic Maturity (DM) is DM-0 (provisional).
Property names and dimension scores
The procedure that determines Diagnostic Maturity is described in Judgment procedure. Property names will follow the standard schema once it is published.
The dimension scores (aird:completenessScore and so on) are a shortened notation for readability. AIRD vocabulary v0.10.5 records dimension scores as quality measurements (dqv:QualityMeasurement, 2.3.1 — one each for D1–D7).
{
  "@id": "https://data.example.go.kr/id/dataset/biz-registry/manifest/1.1.0",
  "dcat:previousVersion": "https://data.example.go.kr/id/dataset/biz-registry/manifest/1.0.0",
  "aird:lifecycleStatus": "http://vocab.datahub.kr/def/aird/lifecycle-status/Discoverable",
  "aird:dataType": "STRUCT",
  "dqv:computedOn": "https://data.example.go.kr/id/dataset/biz-registry",
  "prov:generatedAtTime": "2026-10-05",
  "aird:completenessScore": 1.0,
  "aird:validityScore": 1.0,
  "aird:uniquenessScore": 1.0,
  "aird:machineReadabilityScore": 1.0,
  "aird:diagnosticMaturity": "DM-0",
  "aird:qualityTier": null,
  "aird:thresholdProfile": null,
  "aird:diagnosticReport": {
    "@id": "https://data.example.go.kr/id/dataset/biz-registry/report/2026-10-05",
    "spdx:checksum": {
      "spdx:algorithm": "SHA-256",
      "spdx:checksumValue": "(SHA-256 of the diagnostic report file)"
    }
  },
  "rai:dataLimitations": [
    "폐업 신고 지연으로 closedFlag의 반영 시점이 실제 폐업 시점보다 늦을 수 있다"
  ]
}
One verified fact Example Proposed
This example records one fact confirmed by diagnosis as one measurement, following the DQV vocabulary that the standard already uses. aird:targetColumn · aird:referenceStandard · aird:validUntil are proposed properties.
{
  "@type": "dqv:QualityMeasurement",
  "dqv:isMeasurementOf": "aird:D2-02",
  "dqv:computedOn": "https://data.example.go.kr/id/dataset/biz-registry",
  "prov:generatedAtTime": "2026-10-05",
  "dqv:value": 0.997,
  "aird:targetColumn": "regionCode",
  "aird:referenceStandard": "행정표준코드 법정동 (버전 명시)",
  "aird:validUntil": "2027-01-05"
}
The whole pack as one RDF graph
Merging the pack’s JSON-LD files into a single RDF graph (manifest · column schema · operation file · decision gate judgments) reveals the references that cross file boundaries. The contents of each file are described in Packaging and distribution — files needed for each readiness state.
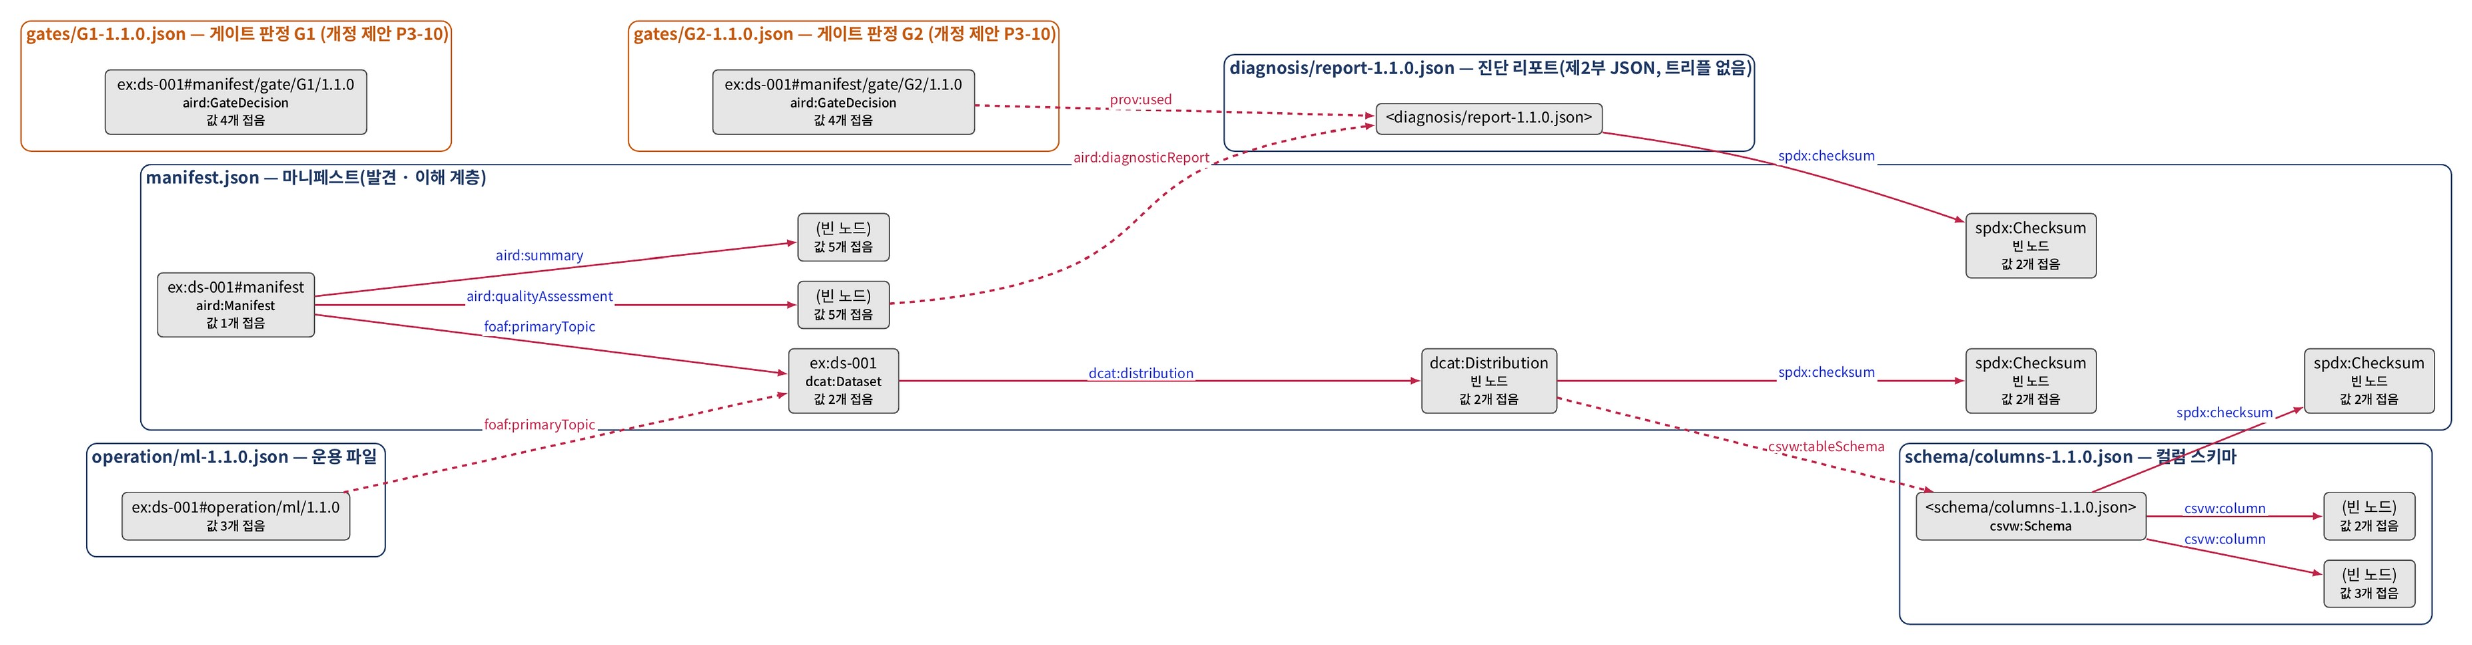
How to read it is in Fields and handling by judgment and the property list in Metadata elements.
Basis: Part 2 Appendix I · AIRD vocabulary v0.10.5 2.3.1
Public tools
Contents
ContentsOf the tools that apply the AI-Ready Data draft standard, two can be downloaded or connected to from public repositories today: Public Data Lens (an MCP server) and the catalog converter. The status of tools still in development is in Current status and release plan.
Public Data Lens (public-data-lens)
Public Data Lens is an MCP server that applies the draft standard to the catalog metadata of the Korea Public Data Portal (data.go.kr). When an agent queries with a use purpose, the server searches for relevant data and returns, with the grounds for each judgment, its judgment of the completeness and timeliness of the catalog metadata and its catalog-level measurement of the minimum measurement indicators (MMI). These judgments are not quality measurements or tier judgments of the data itself.
| Item | Details |
|---|---|
| Kind | MCP server |
| Main users | Agent and AI developers (data users) |
| Status | Beta (v1.1) |
| Features | Search · single-record lookup · comparison · monthly change tracking · catalog statistics · column structure of file data · observation of sample values · drafting a data-use plan |
| Judgment and interpretation | Judgment: performed by the server under versioned rules (reproducible) · Purpose-specific interpretation: performed by the agent |
| Data | Monthly snapshot of the full Korea Public Data Portal catalog (the observations in Why it is needed cover only the file data catalog) — 96,110 entries in the 2026-07 snapshot (checked 2026-10-05) |
| Limitations | Based on catalog metadata. No guarantee of the content, quality or joinability of the actual data |
| Repository | github.com/hike-lab/public-data-lens · MIT |
| Related pages | Fields and handling by judgment · Metadata elements |
Catalog converter (aird-tools · catalog-converter)
The catalog converter is the tool currently usable from aird-tools, the collection of implementation tools released during development of the standard. It converts catalog metadata into the metadata format of the standard.
| Item | Details |
|---|---|
| Kind | Conversion tool |
| Main users | Data providers |
| Status | v0.1 |
| Features | Catalog metadata conversion |
| Judgment and interpretation | No judgment (format conversion only). Usage and input formats are described in the repository |
| Limitations | Early version. The manifest validator, quality evaluator and conversion pipeline are under review (Current status and release plan) |
| Repository | github.com/hike-lab/aird-tools · MIT |
| Related pages | Metadata elements |
Tool information was checked on 2026-10-05.
FAQ
Contents
ContentsAnswers to frequently asked questions about whether the standard is mandatory, the scope of work, checksums and tier judgment. The standard is not mandatory, stage 1 can start without tools, and quality tiers are judged only under an operating guideline.
- Is it mandatory?
- It is not an obligation under laws or regulations. Organizations and companies can cite this standard as a related standard in their data management guidelines, project requirements or contract terms. Completing stage 1 alone already reduces the number of items an agent must guess.
- What do we gain?
- Agents and users can judge, without contacting the data provider, whether the data fits the purpose, whether it can be trusted, whether it can be joined with other data, and under what conditions it may be used. The manifest also records the grounds on which an agent selects the data as a search result or a join candidate.
- How far do we need to go?
- Stage 1 alone establishes the discovery layer, so users and agents can find the data and decide whether to use it. Setting priorities in this order is recommended: data with use requests → data used in joins with other data → all other data.
- Do we have to fix the data?
- Stage 1 records descriptions without changing data values. Values are corrected in stage 2, fixing defects; keep the original and create a separate cleaned version.
- How long does it take?
- The time required depends on how complete the existing registration information and column descriptions are. The catalog converter among the public tools can convert some items of existing listing metadata, so only the items missing from the registration information are entered by hand.
- Who calculates the checksum?
- The data provider calculates the file’s SHA-256 checksum with a common tool such as sha256sum. When a diagnostic tool is used, the diagnostic tool calculates it.
- Do we have to change our systems?
- First use the existing registration system and its export functions. If the existing system does not support entering required properties, version management, checksum generation or publishing the manifest, add the missing functions.
- Can we do it without tools?
- Stage 1 can be done by hand; indicator measurement in stage 2 is performed by a diagnostic tool. The release plan for the diagnostic tool is in Current status and release plan, and how to read the report is in Measuring quality and the diagnostic report — reading the report.
- What if the data contains personal information?
- Do not decide alone; check together with the department responsible for personal information protection. The checking procedure is in Checking your data.
- Do we have to redo data we have already published?
- You do not start over; keep the existing persistent identifiers and fill in the missing descriptions. Check the column schema and the license statement first.
- Can we get a tier now?
- Tiers are judged by applying an operating guideline and require Diagnostic Maturity (DM) DM-2. The operating guideline provided by the standard will be published when the standard is established (expected December 2026). An organization can build and publish its own operating guideline and judge tiers with it; a tier is recorded together with the identifier and version of the operating guideline applied. Results without an operating guideline applied receive no tier (Not judged: no operating guideline applied). How to build an operating guideline is in Building an operating guideline.
- What if a user reports a problem?
- Review the report, take the necessary action (cleaning, correcting the description or updating), and record the result.
- What are the results used for?
- Measurement results are used in four ways:
- Judgments by people looking for data
- Automated use by AI agents
- Internal priorities for data improvement
- Evidence for reviewing the threshold profile (judgment reference values) of an operating guideline
- Is there a penalty for recording something wrong?
- The standard does not define penalties for recording errors. Inaccurate records, however, are a bigger problem than low scores. Recording an unmeasured item as measured, or omitting a limitation, leads users and agents to misjudge the data, so record anything you could not confirm as “unconfirmed” or “not measured”.
- What is the status of Parts 4 and 5?
- Part 4 “Transformation Pipeline and Governance” and Part 5 “Discovery, Exchange and Use” are not included in the December 2026 enactment scope (Parts 1–3); they are follow-on parts expected to be enacted in 2027. This site marks such citations with a “follow-on” label.
About this site
Contents
ContentsThis is a public site that explains Parts 1–3 of the TTA (Telecommunications Technology Association) “AI-Ready Data” standard (TTAK draft, v0.95) and describes the structure and schedule of the follow-on parts (Parts 4 · 5). It is run by the HIKE Lab, Chung-Ang University. Requirements are defined by the specification, which prevails where the explanation differs.
Four components of the site
The site explains the requirements and judgment methods of the standard and provides application guides, tools and observational evidence. Its content is organized in four layers: the standard, explanation and guides, tools, and evidence.
Contents and location of each layer
| Layer | Contents | Location on the site |
|---|---|---|
| Standard | Requirements and the tier system. Normative documents. Judgment criteria are set by the operating guideline, a document separate from the standard | Clause markers · What the standard does · Building an operating guideline |
| Explanation · guides | Background of the requirements and application procedures. Does not create new requirements | At a glance · Preparing data · For agents · Concepts and judgment menus · Recommended marker |
| Tools | Public tools (MCP server · conversion tools) · how to read the diagnostic report | Public tools · Reading the diagnostic report |
| Evidence | Observations · run logs · experiments. Methods and limitations are stated with them | Measured · run log · illustrative example markers |
Site menus
The site has six menus: About the standard, Preparing data, For agents, Operating guidelines, Concepts and judgment, and Reference.
Publication information
| Item | Details |
|---|---|
| Operator | HIKE Lab, Chung-Ang University |
| Standard | AI-Ready Data draft standard (Parts 1–3) · standard number not yet assigned |
| Establishment scope | The December 2026 establishment scope is Parts 1–3. Parts 4 · 5 are follow-on parts expected to be enacted in 2027. |
| Vocabulary | AIRD vocabulary v0.10.5 (reference vocabulary) |
| Content license | CC BY 4.0 |
| Public address | https://aird.datahub.kr |
| Error reports | hike.cau@gmail.com |
Status of the site
The content of this site is not an obligation under laws or regulations, and the site does not create new requirements. The governing standard is the TTA “AI-Ready Data” Parts 1–3 draft standard. The follow-on parts (Parts 4 · 5) are expected to be enacted in 2027; this site describes only their structure and schedule. The explanations apply equally to data from public institutions, companies and non-profit organizations. If requirements or identifiers change in the established standard, this site is updated accordingly. This English version is an unofficial explanatory translation of the Korean site.
Scope of the site
The site presents the items to check and record, with the evidence and judgment criteria for each, and explains error cases, correction cases and how to interpret the diagnostic report. Imposing new obligations, deciding judgment criteria (decided by the guideline publisher), evaluating specific organizations or datasets, ranking organizations, and receiving files to diagnose them (a distributable version of the diagnostic tool is in development) are out of scope.
How the standard was created is in Origins and progress.
Usage statistics
This site uses Google Analytics 4 to understand how it is used and to improve its content. It does not collect information that identifies a person, search terms, or values entered or selected in widgets. Nothing is collected if you use your browser’s tracking protection or the Google Analytics opt-out browser add-on, and opting out does not affect use of the site.
Data collected and retention
| Item | Details |
|---|---|
| Collected | Address and title of pages visited · time on page · scrolling · outbound links · file downloads · video plays · whether widgets and search are used · referral source · approximate location (country · city) · browser and device type |
| Not collected | Information that identifies a person, such as name or email · search terms · values entered or selected in widgets. Google Analytics 4 does not store IP addresses. |
| Features not used | Google signals · ads personalization · linking to advertising accounts |
| Retention | Event data: 2 months |
| Opting out | Use your browser’s tracking protection or the Google Analytics opt-out browser add-on. Opting out does not affect use of the site. |
Media kit
Descriptions, key facts and figures that can be quoted as is in articles, talks and reports. License: CC BY 4.0. Credit: “AI-Ready Data Explained (aird.datahub.kr), HIKE Lab, Chung-Ang University”.
One sentence
The AI-Ready Data (AIRD) draft standard specifies how to record facts about data in a machine-readable form and how to judge its readiness, so that AI agents judge data without guessing.
Three sentences
The AI-Ready Data (AIRD) draft standard specifies how to record facts about data in a machine-readable form and how to judge its readiness, so that AI agents judge data without guessing. Data providers distribute a manifest with their data files and measure quality with 16 indicators in 7 dimensions, recorded in a diagnostic report. Data is judged Discoverable, Quality-Ready or Purpose-Ready; of these, AI-ready data is data in the Quality-Ready or Purpose-Ready state that meets the common readiness requirements for AI use.
One paragraph
AI agents guess units, as-of dates and conditions of use that are not written down, and act on wrong conclusions without raising errors. The AI-Ready Data (AIRD) draft standard addresses this. It specifies four activities: recording facts about data, measuring quality, judging readiness, and using data on that basis. Data values are not changed; a manifest and a diagnostic report are distributed with the data, and thresholds are set by an operating guideline separate from the standard. The same procedure applies to data from public agencies, companies and non-profits, and it is not a legal obligation. Parts 1–5 were proposed to TTA on 2026-05-13 and are under review; of these, Parts 1–3 are expected to be established in December 2026 and Parts 4 · 5 in 2027. The explanatory site is run by HIKE Lab, Chung-Ang University.
Key facts
| Item | Detail |
|---|---|
| Standard | TTA “AI-Ready Data” Parts 1–3, TTAK draft (v0.95) · Parts 4 · 5 are follow-on parts (expected to be enacted in 2027) |
| Schedule | Drafting began 2026-03-09 · proposed to TTA 2026-05-13 · establishment expected December 2026 |
| Four judgments | Fitness · reliability · joinability · usability |
| Four activities | Record · measure · judge · use |
| Readiness states | Discoverable → Quality-Ready → Purpose-Ready (AI-ready data is Quality-Ready or Purpose-Ready) · Stale |
| Measurement | 16 quality indicators in 7 dimensions |
| Metadata elements | 23 required discovery-layer elements (AIRD vocabulary v0.10.5, demo profile) |
| Scope | 5 data types (tabular, time series, text, image, instruction–response pairs) · 6 use purposes |
| Applies to | Public-sector, enterprise and non-profit data — Where it applies |
Figures
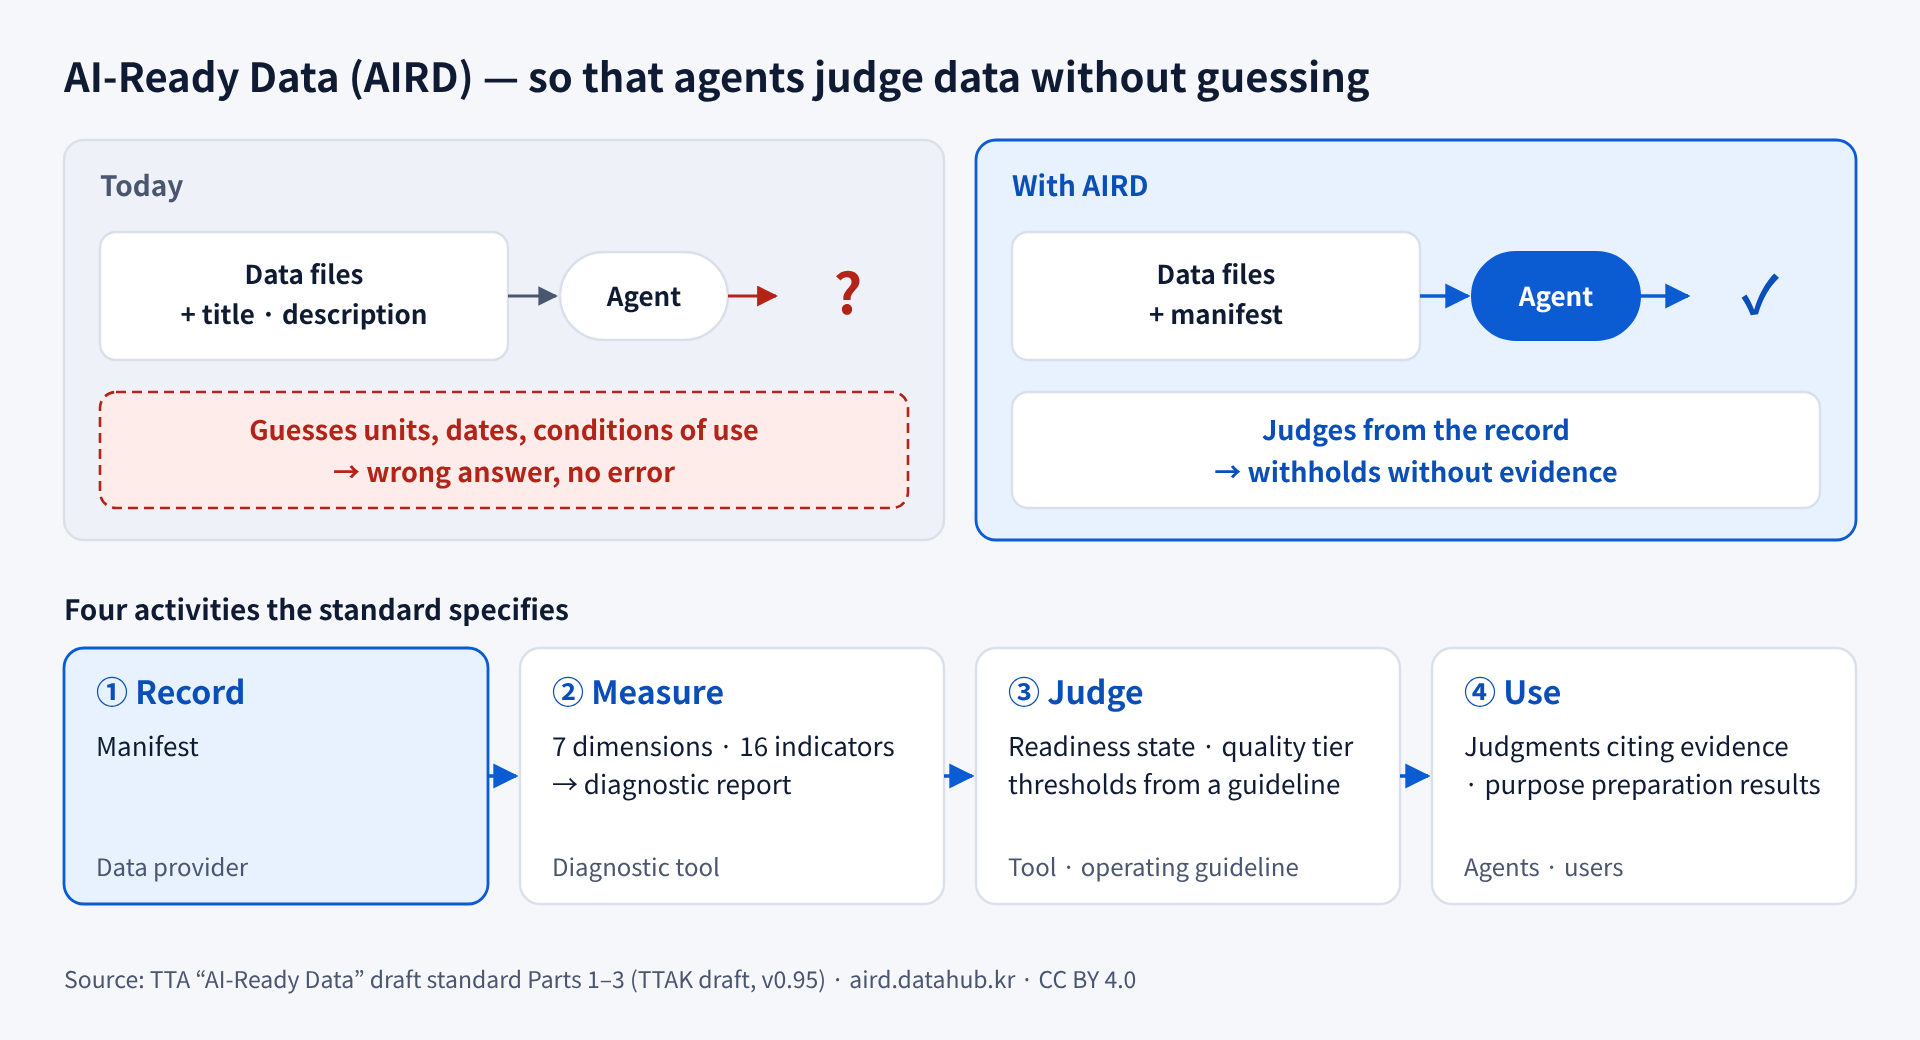
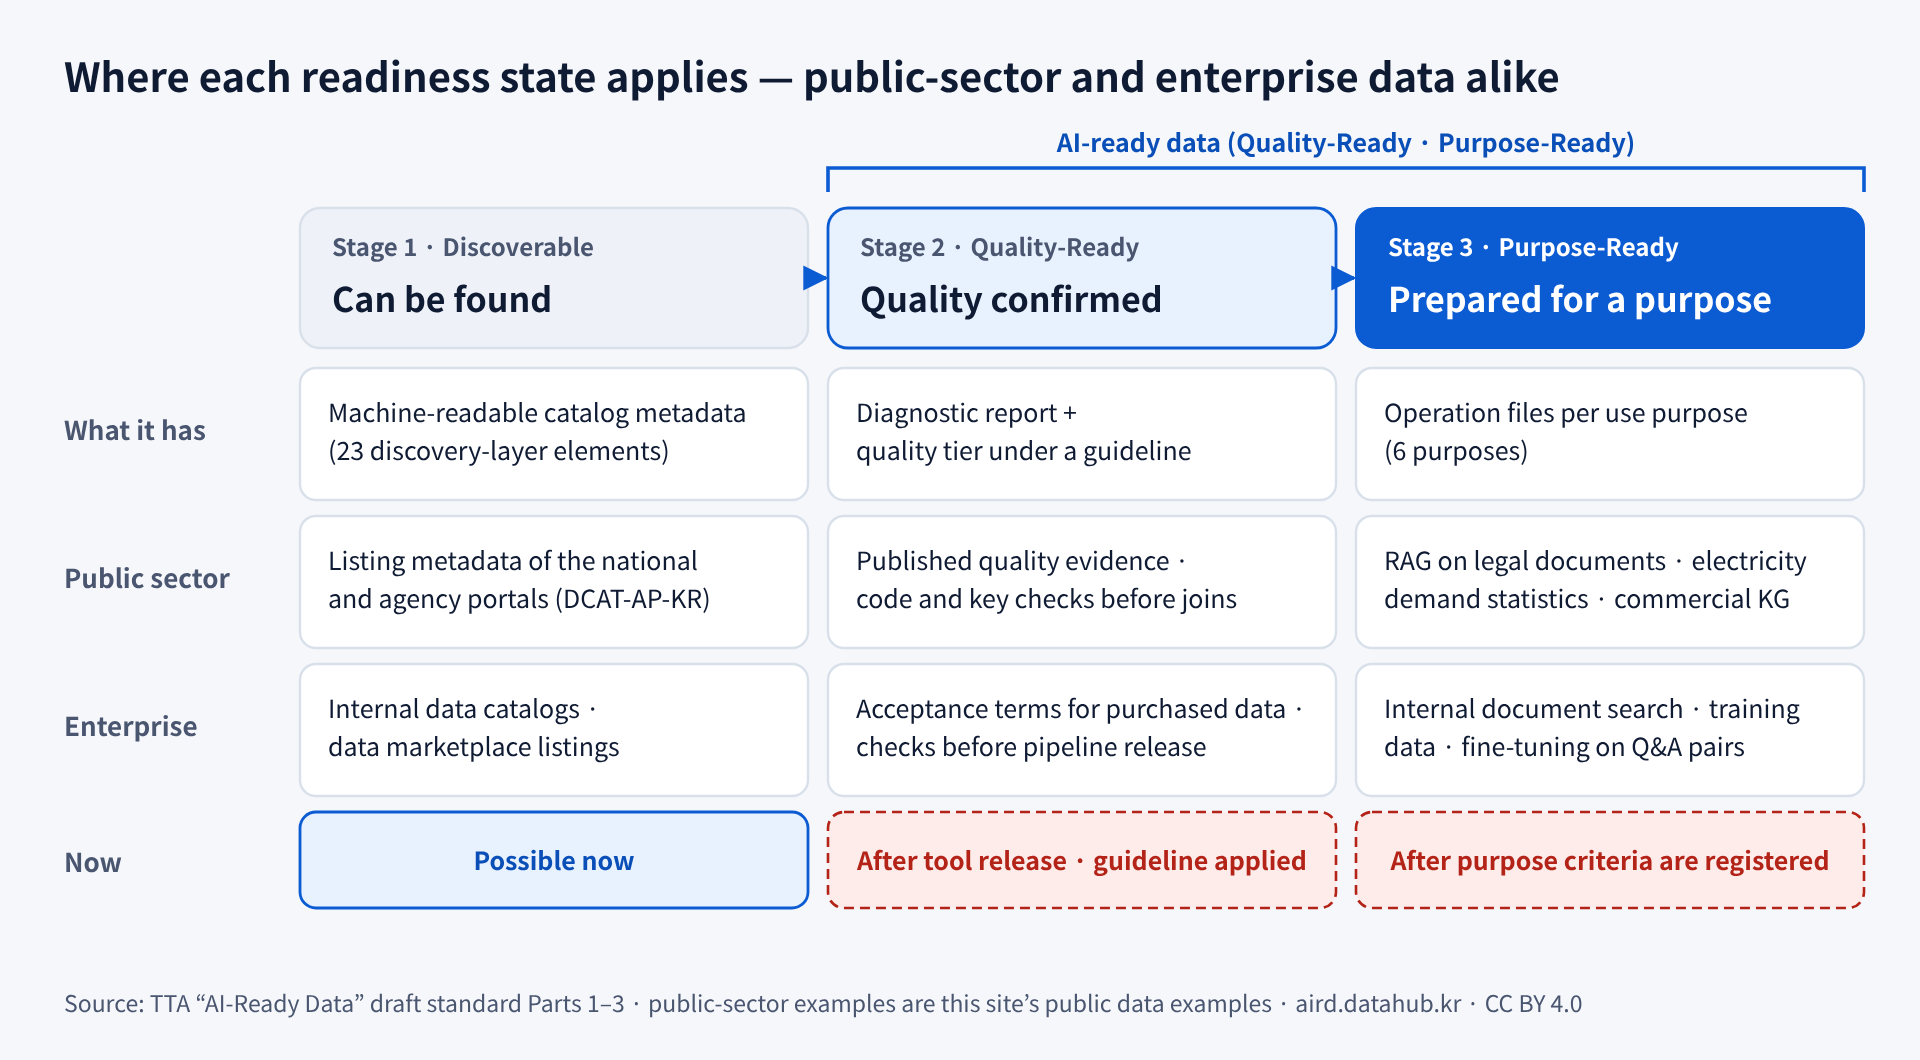
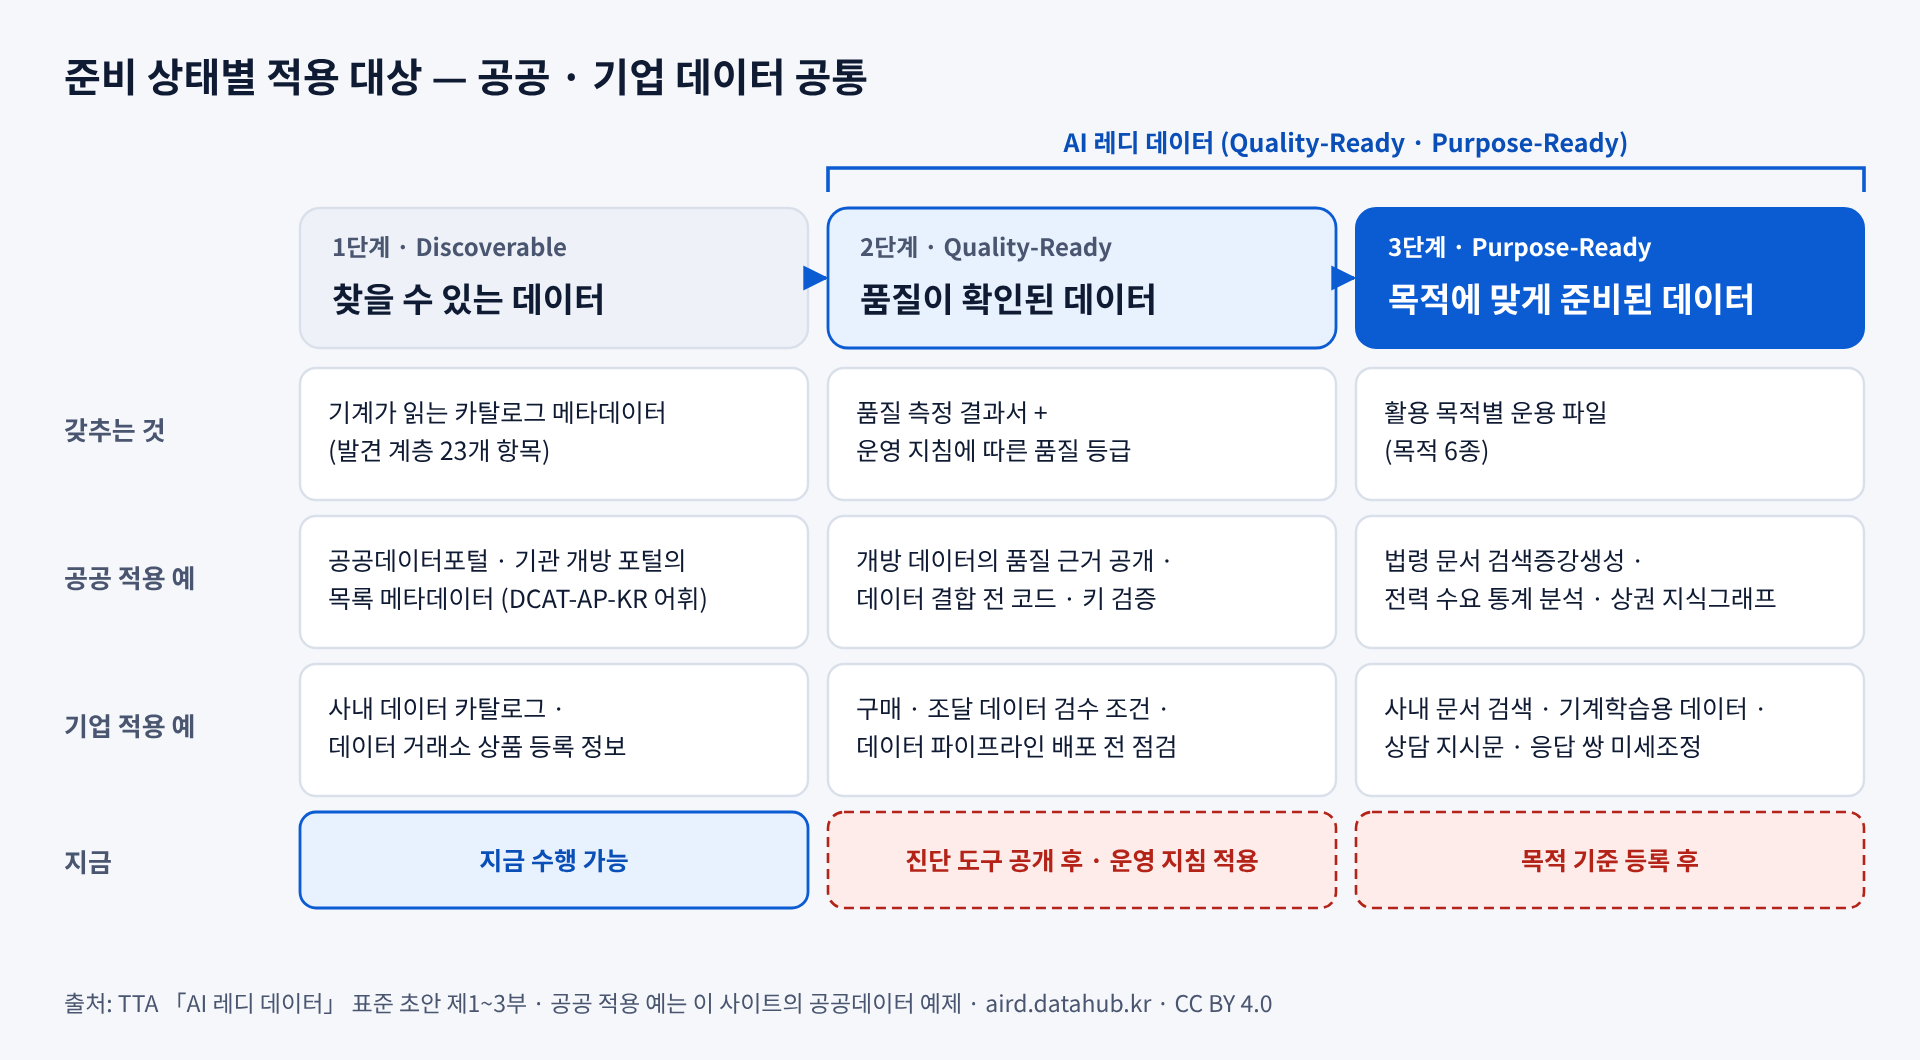
Wording guide
| Preferred wording | Wording to avoid | Reason |
|---|---|---|
| AI-Ready Data (AIRD) | AI-prepared data · data for AI | Name of the standard |
| Draft standard · establishment expected December 2026 | National standard · established standard | Under review |
| Quality tier judged under an operating guideline | AIRD certified · AIRD rating obtained | The standard-provided operating guideline is published at establishment · certification is outside the scope of the standard |
| Values computed by the measurement engine (experimental) | Improves accuracy | The effect on real agents has not been measured |
| Cited and used by organizations | Mandatory | Not a legal obligation |